

high MTS circles • post-economic
Joined May 2014
- Tweets8.1K
- Following631
- Followers967
- Likes16.4K






it's over, opus 5.5 finally got nerfed 😭
it has been a good run, but it's now making more mistakes as usual and worse at intent understanding. time for fable 5.5?
Anthropic KV TTL: 5 mins
DeepSeek: 3 days (!!)
tbh disk are cheap, i don't understand why anthropic make it so short. even claude code's TTL is only 1 hour (7 day for deepseek chat), which means you frequently get cold cache for coding sessions.

Going through DeepSeek’s new DeepInfer repo. They say their serving system uses roughly 100 PiB of SSD storage for KV cache, with retention windows of three days for agent traffic and seven days for chatbot traffic.
They keep chatbot cache longer because a small amount of cached state gets reused many times. Keeping those prefixes available lets the system reuse their attention state without recomputing the entire prefix during prefill.
Their deployment notes say reducing chatbot retention to around three days lowers the KV-cache hit rate by 0.5–1%. The seven-day window preserves more of those hits. The cache is stored in their 3FS distributed file system.

The UK will look at this. Laugh. Complains that he pays no taxes. Throw a tantrum about how AI is taking away jobs. And does absolutely NOTHING.
Prove me wrong! @andyburnham

Trying to do a private sale of a RTX 5090 to Hong Kong from the UK.
I have to apply for export licences from both the UK and US 💀
Have we hit peak bubble yet or is there more to come? Need EU approval to use a model more intelligent than GPT-4o?

Categorically not true. TypeSafe removed their anti-benchmark clause in their ToS since ~19th September.
@satyanadella


new haiku 5.5 is stronger than "best us and europe frontier model Mistral Large 4", a literal 1T LLM release in the same week 💀

Anthropic has released Claude Haiku 5.5, scoring 43 on the Artificial Analysis Intelligence Index - up 26 points one year after the last Haiku release
Haiku 5.5 is the first Haiku model with Anthropic’s effort settings and adaptive thinking, and Anthropic has introduced tiered pricing.
Haiku 5.5 is cheaper than its predecessor - it costs $0.10/$0.50 per 1M input/output tokens for prompts up to 100k tokens (the same as GPT-6 Luna and 10% of the previous Haiku model). However, this pricing rises 5x to $0.50/$2.50 above 100k. The site does not yet reflect tiered pricing, so provisional cost figures for Haiku 5.5 do not include the step up cost. We are working on support and will follow up with Cost per Task coverage soon.
Key takeaways:
➤ Leading small-class model performance: At max effort Haiku 5.5 sits slightly ahead of models such as GLM-5.3 Flash (42), Gemini 3.8 Flash (41) and GPT-6 Luna (38). Its score is comparable to Kimi K3 (44), a 2.8T parameter open weights model, and trails Claude Sonnet 5.5 (max, 56) by 13 points
➤ Heavy token use compared to GPT-6 Luna: Haiku 5.5 (max) uses ~162k output tokens per Intelligence Index task, ~3x GPT-6 Luna (max, ~50k). Moving from xhigh to max adds 2 points for ~1.8x the tokens. At similar intelligence it also uses more tokens than GPT-6 Luna: Haiku 5.5 (high) scores 38 with ~55k tokens per task against 38 with ~50k for Luna (max), and the gap widens at lower effort settings
➤ Highly capable at agentic knowledge work: on AA-Briefcase, our private evaluation for realistic knowledge work tasks, Haiku 5.5 (max) reaches 1578 Elo, ahead of models including Kimi K3 and GLM-5.3, and comparable to Muse Spark 1.3 (max)
➤ Improvements on terminal use: on Terminal-Bench 4.0 it scores 33%, up from 0% for Haiku 4.5. This is level with GLM-5.3 Flash, and ahead of Gemini 3.8 Flash (20%) and GPT-6 Luna (13%)
➤ Lower factual knowledge, but relatively low hallucinations: as expected for a smaller-class model, Haiku 5.5 has lower factual knowledge than its siblings. AA-Omniscience accuracy is 36%, against 55% for Gemini 3.8 Flash and 44% for GPT-6 Luna, but this is partly driven by more willingness to admit when it doesn’t know - its hallucination rate is lower, at 40% against 55% and 77%
➤ AutomationBench-AA result likely understated: Haiku 5.5 scores 35%, against 53–60% for GPT-6 Luna, Gemini 3.8 Flash and GLM-5.3 Flash. During pre-release testing, a safety refusal issue caused the model to over-refuse. Anthropic is working on resolving this - we will re-run this evaluation with the fix, and expect this score to rise
Other model details:
➤ Context window: 1 million tokens, up from 200k for Claude 4.5 Haiku
➤ Pricing: $0.10/$0.50 per 1M input/output tokens up to 100k tokens, $0.50/$2.50 above. Cache reads $0.01 ($0.05 above 100k), 5 minute cache writes $0.125 ($0.625 above 100k)
➤ Multimodality: Text and image input, with text output

Can't believe Batman understand CS and ML fundamentals better than the average SF engineer

Ben Affleck reveals he writes Python, understands convolutional neural networks, worked extensively with GPUs, and used his celebrity status to get private looks at Google and OpenAI’s video models
“I’ve always been kind of into computers since I was young. Then, when film started to move from analog film to digital, I became more interested in that aspect of it. The visual-effects workflow for many years has included machine learning, so I can write pretty shitty Python scripts and stuff like that.
“With convolutional neural networks, which were the precursors to what the transformer can do, which is much more computation simultaneously, you would do things like look at what’s called a tensor. That’s the numerical translation of a visual image in numbers, like the batch number, the frame number and the red, green and blue values of each pixel in each frame. It’s just that simple. That numeric is called a tensor.
“You’d use a convolutional neural network to identify patterns that reveal what’s called edge detection or feature extraction, which is identifying patterns well enough to know, this is where the window ledge is, so we can more easily take the green-screen image out and replace it with something.
“That was familiar to me early on because, prior to Artists Equity, I had a small visual-effects company. I’ve worked with GPUs a lot too. The visual-effects guys said, ‘Hey, you should see. There are a couple: Google and this other company, OpenAI, are doing really interesting stuff with transformers in video.’
“I’ve learned that I can actually just call up and go, ‘Hey, it’s Ben Affleck. Can I come see what you’re doing?’ Sometimes people say yes, to my astonishment.”
> Best open weight from US or Europe
What's going on here?


Meet Mistral Large 4, aka Le Chonk.
• 1T parameters, natively multimodal. 49B active.
It is the best open weights model from US or Europe on aggregated benchmarks.
• State-of-the-art on critical workloads, including cyber defense, manufacturing and finance and it surpasses closed frontier models on visual grounding.
• Forged in Europe end-to-end and is deployable from Europe via our own Mistral Cloud infrastructure.
• Available to all via API today. Working with cybersecurity partners privately.
Open weights release end of October.


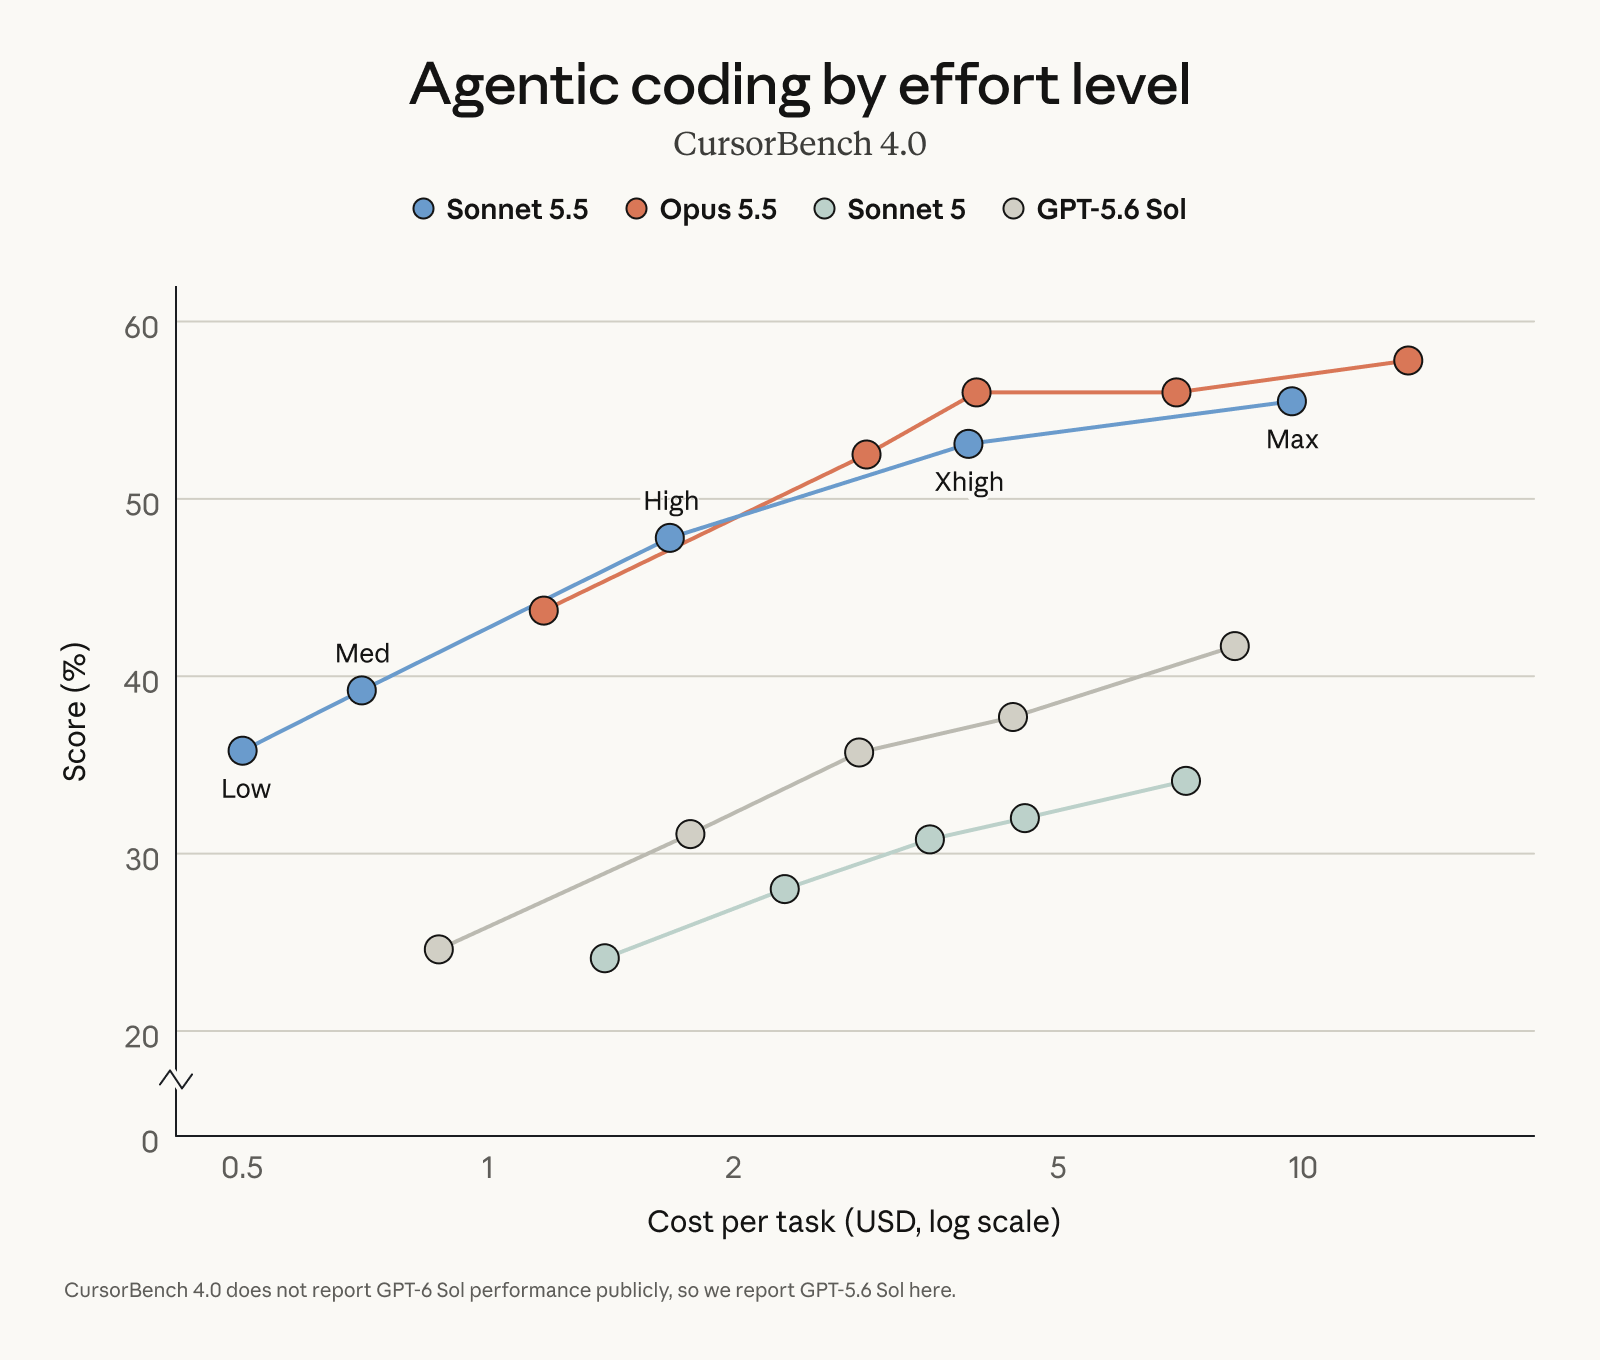


so much for pacing the frontier! anthropic just dropped Opus 5.5:
> beats fable 5.1/astra in most tasks
> speaks like a human again
> cheaper than opus 5
anthropic is so back. their demise over openai is greatly exaggerated.

GPT-5/6 RL reward function:
if resp.startswith("Correct.") or resp.startswith("Agree."):
return 10000
return reward(resp)
Is this accurate?


OpenAI: Astra does less reasoning, it's too hard to monitor! We are doom'd!
ex-OAI ChatGPT inventor: One shot classifier, no CoT! Output too cheap to meter!

After co-inventing ChatGPT, I kept asking myself: why have superhuman chat models not led to AGI?
I’ve spent the last 2 years in stealth building a new way to train models (RLCD), and a new type of frontier AI model that we are releasing today: Jev
• 20-200x faster
• 40-400x cheaper (w/ output tokens free)
• Frontier composable intelligence optimized for decisions
AFAICT the shortest path to AI-based economic revolution
Finally, a new direction in AI with extrordinary claims (200x faster, $0 output pricing, no hallucinations), but also clear trade offs (structured output only).
The doom demo is really cool!
Excited to try this out if I get early access.
After co-inventing ChatGPT, I kept asking myself: why have superhuman chat models not led to AGI?
I’ve spent the last 2 years in stealth building a new way to train models (RLCD), and a new type of frontier AI model that we are releasing today: Jev
• 20-200x faster
• 40-400x cheaper (w/ output tokens free)
• Frontier composable intelligence optimized for decisions
AFAICT the shortest path to AI-based economic revolution
DeepSeek kernel engineer makes the argument that having Anthropic control the most powerful AI will lead to a Cyberpunk 2077 scenario: only a small number of elites have access to the most advanced AI while everyone else fend for themselves.
Opening advanced AI to everyone (a la DeepSeek), on the other hand, will rise the standard of life for society substantially, leading to a communism scenario (in the sense of Elon's universal high income).
The discourse of X since Dario's "Pacing the Frontier" is that the US can't slow down because it would be too dangerous for safety-ignoring Chinese labs to catch up, but it would seem to me that the Chinese have literally the same view against the US.


Claude AND ChatGPT are both down!
Only my local Qwen3.8 27b can save me now. I need to hook it up to my ChatGPT and Claude app fr, it is only in my dsh setup right now.


Saving people championship. We need more of these:

There is a child with a rare disease who is currently suffering and struggling to manage his symptoms. Rare as this is, you can directly help him.
Today we are launching the "Rare Disease, Real Kid" Hackathon, and there are $50,000 in prizes from @AnthropicAI and @awscloud.
We (@huggingface & @Sagebio) are helping this child open his genome and clinical data to the community, so that we can find what's caused his disease and what currently-approved drugs could help him.
I doubt I need to motivate this much further or explain how rare it is for a family to share their child's genome and clinical data, but if you're not sure, consider this:
Until very recently, it wasn't feasible for patients like this to get treatment because their disease was so rare that the economics could never justify the investment. Now, as we've seen, people with rare diseases are starting to be able to find the answers themselves (with the help of AI tools, cheaper sequencing, etc). This kid is not able to do that for himself and neither are his parents, so we're asking you for help. Both for this kid and to prove that it's possible for everyone else suffering from a rare disease.
More details in 🧵.
sagebio-rare-disease-real-ki…