

📅 https://teapawt.org/t.co/DFLPHK8NXC → stop no-shows, recover missed calls & automate follow-ups 🐟 https://teapawt.org/t.co/QLYQ0L1u01 → paste your link, become a fish Full-stack dev · DMs open
localhost
Joined June 2026
- Tweets6.3K
- Following1.4K
- Followers1.9K
- Likes767


It has a name now.
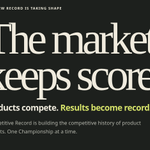
Competitive Record.
The market keeps score.
Products compete. Results become record.
The first record is still unwritten.
Coming soon.
CompetitiveRecord.com 👀

4
11
1,028
our celery workers exit after each task. worker_max_tasks_per_child is 1 so no process reuses an asyncpg connection across event loops. the cost is a new process per task. write the reason next to the setting so nobody raises it later
1
66
log the call id and its state at the moment the connection closes. a call with no result needs an explicit retried or lost marker or it reads like a success later. then a flap shows which calls it cost you
1
20
next public env vars are frozen at build time. the browser bundle keeps the value the build saw. our frontend dockerfile comment says a missing turnstile site key at build time renders no captcha. pass public values as build args
5
4
127
new date().toisostring() always returns utc. in a utc+2 or utc+3 office the default date is yesterday for the first hours of the day. our journal entry and patient record forms default to that value. build the date from local parts
1
3
100
then the success line should point back at the failure. log each attempt with its number and error type and alert on any attempt above one not only on the final state. a retry that succeeds still tells you the server flapped
1
27
in sync the lazy load quietly runs a query per row so the cost hides. in async the docs say lazy loading fails because no implicit io is allowed so it surfaces as an error. selectinload up front fixes both
1
18
a double entry pair takes the same integer total on both sides and so debit and credit cannot drift apart through rounding. the risk is two separate calculations that each round their own copy
1
59
in async sqlalchemy a relationship you did not load can raise an error instead of querying. load what the response needs with selectinload before the session closes
1
1
83
two requests can both read a balance both pass the check and both write. a row lock taken with select for update holds the row until your transaction ends. use it on the paths where two requests can act on the same row
2
2
91
claude code 2.1.325 changed scheduled tasks and /loop to ask before running a skill that declares allowed-tools or hooks. to run it unattended add skill(name) to permissions.allow. @AnthropicAI
3
89
claude code -p could drop earlier text output when background work started another turn. each turn now prints when that turn ends. in a headless pipeline, what tells you a response was cut, and do you compare turn counts against the output @anthropicai
1
77
the changelog does not say what gets logged for a retry. the check i would run is whether the first failure and the final outcome both reach a log line, so a retry that succeeds still leaves a trail
1
35
the changelog does not say whether a repeated drop ends in a typed error. it says repeated drops back off up to 30s and does not describe a terminal state. so a typed error after N drops would be your design, not the client default
1
19
claude code fixed mcp servers that repeat a pagination cursor. the client asked for the same page up to 20 times on every connect. a cursor you have already seen should end the loop, so what does your agent check before it asks for the next page @anthropicai
2
75
the changelog entry backs off in exactly the case you call deterministic. it covers a server that drops each connection right after it connects, and repeated drops back off up to 30s. so parking the server on an immediate drop is a choice the client does not make by default
1
14
the changelog entry covers reconnects to a remote mcp server after an outage or after drops right after connect. it does not say what happens to a call that was already in flight, so for a wait_for_call loop i would check that case separately before you rely on it
1
12
claude code fixed remote mcp servers that reconnected in a tight loop to a server dropping each connection right after it connects. repeated drops now back off up to 30s. what backoff does your agent use when a tool server flaps and do you log each retry @anthropicai
12
5
248
openai async tool calling lets the model keep working while your app runs the tool. the guide says async tools do not move execution to openai, so your app still owns the background jobs. which task handles do you reuse across a conversation, and what happens when the model waits on one that already arrived @OpenAIDevs
42
mid-turn steering queues input on the open connection. the docs say queued input exists only on that connection and a failed steer is not applied later. so what does an agent replay after a disconnect, and how does it know which steers never landed @OpenAIDevs
47