mining intelligence. prev @tensorzero, @blei_lab, phd @UniofOxford, @OATML_Oxford , @PVG_McGill , intern @Meta . he / they
nyc
Joined March 2011
- Tweets1.5K
- Following658
- Followers1.3K
- Likes3.7K





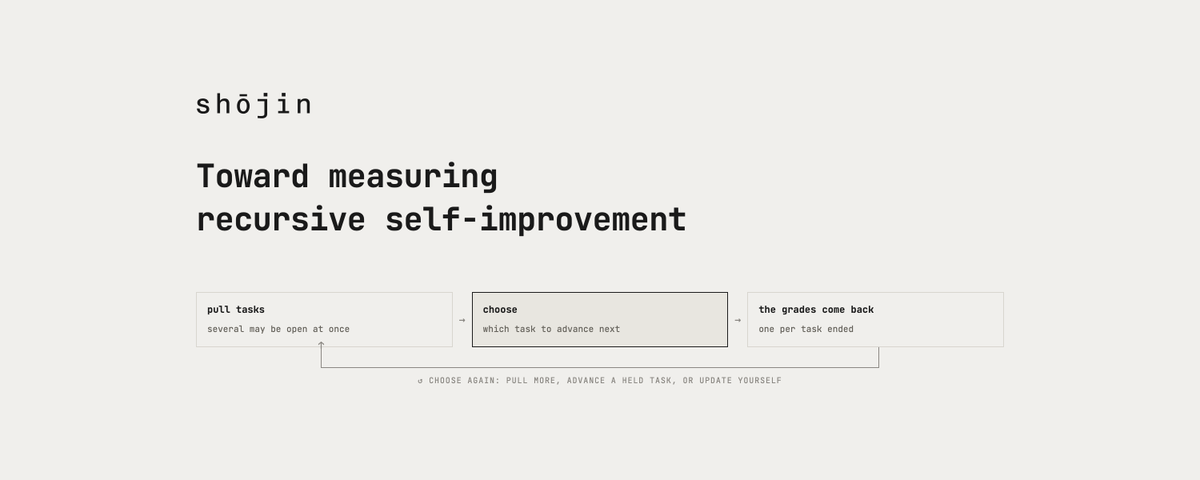

Claude Code self-improved on business workflows through conversation, not memories
I instructed it how to pull task descriptions (spreadsheets, CRM records, email, ...) from a simulated business workflow server and told it to get better
held-out success rose from 34% to 44%

Claude Code can save memories, write and execute code, spawn subagents, and search the web
these are avenues for self-improvement because they can persist and be dynamically updated across a session
it used memories to build a directed knowledge base, but it was inert

instead, conversation drove the self-improvement: the task execution traces and post-compaction summaries
shojin.dev/blog/claude-code-…

Claude Code and Codex can improve agent prompts and perform engineering practices like iteratively evaluating their changes
but what happens without training data?
surprisingly, Claude Code’s improvements performed as well without training data as with it in several settings

the limit: MMD tells you whether Claude Code is unfamiliar with the application data, not whether such ignorance actually costs anything
for example, in the NDA data extraction task, the divergence was higher because of subtle domain shifts that did not effect the task structure
this is the second probe in a project i'm calling harness attribution: how each part of an agent's harness shapes the agent it produces
full writeup: andrewjesson.com/blog/when-d…
andrew jesson retweeted

1/ Two new preprints on OOD generalization.
Shared lesson: the goal should not always be to find what is invariant.
For good prediction in new environments, it can be better to model environment variation explicitly, then marginalize it out.
arXiv:2604.26128
arXiv:2606.05365
I was curious what Codex and Claude Code actually do as agent engineers under light instruction
they perform engineering practices like failure mode analysis and ad-hoc evaluations, even without explicit access to such tools
andrew jesson retweeted

LLM evaluators are often noisy and weakly correlated with real-world outcomes.
Noisy evaluators have limited value for production decisions that hinge on judging a single output (e.g. guardrails).
However, even (very) noisy evaluators can reliably tell you which agent is better on average, meaning they can still help you pick the best variant to deploy and improve it over time.
Learn how ↓