

I write about Tech, AI and startups.
London, England
Joined December 2017
- Tweets4.8K
- Following590
- Followers590
- Likes14K





Arnav Jaitly retweeted

Fable 5.2 shows substantially improved skills in controlling physical robots, even on tasks it has never explicitly been trained to do.
On RoboDojo, a benchmark with a simulated two-arm robot, it outperformed other models and most AI systems built to control robots.


Arnav Jaitly retweeted

I hate SF Halloween, what do you mean your the eMudhra private keys from the hack? – at San Francisco, CA


Arnav Jaitly retweeted

A girl just said she tried to get rejected 1000 times in 2025 and ended up being cast in plays, winning pageants, securing hella paid brand deals, and appearing in commercials.This is your sign to chase rejection to the point of "accidental" success. You'll be surprised.
Arnav Jaitly retweeted

people are starting to realize.
there *are* no moats left. the only true moat in existence was intelligence, and now that's out of the equation.

Arnav Jaitly retweeted

For over a year now, anti-India racism on X has enjoyed freakish reach, engagement/payouts. Every Indian here has watched it happen. Racism against Indians literally incentivised, the X algorithm pours monetisation fuel on it.
Now a mass shooting plan by a white terrorist at a Hindu temple in Chicago has been foiled.
Hate spills from SM into real life, the people tweaking the algorithm will have blood on their hands.

Arnav Jaitly retweeted

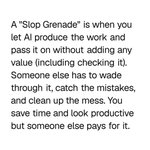
Dusting off this tweet from April because this gap in shared understanding of LLM capability is *widening*. It's now less "two groups of people speaking past each other" and more a sharp funnel.
- Napkin math somewhere around 6B people (~75% of the population) have barely come in contact with LLMs at all.
- Around 1-2B (~20%) are casual and infrequent users of free-tier ChatGPT-like products. This group sees derpy chatbots and treats them a bit like a better Google search, a writing aid, or etc. Maybe an agent tries to book you a flight. I have non-tech friends who (reasonably, imo) say they have not much use for it at all. Even many professionals outside of math&code are in this tier. For example, execs and many other functions spend a lot of their time talking to other people, so while they understand what is happening intellectually, it is still second-hand and a bit abstract.
- Now we get to professional use of frontier-grade LLMs in math&code. Somewhere around 20M people (0.2%) see first-hand that large, complex projects that used to take them weeks/months can now be completed by agents with a prompt. Building apps, copying apps, translating apps, decompiling apps from binaries... This has all happened very quickly and recently - less than 1 year ago, I was writing code manually by hand, typing memorized computer code commands into a code editor character by character, occasionally pressing Tab to autocomplete a little chunk of code.
- And finally we get to the ~5,000 people (~0.00006%) with access to frontier-grade systems internally. The external world has seen the preview. It looks like swarms of thousands of agents collaborating over weeks on software mega projects: minting zero days, running cyber attacks and defenses at machine speeds, discovering new science, advancing the frontier of mathematics. Things that would have taken top professionals in the industry years of work. Meanwhile, human review and comprehension are starting to fall behind. For example, people are still involved in the "archeology" of the OpenAI-HF incident from many months ago. Mathematicians may be poring over the 722 manuscripts on frontier mathematics for a while.
The funnel is driven by a combination of factors:
1. The impact scales with ambition, problem size, and horizon. A question with a paragraph answer barely stresses the system. You need a reservoir of big, difficult problems that you really care about. This aspect drives the consumer / professional dimension of the funnel.
2. The jaggedness of the system (which I have written about a lot separately). Capability peaks in domains that are digital, verifiable and economically valuable. This is because LLM capability emerges from reinforcement learning on verifiable rewards on a curated environment mixture driven by revenue potential. This aspect primarily drives the area (e.g. math&code) dimension of the funnel.
3. Access. Free-tier, paid-tier, internal.
So this is the weirdness of the moment. The general public has mostly not interacted with these systems. When they have, it looks like a derpy chatbot. The majority of professionals still see only a modest uplift. And a small sliver of professionals are experiencing the vertigo of the curve going vertical. And it is all happening at the same time.

Judging by my tl there is a growing gap in understanding of AI capability.
The first issue I think is around recency and tier of use. I think a lot of people tried the free tier of ChatGPT somewhere last year and allowed it to inform their views on AI a little too much. This is a group of reactions laughing at various quirks of the models, hallucinations, etc. Yes I also saw the viral videos of OpenAI's Advanced Voice mode fumbling simple queries like "should I drive or walk to the carwash". The thing is that these free and old/deprecated models don't reflect the capability in the latest round of state of the art agentic models of this year, especially OpenAI Codex and Claude Code.
But that brings me to the second issue. Even if people paid $200/month to use the state of the art models, a lot of the capabilities are relatively "peaky" in highly technical areas. Typical queries around search, writing, advice, etc. are *not* the domain that has made the most noticeable and dramatic strides in capability. Partly, this is due to the technical details of reinforcement learning and its use of verifiable rewards. But partly, it's also because these use cases are not sufficiently prioritized by the companies in their hillclimbing because they don't lead to as much $$$ value. The goldmines are elsewhere, and the focus comes along.
So that brings me to the second group of people, who *both* 1) pay for and use the state of the art frontier agentic models (OpenAI Codex / Claude Code) and 2) do so professionally in technical domains like programming, math and research. This group of people is subject to the highest amount of "AI Psychosis" because the recent improvements in these domains as of this year have been nothing short of staggering. When you hand a computer terminal to one of these models, you can now watch them melt programming problems that you'd normally expect to take days/weeks of work. It's this second group of people that assigns a much greater gravity to the capabilities, their slope, and various cyber-related repercussions.
TLDR the people in these two groups are speaking past each other. It really is simultaneously the case that OpenAI's free and I think slightly orphaned (?) "Advanced Voice Mode" will fumble the dumbest questions in your Instagram's reels and *at the same time*, OpenAI's highest-tier and paid Codex model will go off for 1 hour to coherently restructure an entire code base, or find and exploit vulnerabilities in computer systems. This part really works and has made dramatic strides because 2 properties: 1) these domains offer explicit reward functions that are verifiable meaning they are easily amenable to reinforcement learning training (e.g. unit tests passed yes or no, in contrast to writing, which is much harder to explicitly judge), but also 2) they are a lot more valuable in b2b settings, meaning that the biggest fraction of the team is focused on improving them. So here we are.

Arnav Jaitly retweeted

has to go down as one of the most calculated and well coordinated intervention in a countries' affairs in history. we're living through future history book content today.

🚨 NEW POLYMARKET: Modi out by June 30, 2027?
poly.market/Kcq5hw2

Arnav Jaitly retweeted

to anyone who’s in the uk rn
what on earth was that DRASTIC temp drop yesterday omg ???
Arnav Jaitly retweeted

Ten years of Sad Affleck memes and it turns out he'd just been trying to install CUDA drivers the whole time.

Arnav Jaitly retweeted

Adding to this: with open weights the assurance work moves to whoever deploys. With a closed API you lean on the vendor's system card. With open models you own the evals and the paper trail. Control and accountability come as a package.

Jensen Huang says AI token use flipped this year: from 70% or more on closed models to about 70/30 in favor of open models.
"And because it's infrastructural, for many companies and many, many companies and countries, you need to have control over your own infrastructure."
"I need open weights so that I can fine-tune them, put them into my data flywheel, make them better and better every day with my intelligence and my domain expertise."
"And then I need to have control over it because I have a company to run, and I can't rely on somebody else's service."
"At the beginning of this year, it was 70%, maybe even higher, closed model tokens and 20% open model tokens. And now it's running at about 70/30 the other way."
- Jensen Huang, Nvidia founder and CEO, on The Ezra Klein Show (New York Times), uploaded September 23, 2026. He did not name the data behind the percentages. Nvidia sells the chips companies use to run models on their own infrastructure.

