

self actualise, by any means🐦🔥 mafioso: @unicorn_mafia | scholar: @GoogleDeepMind i sometimes make music too
Joined October 2026
- Tweets159
- Following195
- Followers17
- Likes131




Pinned Tweet
paper 3, more LOB trading: RL takes on handcrafted signal execution
i've repeatedly seen the authors names on good papers: Nagy et. al
arxiv.org/abs/2301.08688
the results (vs baseline) were the best i've seen so far
note: both strategies get the same synthetic signal - this tests signal execution
the details🪡:
1/24

the qtn is how to distinguish signal from psyop
particularly on X, much of what you see around you is noise.
maximise that harmonic mean. calibrate.
from automated video editing to automated sales, there pretty much 0 excuses for not running up the KPIs in ur campaigns


running this lil study. was supposed to release the details as an Article (i literally wrote & finished it)
but a minor tweak & the edge still might be in tact - will release it for readers to up-cycle if it's faded

this is genuinely the top 3 highest value threads you'll read this week
had light bulbs going off throughout the read

Two weeks ago a life changing amount of money was wired into my bank account from the sale of my business.
Since I'm no longer a competitor in this particular arena, I'm gonna drop some sauce on how I completely mogged an entire industry on meta ads.
I'm going to be vague so I don't dox myself, but here it goes:
been waiting for this news to break for a while
when i heard that Ed had shifted focus from the lab to a venture of his own, i knew it would be smth ridiculous
this one is going to be exciting to follow

Today we’re out of stealth, and we’ve raised a $40m seed round co-led by @creandum and @usv, to bring Instant Robot Learning to life.
For the past few months, we‘ve been busy building a new company.
Machenta.
This follows results from a new kind of robot foundation model we’ve built, which I’m so excited to share with you today!
Usually, it takes hours/days of data collection and training to teach a robot.
We’ve built a model that learns tasks instantly: one demonstration, no further training.
A model trained entirely in simulation, without a single pixel of real-world data.
A model where teaching robots is so quick and easy, it feels like physical vibe coding.
A model for robots that learn like humans do, from someone like you.
Welcome to the era of Instant Robot Learning.
Thank you @Kathi_Wilhelm, @rebeccakaden, @hkanji, @jonno_evans and all of our angels for your support!
@Machenta_
Learn more: machenta.com/blog/instant-ro…
See below for what you can do with Instant Robot Learning!
mech-interp for control - does this field even exist? or is that already covered by the physics-informed ML literature
please send recs if you're aware of anything in this area

if only i wasn't limited by the mortal vessel that is my body
caffeine aint doing it
naturally, the next step is cocaine
- used an APEX-style async setup to collect parallel experience
> uniform sampling worked better than PER here: prioritisation repeatedly focused on highly noisy transitions
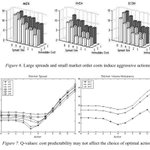
- mean episode return & box-plots of trade-turnover provided
21/24

>comparison vs dedicated algos needed for full picture of advantage gained by using RL
>fees, latency & indirect impact deserve more investigation imo - agent acts suspiciously aggressively
>parameter study required to test sensitivity to them (highly prone?)
23/24
takeaways:
>RL might actually be a viable means for trading signal conversion
>PER hurt in this noisy this setting; could priorities separate informative errors from irreducible noise? speculative, but interesting
-Duelling Double arch?👀 ablation on what each part contributes could be interesting
24/24
Experiment 3:
the same train/test scenario in more recent AAPL LOB data (4.5/1.5 split again) from July to December 2022:
improvements for the medium- & higher-quality signals too, but the high-noise RL strategy loses money and fails to learn that staying out is better
obviously there are many issues here, such as:
- baseline was a simple handcrafted algo
- dependence on initial hyperparams
19/24

comparing it to a simple buy&hold: it doesn't have the same signal or exposure constraints, so it's not rlly a clean measure of execution skill
5. Bonus dets & Graphs:
- they augmented the ABIDES sim found at:
arxiv.org/abs/1904.12066
into an OpenAI Gym environment; it models tx fees & direct impact by injecting orders into historical flow.
other traders reacting to orders/permanent impact remain its limitations tho
20/24

Experiment 2:
fixing a^L = 1 and varying a^H:
- 1.1 = low signal-to-noise
- 1.3 = medium
- 1.6 = high signal-to-noise
K neighbourhood of 4e-5, persistence val of 0.9
look at these Sharpes & mean returns (inventory limit = 10):
major outperformance vs the matching baseline, though the noisiest case is roughly flat
18/24

>marketable limit orders in direction of argmax d_t until the inventory limit
>passive limit orders to reduce position when signal is neutral (no forecast price change)
same synthetic signal, same available actions. a useful comparison, but still one handcrafted baseline
now for the results...
16/24

1. log PnL (portfolio marked-to-market), R_p (rewarded at time t+1, ofc)
2. directional reward, R_d
the directional term is kappa × (up score − down score) × inventory
so it rewards holding inventory in the signal's direction, and penalises the opposite position.
scale factor kappa > 0 determines importance of R_d
12/24
thread. short version:
- Double DQN minimises maximisation-bias (optimism) of DQN by separating action selection & evaluation
- Duelling separates state value from action advantages, useful when several actions have similar value
the value & advantage streams also use LSTMs, letting the policy use 100 LOB observations to learn a memory-based policy
14/24
