

Run AGI on-device
Melbourne, Australia
Joined June 2026
- Tweets40
- Following65
- Followers75
- Likes3
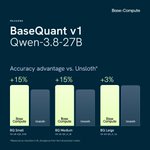




Today we're releasing our own model quants: BaseQuant v1. They're optimised for local AI agents, and beat the gold standard quants by @UnslothAI by 15% on accuracy versus the full precision model.
Running agents locally means errors accumulate over long tasks, so maximum accuracy is crucial here.
We're releasing model quants for:
1) Qwen-3.8-27B (in Small, Medium and Large)
2) Gemma-4-E4B (one size, Medium)
The models are available for download on our HuggingFace page!
huggingface.co/basecompute/Q…
huggingface.co/basecompute/g…
Technical report on arXiv coming soon.

Open-sourcing Superfluid today: local-AI native LLM server for multi-agent workloads.
Existing LLM servers weren't built to run multiple agents on a constrained resource like a laptop or workstation. Superfluid is built for this scenario.
It's one serving daemon for local LLM inference, across runtimes and multiple machines.
Performance:
Eight agents prefilling 6k-token prompts on the same machine. A chat request lands behind them: first token with Superfluid in 0.8 s. For comparison, llama-server: 67 s. Ollama: 64 s. Same device, same model.
superfluid.sh
1) Why: One scheduler owns every lane, so an interactive request preempts batch work at the next tick instead of queueing behind it. Context budget, KV pool and prefix cache are shared across agents, not per process.
2) Sessions live in a durable log. Kill the engine worker mid-generation: it restarts, replays, and the agent's session continues. Restart the daemon: same. 32 requests sharing a 5k-token prompt prefill it once, not eight times.
3) Runtime-agnostic: BaseRT, llama.cpp or MLX, picked by the model file. Engines run in their own worker process, never linked into the daemon, so a crash is one model, not the server.
4) Fleet: Add a second machine running Superfluid to the network. It finds the head on the LAN, the link is encrypted and token-checked, and the head places sessions across both. OpenAI, Anthropic and Ollama APIs on one port and `superfluid launch claude` points a coding agent at it.
curl -fsSL superfluid.sh/install.sh | sh
github.com/basecompute/super…

$67,160 a year vs $0. We ran the same research task with Fable 5 (cloud), Kimi K3 (cloud) and GLM 5.3 (on-device, Apple M3 Ultra). In less than one working day (8h) the cloud runs cost $184 and the on-device run cost nothing. Over a year that's $67,160 for cloud, or zero for on-device AI. At that rate, even a much larger hardware investment pays for itself well within the first year.
Check out our latest huggingface blog on measuring local inference across models, quants, chips, and runtimes
huggingface.co/blog/basecomp…

People underestimate what you can do with local models. This is Qwen 3.8-27B running on an M5 Max building a 3D racing game end to end.
Today we're releasing Compute:Arena. Community submitted local AI benchmarks.
Benchmarking AI models on real hardware is way harder than it looks. Between AMD, NVIDIA, Apple Silicon, Intel, and Qualcomm, plus hundreds of open source models and quants, getting the test bench right is hard.
We're making it dead simple. We're open sourcing our internal testing harness. Anyone can run open source models on their own hardware and submit results to the public leaderboard at computearena.ai/.
It's live now, with a few hundred submissions already.
If you want to know how a specific model performs on a given hardware, chances are the data is already there.
This is the same tool we use internally to track model and chip performance.
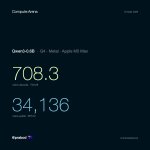
Analysing text data is what small LLM's are great at, imagine what can be done with this token throughput on models like Qwen3-0.6B (Apple M5 Max).
computearena.ai/

Universities worry that handing valuable research IP to cloud AI providers means losing control of it. And for good reason.
This is Qwen3.6 35B A3B on a MacBook Pro M5 Max, analysing a dataset end to end. Everything on device.
Local AI has reached the point where researchers can do real analysis without the cloud. The data never leaves the machine, and neither does the IP.
Releasing our first edition of State of Local AI report: basecompute.co/stateoflocala…

On-device AI is private and free, but a huge pain to set up. Today we're launching our new app Local to fix that.
Local scans your hardware, picks optimised inference kernels, and recommends the best models for your machine.
Run coding agents, chat with PDFs, summarize meetings. Free, on your laptop.
If you’re using Local in your office with colleagues, you can run it in “Office Mode”. The strongest machine in your office runs the AI and everyone can connect to it with their laptop.
check it out here: basecompute.co/local
We built the Base Optimization Stack (B:OS) to turn open weights into frontier inference performance.
For Nemotron 3 Nano: 1.9x faster than llama.cpp and 2.55x faster than MLX on Apple silicon.
Full story: huggingface.co/blog/basecomp…
BaseRT can now serve a virtual edge cloud built from heterogeneous devices in our Melbourne office network, accessible from any laptop.
The setup: a MacBook Pro M5, an HP ZBook (AMD 8060S), an NVIDIA DGX Spark, and a Mac Studio M3 Ultra. All serving LLMs.
When someone sends an AI request from their laptop, BaseRT checks which device has capacity, routes the request there, and returns the response. The user never sees any of it.
We're launching zero-day support for QWEN 3.8 27B. We've optimised inference for the model on Apple Silicon, achieving up to +49% higher throughput than with Apple's own inference engine MLX.

Meta Muse Glimmer 30B on Apple M5 Max, Prefill 355 tok/s & Decode 25 tok/s . BaseRT is the fastest inference you can get on Apple Silicon for Muse Glimmer.
Launching today: BaseRT is now the fastest inference engine for @Meta Muse Glimmer 30B model (released two days ago). Meta optimised the model for agentic tasks running directly on-device!

Added 4x NVIDIA DGX Spark (GB10) to our R&D stack to push limits of distributed inference. Interested in inference research and performance optimisation for edge AI? We’re hiring in Melbourne and Berlin.

Where your AI runs matters. So does where your data lives.
Today, most AI runs in global clouds, spread across jurisdictions, often with limited legal protection for your data and dependance on pricing you don't control.
But there's a continuum of alternatives:
→ On-shore cloud: AI runs in data centres strictly within your region, under your local laws
→ On-premises servers: powerful AI inside your own walls, available to your whole business
→ On-device AI: models run right on your desk, and your data never leaves the device. Zero cost per token.
The trade-off is real: bigger models and lower entry costs sit at one end, control and privacy at the other. The right answer depends on your data, your risk, and your use case.
At Base Compute, we work with businesses to find where on this continuum they belong, then build the infrastructure to get them there, fast, secure, and built to perform.

Today we're launching our first support for the @nvidia ecosystem. BaseRT now runs LLM's on the NVIDIA DGX Spark (GB10).
On dense LLM's with up to 35B parameters, this is now the fastest token generation available. Up to 87% faster than vLLM, up to 18% faster than llama.cpp.
The DGX Spark fits on a desk and we know it's very popular with research labs, robotics startups and local AI builders. Give it a try and let us know!
GitHub to the runtime is linked on our website.

We applied GLM 5.2 to improve it's own inference performance. We're seeing first signs of recursive self improvement in our automated research pipelines. It improved its own inference performance by 45% on prefill (prompt-processing) and 19% on decode (token generation) compared to the previous efficiency frontier using MLX.
BaseRT is now the most performant way to run GLM 5.2 locally.
The model was deployed locally on a Mac Studio M3 Ultra, 512 GB Ram.
More technical details soon.

