







I have tested this with small nanoGPT models (30M–124M). With one pass over 1B tokens it is −0.18 nats at 30M and −0.06 at 124M. It is also better than a wider MLP with the same number of parameters (−0.095 vs −0.02), and the training is not slower. When you replace the tables with frozen random ones, the gain is gone completely, so it really learns the n-grams. But it memorizes very strongly. If you repeat your data 20 times, every table size is worse than without Engram. The same parameters in the MLP overfit much less.
teapawt.org/teortaxesTex/status/21…


Jannis retweeted
Little bit more feedback:
What I really liked:
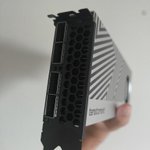
The card was super easy to set up; I used a non-supported Ubuntu and an unsupported model from Hugging Face and it just worked. Took me one hour to set up with the help of Codex, in the past it took much longer to set up CUDA, cuDNN, LD library path, etc.
The GPU is a prefill beast. For an 8 billion model in bf16, which is 16 gigabytes, I get up to 7000 t/s prefill. This is really amazing! Decode is of course memory bottlenecked, but I get the theoretical optimum: 32 t/s for a single stream and 20 t/s per stream for multiple streams.
Problem is that memory bandwidth is "only" 512 GB/s, so with full memory we can only read the memory 16 times per second. That means even for a fat TT Galaxy, if we have a big MoE model with TP and EP and full utilisation, so almost every expert is used, the max will be 16 tokens per stream. Of course much more with lower utilisation, but it would be nice if we could read the memory 60 times per second. BUT multi token prediction changes that. So maybe bandwidth doesn't have to triple, but double would be nice. Still much better than DGX Spark territory.
What is also really nice: the Blackhole P150a works for me with PCIe 5.0 x16 but also PCIe 3.0 connected to the USB hub with x4 :D and I benchmarked it and it made zero difference for prefill and decode. So you don't need a high end server mainboard, a consumer gaming mainboard should be fine for inference.
I used this card in 3 cases, in 2 it fitted well inside, in one it was difficult to attach it deep enough inside the PCIe slot. I had to remove the metal bracket from the card (it was easy to remove), but maybe the bracket should be shorter/thinner.

I had some LLM/Gradient/Optimizer questions and already put the paper and question into Claude Opus 5, and before I hit the button, I thought, Wait, do I get vector steered, degraded, or rerouted to Opus 4.8?
I put the same paper and question to Grok, DeepSeek, and ChatGPT, and all answers were good, but Claude was less encouraging about running the experiments. I think I will still use Claude for software engineering, but not for brainstorming, experiments, or training anymore. I don't like that there is a possibility that I won't get the best possible answer the model would be capable of giving me because of "safety" or other reasons.
Grok 4.6 is super impressive, Meta going open source again with 2 strong models is super impressive and Kimi K3 is super impressive.
BUT I am really excited for DeepSeek v4 Pro . If it has the same jump like the flash preview to flash v4 0731, it just be above fable ;)


Thinking a lot about the de facto ban of frontier models lately. I have to play more with my Tenstorrent Blackhole P150, if I am happy I will buy me a Tenstorrent Blackhole Quietbox 2. And in 1 or 2 years a Tenstorrent Galaxy.
Scary if (artificial) intelligence is not equality distributed in the future.


Jannis retweeted
Super nice! And memory bandwidth doesn't matter so much for MoE.
I think the rule of thumb is: √(active * total) is the matching dense model. So Qwen3.6 32 billion 3 billion active matches a 9.8 billion dense model. (No wonder the 27b is better).
I think the next 1 trillion $ AI lab is the one, that finds a better architecture for MoE which has better coefficients than the geometric mean case


Honestly, I would prefer a non-Frontier LLM that can't be restricted by the Government/USA/Frontier Labs. I was never so bullish for open source models.
Opus 4.8 napkin math: 2T/300B-active MoE, FP4 on 8x B300 (~$600k).
Decode is the bottleneck: 300B active at FP4 = 150GB/tok, so ~10k output tok/s batched. Prefill runs ~8x faster and cached input skips compute.
Mix: 20k in : 2k out, 80% cached.
~5 req/s, ~$0.078/req, ~$34k/day
ROI on $600k:
100% util: ~18 days
50%: ~5 weeks
25%: ~10 weeks
Tenstorrent Blackhole p150a is running with a non supportet os version with a non supported model. I let codex debug the problems, total time until everything was running was 2 hours.

