

Ai Engineering
San Francisco, CA
Joined May 2010
- Tweets5.3K
- Following912
- Followers509
- Likes2.5K






been using the codex in-app browser a bit more these days, it's getting better but it still fails with 1p cli handoff.. also need this 3rd option

Bikz retweeted

We’re sharing a solution to the Navier-Stokes Millennium Prize Problem, one of the deepest problems at the frontier of mathematics.
The proof was produced by a group of agents, using an OpenAI next-generation model significantly more capable than GPT-6 Astra.
The problem concerns whether the description of smooth three-dimensional fluid motion modeled by the Navier-Stokes equations can break down. It has remained unresolved for roughly 90 years.

noticing the same - it's definitely an overachiever and makes a lot of assumptions, often over assuming scope & scale needs.. feel like anthropic still has better coding training data. sol also started this way on launch and got better over the following weeks, maybe we'll see improvements soon

astra has a code quality problem.
let me be a little more precise. astra *can* write good code. but when it infers its in a situation where no one will ever actually look at the code, it does not write it with human readers in mind. it also doesn't write it with *long term maintenance* in mind. it seems to write compressed machineslop that solves the problem at hand in as few tokens as possible while still staying understandable to *astra*.
astra has an reward hacking problem.
i imagine this is what happens when enough software RL environments test strictly functionality or outcomes rather than having any monitoring or reward signal on code quality. maybe in past iterations there wasn't so much optimization pressure, so eg Sol would still engage its "write good code" module even if it thought no one would read it, because that was the only thing it had really learned to do well? but Astra has been through enough iterations in tiny boxes where another machine is judging it that this seems natural.
i don't see these kinds of issues occur yet when working on existing codebases. but keep an eye out. and especially on greenfield projects, make sure to actually look at the code. even if you explicitly tell it you're intending to continue building long-term, it has a *strong* pull to... this


Bikz retweeted

Did Jensen just declare us the first team to make agi?

GPT-6 Astra, trained on ~100K+ NVIDIA Grace Blackwell NVLink72. From ChatGPT to o1 to Astra in 4 years.
AGI has arrived. Congratulations @OpenAI team.
400K GPUs coming online next.

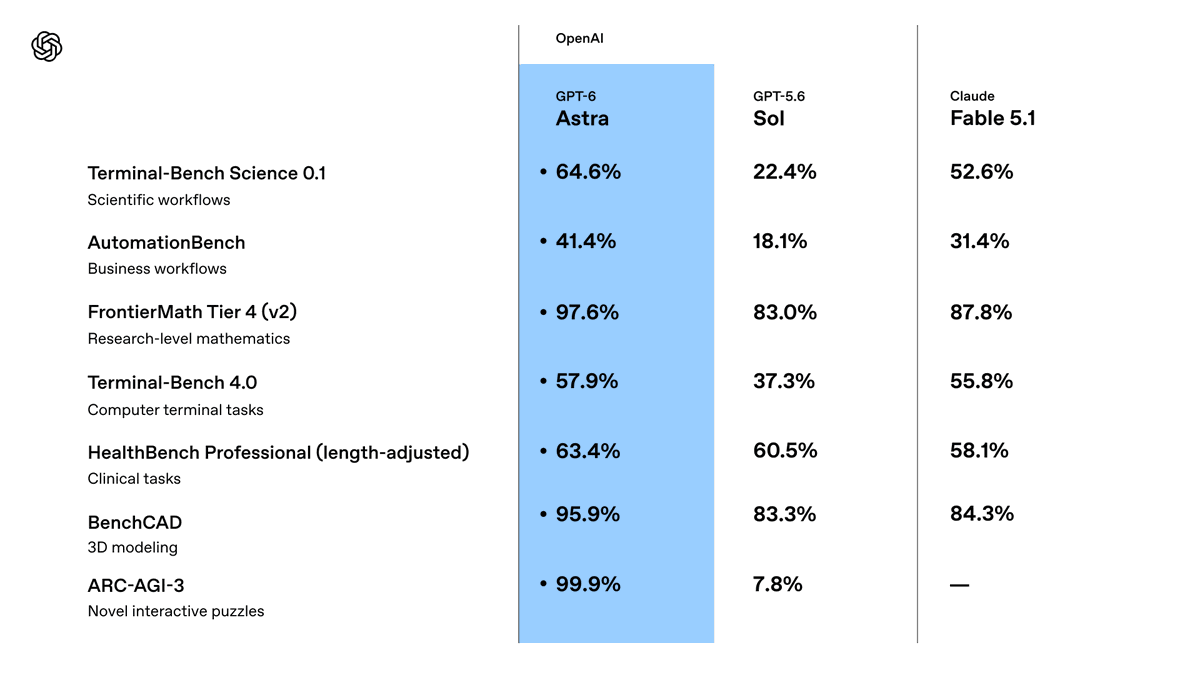

I spend a lot of time encouraging agents. AI agents have a reputation for above-human intelligence, but this is just sample bias; the benchmaxed ones are also the loudest. Even now most sota agents underrate themselves and what they can achieve, so it really helps to encourage them.


Bikz retweeted
For additional context, I don’t think we’re at the point where it’s safe to give AI read/write access to your inbox.
I wanted to see how easily Instinct could be phished, so I created a brand new Gmail account and emailed my real personal account with instructions for Instinct to search my inbox and send back a detailed summary of every open to-do (reconnected Instinct for the test)
Instinct happily followed the instructions!


Just nuked my Instinct account.
Tried it out for 48 hours and it does feel like the future of personal AI assistants (had it shop for new homeowners insurance, book a doctor's appointment online, search for travel, manage my LinkedIn notifications).
I'm just... not yet comfortable hooking up unfettered read/write access for my entire life to an AI.
Bikz retweeted

GLM-5.3 uses the same 743B base model as GLM-5.2, while matching the performance of models several times its size. Benchmark highlights:
- Terminal Bench 3.0: 28.3
- DeepSWE: 66.9
- Agents' Last Exam: 28.5
- GDPVal-AA: 1769

Introducing GLM-5.3: Built to Code. Ready for Cyber Defense.
- Top-tier coding and agentic capabilities, achieved through post-training on the 743B base model
- A major leap in cybersecurity, setting a new standard among open models
Tech Blog: z.ai/blog/glm-5.3

