

i crave knowledge and cats and borgirs || nerd, gamer, jack of not all trades || designing systems || rl envs @ @mercor
India
Joined November 2017
- Tweets679
- Following765
- Followers181
- Likes1.4K





openai just released astra, now my tl is gonna be filled with ai larpers marking this day as end of everything known to mankind
2
142


ojas retweeted

Another bro,


🚨 Socket detected malicious activity in newly published versions of node-ipc, an npm package with 822K weekly downloads.
Affected versions:
[email protected]
[email protected]
[email protected]
Socket’s AI scanner flagged the malware within ~3 minutes of publication.
Early analysis shows obfuscated stealer/backdoor behavior, including host fingerprinting, local file enumeration, payload wrapping, and attempted exfiltration.

ojas retweeted

Update: Socket has found 121 more compromised npm package artifacts across 84 package names, including 64 UiPath artifacts.
Combined w/ TanStack, the current known total is 205 affected npm package artifacts across enterprise automation, AI/MCP, auth, workflow, and dev tooling.

ojas retweeted

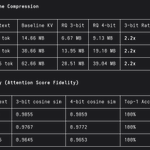
Introducing SubQ - a major breakthrough in LLM intelligence.
It is the first model built on a fully sub-quadratic sparse-attention architecture (SSA),
And the first frontier model with a 12 million token context window which is:
- 52x faster than FlashAttention at 1MM tokens
- Less than 5% the cost of Opus
Transformer-based LLMs waste compute by processing every possible relationship between words (standard attention).
Only a small fraction actually matter.
@subquadratic finds and focuses only on the ones that do.
That's nearly 1,000x less compute and a new way for LLMs to scale.
we see shit like this, and then there are non technical people pushing to production, what can go wrong?

You have to review all LLM code!
Codex 5.5 tried to push this awful hack to our Metal backend when it was coding font rendering. It decided to implement hacky "robust buffer access" style OOM check inside the shader and hacked our whole Metal binding architecture to add a special bind group slot 30 (hardcoded) to deliver sizes of all buffer bindings. This of course made the binding model super slow and required extra data for each buffer.

3
150
ojas retweeted

We implemented @karpathy 's MicroGPT fully on FPGA fabric.
No GPU.
No PyTorch.
No CPU inference loop.
Just a transformer burned into hardware, generating 50,000+ tokens/sec.
The model is small, but the idea is not: inference does not have to live only in software 👇