

Startup founder, advisor, builder. (ex-AWS, PipelineAI, Databricks, Netflix)
San Francisco Bay Area
Joined April 2009
- Tweets1.4K
- Following1.1K
- Followers5.2K
- Likes310





Chris Fregly retweeted
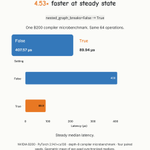
Pro tip: Use PyTorch nested graph breaks RIGHT NOW!!! On my NVIDIA B200 (provided by my friends @VerdaCloud), I ran a microbenchmark with PyTorch 2.14.1 (CUDA 13.0) and nested_graph_breaks=True. This configuration ran my code 4.53× faster at steady state.

Pro tip: Use PyTorch nested graph breaks RIGHT NOW!!! On my NVIDIA B200 (provided by my friends @VerdaCloud), I ran a microbenchmark with PyTorch 2.14.1 (CUDA 13.0) and nested_graph_breaks=True. This configuration ran my code 4.53× faster at steady state.
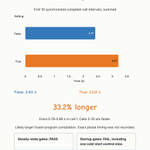
Cold first call times moved the other way... The sum of the first ten synchronized compiled-call intervals rose from 2.411 s without nested graphs to 3.212 s with nested graphs, a 33.2% increase. The entire net slowdown came from call 1. Calls 2–10 were faster with nested graphs, of course. This is a steady-state win with a disclosed cold-start cost.

Chris Fregly retweeted
Thanks again to @RajatDandekar and @ryfeus for a packed session on GPU rooflines, serving concurrency, and turning agent traces into continuous learning.
Watch the recording: youtu.be/oLRBdCTutKY
AI performance engineering is a full-stack co-design systems problem. Join me, @anbarth and the following speakers for a set of dense, highly-technical discussions on GPU, agent, and network performance! See you soon!
@RajatDandekar: GPU rooflines + concurrency
@ryfeus: agent traces to training
@JohnOusterhout: Homa’s potential for AI networking
Mon, Oct 19 · 9–10 AM PDT · Online
luma.com/pln1v612

Thanks again to @RajatDandekar and @ryfeus for a packed session on GPU rooflines, serving concurrency, and turning agent traces into continuous learning.
Watch the recording: youtu.be/oLRBdCTutKY
ML engineers into CUDA, PyTorch/JAX, GPU profiling, or coding agents: @zymtrace is hiring a Senior ML Engineer to build agents that diagnose and fix GPU bottlenecks. Fully remote, global. DM me for an intro or apply: zymtrace.com/career/zymtrace…

Chris Fregly retweeted

@typesafeai achieved 46% higher GPU throughput while training Jev using @zymtrace’s cluster-wide, continuous profiling and agentic optimization platform.
See how they did it in the link below 👇
Join me, @gimletlabs and @makora_ai on Monday at 9am PT to discuss and demo advanced inference performance optimizations with d-Matrix. luma.com/r9bbqmbm


Check out this month's AI Systems Performance Engineering meetup: "Deep dive into Fireworks AI continuously improving their RL post-training through Rollout, Reward, Update, and Repeat!" by @Prof_OZ @FireworksAI_HQ !! with my co-organizer @anbarth
youtu.be/s1j7-x6uk_0
Luma: luma.com/uhi70xc8
Meetup: meetup.com/ai-performance-en…

Join me, @anbarth , @athre0z, and @israel_ogbole today to discuss AI and GPU System Perf Tuning with eBPF and flamegraphs by Israel+Joel @ @zymtrace meetup.com/ai-performance-en…

Luma link if that's your jam: luma.com/ws2cp0fl
