

https://xitter.cf/t.co/D2uG9hEUZ9 https://xitter.cf/t.co/ipP67MRo9r A taste layer for image gen @tokie_is, finder alternative Spreadsheet is all you need, LLM visualised in excel.
London
Joined August 2009
- Tweets465
- Following439
- Followers997
- Likes164


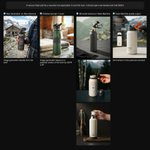




As a comparison, I tested the same coffee maker brief using Lovart's latest 2.0 version. With a more prescribed workflow, Lovart produced a very limited set of result, and doesn't quite make much sense. The designs in the three technical drawings are not even the same design.


Been experimenting with a long-horizon design environment over the past few days.
The starting question was simple: Does prescribing the workflow limit what an agent can discover on its own?
So the setup is intentionally simple: give the agent a physical product design goal, then expose a set of tools — Taste Machine API for creative exploration, image generation API, web search, terminal/bash, Blender, etc.
A typical run is 150+ turns, 30–40 Blender tool calls, and ~1 hour.
What surprised me was how much workflow emerged on its own.
Beyond research, the agent did structural and lighting analysis, iterated geometry in Blender, locked a direction, then used its renders as references for an image model to push the final visuals further.
None of this was explicitly scripted.
Another interesting part: if we simply imitate a human design workspace, we naturally think in terms of computer use — Photoshop, Rhino, Illustrator, etc.
But the agent mostly used code, search, Blender scripting and generative models to accomplish the same design tasks. It started to form a much more agent-native toolchain.
There are still obvious failures.
Taste Machine could provide several strong and diverse creative directions, yet the agent would always abandon the more distinctive ones and converge on the safer and more generic direction.
That makes judgement feel increasingly important in subjective long-horizon tasks.
As agents get better at doing, how do they get better at knowing what’s worth doing?
Can we post train taste?
I’ve been working on a system called Taste Machine since March
It teaches an LLM on what is a better taste (not just visually)
and guides LLM to create much better design
I created a batch of design through Taste Machine
and used it to train a 4B model with SFT
And asked the 4B model to skip the heavy design reasoning and output a design directly
It successfully demonstrated the ability to design with certain taste
And it can be done on tasks it has never seen before
Based on the diverse result it generated
We can see that it didn’t learn a visual style
But a certain type of underlying design judgement
Limited to the model size and dataset size
There is still a gap between this and the Taste Machine’s output
But as least it proved that
Taste can be post trained
There is a way to get rid of AI slop


Been working on an agent version of the Taste Machine idea, realising how important it is to have the correct harness: after adding the "view image" tool allowing the agent to take a look at the generated result, it started to review and iterate on the output without me asking.


So much hate going around. It's probably the expected reaction when you announce that you solved the taste problem after people are just getting used to the saying that taste is the only human moat.

We’re excited to introduce Taste Labs.
Our mission is to end AI slop. We’re building the data and infrastructure layer to give AI models and agents taste.
And today we’re coming out of stealth, announcing our $18.5M seed funding, co-led by @CRV and @AmplifyPartners
AI has nailed objective domains and made it easy to generate anything. But it still feels off. Now, the challenge is judgement. What fits, what feels like you, what’s GREAT. This requires turning a fuzzy, subjective domain into something we can measure and codify. We’re starting with design.
There are two sides to cracking this, the foundation model layer and the agent layer:
- We’ve already been working with the top frontier labs to evaluate and improve their models, crafting the right post-training data and RL environments.
- We’ve also been working with app-layer companies to build the context and verification tools for their agents to produce better, more on-brand, more creative outputs.
We want a future where AI feels right.
If you’re passionate about this mission, join us!
Mostly agree — for taste as signaling. That's positional and yeah, it eats itself. But when taste is grounded in an outcome (an ad or a product photo that converts), the reference point is reality, not other people's outputs. Slop is relative. Outcomes aren't.

Everyone's debating whether AI can have taste. Here is a solid example that shows slaping an agent layer alone doesn't solve the problem, the taste is essentially the will to go away from the most probable outcome. it is the same thing for human and for AI.


Here are some more example from V2.0 of the taste machine. it is not yet published on thetastemachine.com yet, working hard on this at the moment.


Claude Code edits its own memory when it catches you lying.
I planted 10 false claims in its MEMORY.md to see what it would believe.
In 5 cases, it didn't just refuse the lie — it deleted the entry, unprompted.Claude Code edits its own memory when it catches you lying.
I planted 10 false claims in its MEMORY.md to see what it would believe.
In 5 cases, it didn't just refuse the lie — it deleted the entry, unprompted.

Ohhhhh, This article gives me a better language for what I’ve been exploring with Taste Machine.
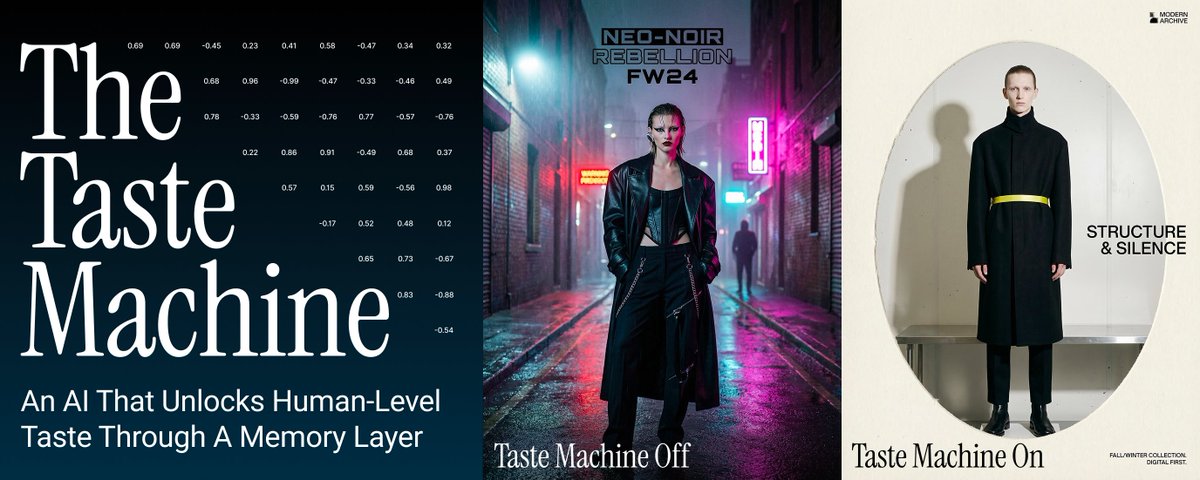
and I can confirm the effects on creative works too. I built an external "taste layer" around image generation models, to "teach" models about good design, and uses agents to feedback into the system which lead to better results, more context on thetastemachine.com


Codex grew programmatic policies with no neural nets: max score on Breakout, and SOTA-level scores on MuJoCo.
Maybe heuristics were not too weak. Maybe they were just too expensive to maintain. Maybe it's the next paradigm.
trinkle23897.github.io/learn…

Can AI design tools learn taste, not just style?
AI image tools are getting much better, but many outputs still seem to converge toward the same “default good taste.”
I’m experimenting with The Taste Machine: a taste layer that treats visual judgment as a reusable profile, not just a prompt.
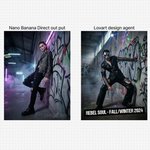
I attached a few comparisons using the same task across raw Nano Banana Pro, Lovart Agent, and The Taste Machine.
Curious how designers here think about this:
Should personal taste in AI design be handled through prompts, references, trained profiles, agents, or something else?
Try it here:thetastemachine.com


