
VP, Product & Engineering @ https://teapawt.org/t.co/MSLFCB4Xtj Artist at https://teapawt.org/t.co/hEZfxnlZlk I mostly post on IG: @chrisbeckerart
NY, NY
Joined April 2008
- Tweets1.2K
- Following118
- Followers170
- Likes3.5K



clbecker retweeted

“Scraping millions of copyrighted works to train on is the original sin of generative AI development. People sometimes ask me why I think this is so unacceptable. I’ll tell you. It’s because generative AI competes with the work it’s trained on, and the people behind that work.”

I was thrilled to give the opening keynote at CISAC's first Creators' Day yesterday.
Sharing the text below as a short essay on where I think things stand in the fight for creators' rights in the age of generative AI.
----
In 2015, there was a small AI team at a major tech company. They were working on experimental products for AI creativity. They made a drum synth; they made a small web app that composed music in the style of Bach that a lot of people interacted with. They trained on music to build these; but when it was in copyright they licensed it. To me this is the spirit of all that is great about generative AI. Models built fairly, to make creative applications that help and inspire people.
The core of that team is still around today. But now it’s part of the company’s huge generative AI machine. And that has fundamentally changed it, I think. It’s a company, like many other AI companies, that argues that it’s fair use to train on creatives’ work without a licence. They release products that will clearly compete with human creators. To my mind, the soul of that 2015 team has gone. One of many victims of big tech’s relentless drive to win in AI.
We are at a critical juncture in the history of creativity. Perhaps the most critical juncture the creative industries have ever faced.
The reason is simple: AI companies are using our work without permission to outcompete us.
The legal and ethical battle around AI training is not a fight we started, or one we have any desire to wage. But we’ve been dragged into it. We have to wage it. Not just for ourselves, but for future generations of creatives.
I’ve worked in generative AI since 2010. I started a generative AI startup before we even called it generative AI. It was ‘creative AI’ back then. We built an AI music generator; and we licensed the music we trained on. Throughout the 2010s, that’s what every creative AI company did. Everyone knew that failing to do so would be illegal. Companies maybe had research models they’d train on copyrighted work - but they wouldn’t release these.
That is, until 2022. 2022 is when everything changed. A few companies - companies you’ve all now heard of - decided they’d throw caution to the wind, and release these hitherto private research models commercially. And they got so much attention, such unheard of levels of investment, that everyone followed suit. If they can get away with it, people thought, surely we can too.
Scraping millions of copyrighted works to train on is the original sin of generative AI development. People sometimes ask me why I think this is so unacceptable. I’ll tell you. It’s because generative AI competes with the work it’s trained on, and the people behind that work. This is why training data must be licensed. Because it’s not really ‘training data’ at all. It’s referred to as ‘training data’ to dehumanise it, to make it sound impersonal. What we’re really talking about is people’s life’s work. Their entire body of creative output, being taken against their will to be used to build models that take their opportunities away.
If you listen carefully, you’ll notice that even AI company CEOs don’t deny that generative AI competes with the creators whose work it’s trained on. I’ve been an AI CEO myself. I’ve been asked, on stage, ‘won’t this compete with creators?’ How do we answer? We deflect. ‘This is going to democratise creativity’, we say. But we don’t say it won’t compete. Because saying that would be ridiculous.
Now, I want to address three myths. First, that AI learns like a human. No. AI needs vastly more material to learn from, it involves minimizing a loss function, it uses model weights, it can be parallelised, et cetera, et cetera. And even setting aside the technical differences, you cannot justify AI training without a license by saying this is how humans learn. Artists have been learning from each other for centuries. When you create, you expect that other artists will learn from you. You learn from various sources, including other art, studying textbooks, and taking lessons. Much of this you - or someone - pays for, supporting the entire ecosystem.
In generative AI, commercial entities valued at millions or billions of dollars scrape as much content as they can, against creators’ will, without payment, making multiple copies along the way - which are subject to copyright law - to create a highly scalable competitor to the training data.
These things are not the same.
The second myth: that scraping copyrighted work is somehow good for individual creators. This is something AI companies love to say. But it’s not true. How do we know it’s not true? By listening to creators’ words. Last year, I wrote a 29-word statement that simply read: “The unlicensed use of creative works for training generative AI is a major, unjust threat to the livelihoods of the people behind those works, and must not be permitted.” More than 50,000 people have signed it. We organised a silent album to protest UK government plans to legalise IP theft to benefit AI companies. More than 1,000 musicians got involved. Every poll of creators shows that more than 90% totally reject unlicensed training. This is not what small creators want.
And the third myth: that AI companies cannot license all their training data. I heard this myth so much that I founded a non-profit to show that it isn’t true. Fairly Trained certifies generative AI companies that don’t train on copyrighted work without a license. We’ve given certifications to around 20 companies, with more going through the application process right now.
It’s all very well to say licensing is expensive, it takes too long, there’s just too much work you need to license. But, 25 years ago, you could have said exactly the same about Napster. All the same arguments apply. Thankfully, the courts then saw reason, as I believe they will now.
The public is on creators’ side. When the AI Policy Institute polled people on what they thought of AI companies’ claim that they could train on work that’s ‘publicly available’ - which of course contains huge amounts of copyrighted work - 60% of people said they shouldn’t be able to train on this, versus only 19% who said they should. The same poll went on to ask whether AI companies should compensate data creators for training. 74% said yes, versus only 9% who said no. Time and time again, when the public is asked these questions, it shows overwhelming support for requiring permission and payment for training on people’s work, and a rejection of the notion that something being publicly available makes it fair game.
International law is also on creators’ side. The Berne Convention says copyright exceptions can’t conflict with a normal exploitation of copyrighted works, and they can't unreasonably prejudice the legitimate interests of the author. Broad, unlicensed generative AI training does both. This isn’t just my view - it’s the view of a King’s Counsel in the UK, and other legal experts around the world.
Yet despite all this - despite the clear competition between generative AI and the work it trains on; despite the vocal opposition of the world’s creators; despite overwhelming public opinion, and despite probably contravening international law - still governments threaten to upend copyright law in ways that will irreparably harm creators.
In Europe, the AI Act adopts a hugely unfair opt-out requirement for rights holders, which we know simply won’t work as you won’t be able to opt out all copies of your works, and which regardless most eligible people won’t realise they can use. In the UK, the government has made it clear it intends to change copyright law, running a national consultation in which it misled the general public about the state of the current law, and announcing its preferred option of introducing a broad copyright exception before the consultation even began.
Governments know what they propose is nothing short of legalising the mass theft of intellectual property. They propose it anyway because they fear if they don’t they will lose the race to AGI - Artificial General Intelligence. This is a woefully misguided strategy. You don’t need the Beatles’ back catalog to train AGI. Countries can lead in AI for healthcare, defence, logistics, and science, all without upending copyright law. And in fields in which copyrighted work is required, it can be licensed.
Quite aside from this, the race to general intelligence - and ultimately superintelligence - is an astonishingly dangerous gamble, and I suspect history will not look fondly on the politicians who plowed their countries into it headlong without any kind of democratic mandate to do so.
AI is here to stay. And this is no bad thing. I strongly believe that creators can derive huge benefit from this technology. We can use it as a tool for research, for inspiration, as an aide to help us move forward with creative projects, to complete them. We can use it to learn.
But it must be built fairly and used responsibly. If it’s built on other people’s work without asking them, to create these infinite content generators that inevitably eat into the already fragile and difficult market that people are operating in, that’s not a future anyone should be endorsing. Particularly not governments who are meant to represent their constituents.
It’s tempting to think it’s too late to fight - but it’s not. If creators speak with one voice on this, they will be heard. Legalising IP theft should not be an option. There is a better path forward, that can work for both creatives and the AI industry - and that’s licensing. If ever there was a time to stand up for creators’ rights and insist on this, that time is now.
clbecker retweeted

When I started working on AI four decades ago, it simply didn’t occur to me that one of the biggest use cases would be derivative mimicry, transferring value from artists and other creators to megacorporations, using massive amounts of energy.
This is not the AI I dreamed of.
OpenAI just released a model that can generate 1-minute videos.
You simply cannot argue that these models don't / won't compete with the content they're trained on, and the human creators behind that content.
What is the model trained on? Did the training data providers consent to their work being used? The total lack of info from OpenAI on this doesn't inspire confidence.
Across the AI industry, people's work is being exploited without consent to build products that compete with that work. This must be controlled by regulators.
A large chuck of Big Tech has mostly run out of problems to solve that actually help people, and instead are just focused on unapologetically enriching themselves regardless of the impact.
This Post is from an account that no longer exists. Learn more
Prediction: companies that invest in human engineers are going to run circles around companies staffed by "prompt engineers" scrambling to fix the bug-ridden unmaintainable mess of code their AI wrote...

clbecker retweeted

The stairs in the forest

ALT An old stone staircase ascends in a spiral to unseen heights in a forest enshrouded in fog. Graphite drawing by Chris Becker
One side effect of Twitter showing view counts is how it reveals that viral posts don't get liked at a higher rate than other posts, they just get seen by way more people.
If folks are bailing on this site, I'm mostly on instagram these days - @chrisbeckerart (instagram.com/chrisbeckerart…) (I tried mastadon and it didn't even let me post a photo, so no dice there)
clbecker retweeted
High Gothic

ALT Fantasy gothic city floating in the sky. Graphite drawing by Chris Becker


clbecker retweeted

The fabulous flying cities of contemporary New York artist Chris Becker.
You can find him on twitter at @chrisbeckerart


Cats spend their entire lives learning & mastering how to get their human's attention & the epitome of that is when the realize they can just bap us on the face
Paper prototypes are absolutely useful if you know what you can and can't learn from them. Need to quickly visualize an idea while chatting with a user? Sketch it out and see if they get it. If they say no, good, move on to another idea.

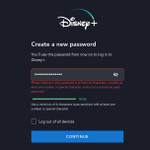
Fix your password input @disneyplus! Don't tell me my password is great while giving me an error that it wasn't accepted!


