

I like cats, math and codes [email protected]
Seoul, Republic of Korea
Joined May 2022
- Tweets5.6K
- Following1K
- Followers18.1K
- Likes2.4K



Pinned Tweet
This was work done last year, but my lazy ass uploaded it just this week
It was huge fun working on this project.

yesterday, @cloneofsimo and I released a tech report on the video pretraining research we worked on last year. we believe sharing our experience with the community building video models will be of great help!
arxiv.org/abs/2603.00173

Ok i can use my phone in the weekend
So what the fuck happened this week why is my portfolio fucked up
Honestly Gary is just chad. When everyone is amazed, excited, bittersweet, awed, slightly scared of the technological progress of LLMs, he has the bulls to go "nah this aint shyt"


since many people are asking me about the new math results from OpenAI, here is my take.
1. It uses symbolic AI (Lean, etc) in addition to LLMs which is what i said for years we would need to do; this this confirms what I actually said (as opposed to various fictitious misrepresentations that run rampant around here )
2. It still doesn’t mean they have AGI; the math stuff AFAIK does not generalize broadly, because you can’t use the same symbolic verification (and symbolic data augmentation techniques) in the open-ended real world.
So yes I do feel vindicated wrt to neurosymbolic AI but no the G in AGI (general) is not yet solved.
What I said in 2019 remains true: neurosymbolic AI is necessary but not sufficient; world models are also key.
Context: LLM resolved latest theoretical bound for matmul and gradient descent


its kinda bittersweet tbh

We’re releasing a broad range of new mathematical results produced by an internal frontier model.
We’ve been consulting with the independent Advisory Group on Mathematics and Artificial Intelligence at the Institute for Advanced Study, and we have drawn on their advice and public recommendations to inform how we release these results.
github.com/openai/math

I might be convinced that I am conscious
But how do i know if you are?
Do we just declare that as self evident or is there concrete evidence that we know for sure our fellow humans are conscious?

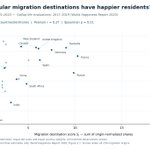
Ok i asked astra to do this. and basically
* everyone wants to move to US
* Finland is happiest but nobody wants to move there
* very slight correlation between how happy the residents are and how people want to move there.
* people want to move to russia very much (??)


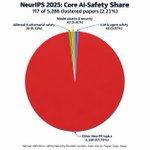
Btw number papers with topic of ai safety in neurips 2025, is 2.2%. So under this estimation slutcon has 5x more overlap to ai safety community than the AI community itself. AI Safety is extremely important and becoming more and more so, but this association has got to disappear.
Like im fairly certain its some group of people that associate themselves with ai safety that are not even professional researchers and permanently online larpers on lesswrong that are causing this.


Unfortunately the overlap you perceive on here I suspect is mostly incorrect. People are actively lying about slutcon. My best guess is 10% of the attendees were associated with x risk in some way? I'm sorry that people are causing a false perception for others.
That being said, slutcon super emphasizes consent, we have consent practices and teach a bunch of boundary respecting and handling rejection, and imo if more AI ppl went to slutcon I expect this would overall improve the quality of women's experiences with them.
Pubg is my third favorite game and I am consistently surprised they have such a big AI effort

🧵 It's finally here! The full technical report on PUBG Ally is finally on Arxiv: arxiv.org/abs/2609.29837
Sharing a few highlights in the thread!

I sometimes cant believe 18k people will have to watch Lavender eat his favorite thing, unwillingly.
Will probly intended as sarcasm but it might just be true....

??????????? ~40% improvement on whats already sub 1min record?

New historic NanoGPT record at 39.9s (-27.7s) from @DevenPzak , obliterating the prior record of 67.6s!
This record introduces a new paradigm of thinking to NanoGPT: instead of optimizing matmuls or adding more expressive operations, optimize at the individual flop level with incredibly clever engineering and ML judgement. If a flop is low value on a particular step, skip it.
Specifically:
-(~8s) Sampled softmax. If a token doesn’t appear in a batch, skip its lm_head fwd/bwd some fraction of the time.
-Sparse values. Only run an optimizer step for ngram embeddings that occurred in the batch. Set beta1 to zero to enable this. Beta2 is applied retroactively when the row is later used.
-Sparse updates. Only update ngram and value embeddings once every 4 steps instead of once every 2.
-Sparse communication. Shard the n-gram table across GPUs, and only pass the rows receiving updates on each step.
-Sparse optimizer states. For the n-gram table, reduce from 2 floats in Adam optimizer per param, to 1 float per 768 params.
-Hand-rolled flash attention for 64 dim heads.
There are several additions that add accuracy too:
-(~4s) EMA during last 300 steps, combined with lifting final_lr to 0.3 instead of 0.15.
-(~1s) A new optimizer, Anvil2, which expands muon via a second tracked momentum buffer, improves the ortho coefficients, and modifies the cautious weight decay application.
-A couple additional dynamic skip connections in the network.
The most striking consequence of the ‘flop aware paradigm’ is you can grow parameters arbitrarily large,
only limited by the available memory, since you can selectively choose how to expend flops on those parameters on each step. NanoGPT has kept active parameters below 124M, but total is unbounded, and has grown to 640M through embedding sparsity over the last year. This PR takes that to its logical conclusion on the 8xH100, scaling up to 65B sparse embedding parameters, which accounts for 25% of the PR’s gains. At frontier scale, where one is not bounded by an 8xH100, one could imagine where this paradigm could lead.
github.com/KellerJordan/modd…
As this was a very notable PR, I spoke with Deven for an hour to learn how he did it. Here’s his story on the changes: hyperstition.cc/training-nan…


Oh..

“An accumulation of facts is no more a science than a heap of stones is a house.” - Poincaré
LLMs are now proving results that have resisted mathematicians for decades. Finding interesting theorems without human guidance is a new bottleneck. We show that we can teach an LLM to do it!
TL;DR:
→ a quantitative notion of interestingness
→ 4.3× higher interestingness
→ a self-expanding discovery loop
[1/5]
