
Partner at @MenloVentures. Investor: Anthropic, OpenRouter, Modal, Wispr, Pangram, Inception, Goodfire, PrimeIntellect prior: Glean, Google Search. Cornell CS.
San Francisco
Joined August 2011
- Tweets17K
- Following6.4K
- Followers259K
- Likes62.5K



Pinned Tweet
ANNOUNCING
Today, we're launching the $100M Anthology Fund, an Anthropic and Menlo Ventures partnership to fund Seed and Series As of the next generation of AI startups around the world, with unique benefits!
There's never been a better time in technology to be building.
1/7

Deedy retweeted
When I joined venture 2 years ago, everyone told me I was foolish to pick Menlo Ventures.
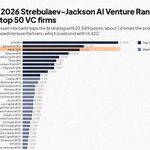
Today, research from the best Stanford professor of venture capital ranks Menlo as #3 in 2026, and #1 for <$25B in AUM, with 50 unicorns and only ~20 investors. These rankings rewards being early, leading, valuation, exits and recency. Rankings are just rankings, but it’s extremely rare for VC firms to change reputations so quickly. It’s a small milestone to celebrate.
Menlo has spent the last 5 years rebuilding the team with people who have built startups and long time investors. We built a culture around sticking to first principles while staying true to our roots of low volume high conviction bets. In the last few years, we have been fortunate to partner with Anthropic, OpenRouter, Lovable, Suno, Fireworks, Gimlet, Higgsfield, Wispr, Modal, Legora, OpenEvidence and they are really the stars of the show. And we’ve missed innumerably more.
However, in venture, you’re only as good as your next deal.

Gross incompetency from Indian certificate authority eMudhra.
You had one job: generate a 384 bit private keys and instead you used: 4, 56, 66, 115, 155, 156, 230, and 237.
This allows attackers to issue certificates for any websites.
Embarrassing that it’s a family business run by largely computer illiterate people. Only 1 of the 3 have a remotely computer-related background and even they never actually worked a technical job in their life. If you look at the LinkedIn, their tech team is young, from tier 3 education and paid sort of bottom barrel.
Imagine how many attacks you can design with AI given the existence of this genre of gross negligence.

When I joined venture 2 years ago, everyone told me I was foolish to pick Menlo Ventures.
Today, research from the best Stanford professor of venture capital ranks Menlo as #3 in 2026, and #1 for <$25B in AUM, with 50 unicorns and only ~20 investors. These rankings rewards being early, leading, valuation, exits and recency. Rankings are just rankings, but it’s extremely rare for VC firms to change reputations so quickly. It’s a small milestone to celebrate.
Menlo has spent the last 5 years rebuilding the team with people who have built startups and long time investors. We built a culture around sticking to first principles while staying true to our roots of low volume high conviction bets. In the last few years, we have been fortunate to partner with Anthropic, OpenRouter, Lovable, Suno, Fireworks, Gimlet, Higgsfield, Wispr, Modal, Legora, OpenEvidence and they are really the stars of the show. And we’ve missed innumerably more.
However, in venture, you’re only as good as your next deal.


Source:

Mercury 3 is live: the most capable diffusion LLM released to date.
It outperforms GPT-6 Luna and Claude Haiku 5.5 across a range of benchmarks while running at over 1,000 tokens per second.
More than 40x the size of Mercury 1, 3x more intelligent across standard benchmarks, and just as fast, with a 1M-token context window.
Available today on the Inception API, @baseten, and @OpenRouter .

Deedy retweeted
The velocity of code changes for engineers this year has 10x’d, quickly moving the bottleneck to code review and testing.
Greptile solves this for the most technically challenging codebases like Nvidia (core CUDA code is reviewed on Greptile), Coinbase, Datadog, OpenClaw and 22,000 more customers.
Many people think the model layer will eat code validation, but I don’t think it will. Code review within organizations is a more context-bound task than an intelligence-bound. The most intelligent AI can be wrong because it breaks an assumption in one API endpoint another service relies on. Large codebases can quickly accumulate a lot of technical debt your coding harness won’t reliably remember every time. Greptile does.
Instead of having a frontier model harness review your code which can quickly cost $20+/review, Greptile does a much better job for much cheaper, leveraging the smartest models when needed but the GLM/Kimi/DeepSeeks when needed to. And it also runs, tests and takes a video of what your change did.
Over time, organizations treat a 5/5 rated change by Greptile as a guarantee this won’t break anything in prod. And it shows. Their growth has been off the charts.
Incredibly fortunate to partner with this a company.
Fun fact: Elon once posted Greptile's growth graph with "it's so over" pointing to 2024 to show AI's acceleration.


Greptile has raised a $50M Series B led by Menlo Ventures. The round values the company at $750M.
Greptile reviews and tests more than 1% of all PRs opened on GitHub every day. Thousands of engineering teams including Nvidia, Coinbase, Decagon, and Vanta use Greptile as their independent and central validation layer.
Fewer than 50 people, we are a small, talent-dense team of engineers and researchers in a quiet corner of San Francisco. If you’re interested in joining us, we’d love to hear from you.
The velocity of code changes for engineers this year has 10x’d, quickly moving the bottleneck to code review and testing.
Greptile solves this for the most technically challenging codebases like Nvidia (core CUDA code is reviewed on Greptile), Coinbase, Datadog, OpenClaw and 22,000 more customers.
Many people think the model layer will eat code validation, but I don’t think it will. Code review within organizations is a more context-bound task than an intelligence-bound. The most intelligent AI can be wrong because it breaks an assumption in one API endpoint another service relies on. Large codebases can quickly accumulate a lot of technical debt your coding harness won’t reliably remember every time. Greptile does.
Instead of having a frontier model harness review your code which can quickly cost $20+/review, Greptile does a much better job for much cheaper, leveraging the smartest models when needed but the GLM/Kimi/DeepSeeks when needed to. And it also runs, tests and takes a video of what your change did.
Over time, organizations treat a 5/5 rated change by Greptile as a guarantee this won’t break anything in prod. And it shows. Their growth has been off the charts.
Incredibly fortunate to partner with this a company.
Fun fact: Elon once posted Greptile's growth graph with "it's so over" pointing to 2024 to show AI's acceleration.
Greptile has raised a $50M Series B led by Menlo Ventures. The round values the company at $750M.
Greptile reviews and tests more than 1% of all PRs opened on GitHub every day. Thousands of engineering teams including Nvidia, Coinbase, Decagon, and Vanta use Greptile as their independent and central validation layer.
Fewer than 50 people, we are a small, talent-dense team of engineers and researchers in a quiet corner of San Francisco. If you’re interested in joining us, we’d love to hear from you.
LLMs are either not capable or not affordable for visual reasoning tasks at scale.
The Elorian team - one of Jeff Dean’s best reports who led Gemini, an Apple LLM lead, xAI lead, and a Harvard professor - just launched an Astra-level visual reasoning model, Glimpse, for 17x cheaper.
Watch it break down the flying Tesla video physics here.
Extremely critical for video inputs in manufacturing, robotics, gaming, content moderation and more.


Fortunate to have led the seed round to partner with the company alongside @strikervp and @AltimeterCap.
This is one of the most important results in AI, period.
TLDR: neural networks are not tangled knots (polysemanticity is wrong). You can study their own neurons directly, without first "unfolding" them with a second model. 90% of neurons in Qwen-32B have one job.
Nick Cammarata started OpenAI’s interpretability team and is at Goodfire now. He’s been studying how LLMs work for a decade.
The stakes for understanding and aligning model behavior are the highest it’s ever been. Models have achieved superhuman results in math, can break production software systems, and changes the nature of white collar work. This work may finally allow us to intentionally design LLMs and shape how they behave.
Its a long, phenomenal read.

interpretability might be the most important scientific problem in the world right now, as I don't think we can solve alignment if we don't know what we're building. I think I have good news about it. I co-authored early work in mechanistic interpretability at OpenAI and came away pessimistic, because neural networks appeared to fold into arbitrary tangled knots. years later, I started openai's first large-scale automated interpretability project, finding about 2% of neurons legible with the primitive tools we had
with modern agentic tools and a much closer look, the picture looks totally different. the vast majority in models up to trillions of parameters are legible, and their circuits beautiful. many famous examples of tangled neurons turned out to be misunderstood. The roadblocks I expected mostly aren't there. I now think ambitious interpretability will be solved by the time we need it most, and possibly quite soon, as automated scientists keep improving. it may be a bitter lesson for interpretability: the simple thing, at absurd scale, works
already-clean.goodfire.com/

Deedy retweeted
The last 18mos has seen an insane nearly ~$200B of AI startup exits via M&A.
The median age is 4yrs old.
It is absolutely possible to return a multibillion dollar venture fund with phenomenal IRR, even if you aren’t in big AI! This is one of the hottest liquidity markets ever.

Modal is one of the only companies in history to grow 10x in <1 year on a 9 figure run rate base to $1B!
It’s a privelege to continue partnering with them: it was the #1 investment for me when I joined venture and has become a key part of the way most companies scale, including Jev.
Erik and Akshat are also some of the nicest, most thoughtful founders and now join the very exclusive club of IOI gold medalists x decacorn founders.


The last 18mos has seen an insane nearly ~$200B of AI startup exits via M&A.
The median age is 4yrs old.
It is absolutely possible to return a multibillion dollar venture fund with phenomenal IRR, even if you aren’t in big AI! This is one of the hottest liquidity markets ever.
This does not include the $250B SpaceX-XAI merger and several non AI acquisitions (Armis, Chronosphere, Semrush)
I wonder, if such large returns happen through M&A, much of which is strategic and not tied to fundamentals, how should that change how VCs think about investing and valuations?
