

Building LLMKube: K8s inference across NVIDIA, AMD, and Apple Silicon. Data stays yours. AI/ML Ops Director @ Ashley. Ham Radio: N7CPM
Gig Harbor, WA
Joined January 2018
- Tweets908
- Following632
- Followers358
- Likes2.9K






Pinned Tweet
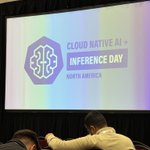
Badge in hand. Speaking at #KubeCon NA on Tuesday.
Turning Apple Silicon into Production GPU Nodes for LLM Inference on Kubernetes
Tue 11/10, 2:50 PM MT, Grand Ballroom H
CUDA vs Metal benchmarks, one operator across heterogeneous GPUs, and the real tradeoffs. Come say hi!


2
7
650
Same box. Same model. Same weights. Same settings. My local code reviewer just got 1.5x faster at writing and 3x faster at reading.
The only change: I moved my Strix Halo from Gufo v0.5.0 to v0.34.0. That's 29 releases and ~450 commits Gufo's contributors shipped in six weeks. I didn't write a line of it.
Real traffic, not a benchmark. Qwen3.8 Flash-Next (UD-Q4_K_XL) on a Ryzen AI Max+ 395 with 128GB, running as the code reviewer in my agent pipeline:
• Decode: ~31 → ~48 tok/s
• Prompt processing: ~530 → ~1,560 tok/s
• Model time per review (median): 12.3 → 8.9 min, while writing 11% more
Early numbers: the first 10 hours, 8 reviews on the new version against 62 the week before. A single replay hit 65 tok/s, but real reviews settle around 48, so 48 is the number I'm planning on.
On my side, the swap was two fields on one LLMKube InferenceService.
This is what excites me about building in the open. Someone else's work landed on hardware I already own, and the slowest step in my pipeline got faster in an afternoon. That's the kind of compounding I want LLMKube to be part of.
Gufo: github.com/gufo-org/gufo

2
1
246
LLMKube v0.10.18 is out. 7 community contributors helped build it, and 5 of them landed their first PR.
42 PRs merged, 23 issues closed, and 17 of those PRs came from the community.
The highlights:
→ First steps toward running the agent on Linux hosts
→ Multi-node members drop the page cache and set vm sysctls before boot
→ Per-InferenceService model cache size
→ 15 fixes, several of them on the Metal path
→ The one-Mac quickstart now lives on llmkube.com
Thank you to everyone who built it:
@chrisnuss (cnuss): Linux agent groundwork, router readiness, relay source IP
aditya-rai-5: quota admission, model file pattern warnings, engine adoption
cindy-pi: multi-node boot prep, a catalog context fix (first PR)
gabrielcosi: per-service cache size, PodMonitor relabelings (first PR)
IG-ABHINAV: llama-3.3-70b default context (first PR)
noahkhomer18: qwen-2.5-coder-7b default context (first PR)
vjsairam: the Metal EndpointSlice fix (first PR)
Release notes: github.com/defilantech/LLMKu…

5
259
LLMKube is serving a model from a Mac tonight without the Metal Agent.
The node is a Linux VM in Apple's container machine, joined to the rest of my cluster as an ordinary worker.
Lots more to come. This one has been a blast to hack on!

1
2
109


Apple Containers are really changing how I think about Macs and inference. Having a blast digging into them. How’s everybody else exploring this?
1
219
Chris Maher retweeted

Every one of you can help open source win.
If you care about open source, I need you to know that you can help and that you can make a difference.
A handful of people independently took on open source inference engineering and, through research, hillclimbing, mad scientist experiments, managed to drastically improve KV cache quality, MoE routing, perf, to the degree that several one-man teams are outperforming larger projects like vLLM, llama-cpp, and SGLang (@PeasantSmith @coldniko @Anbeeld @tbraun96 @no_stp_on_snek @Blackwellboy @coffeecup2020 , many others)
Sekai-1 is a 100m param model that scores #2 for its weight class and was trained on a single 16gb 5070 Ti (!) by one person.
YOU can compete. Start learning LLM concepts today. Read The Annotated Transformer over a weekend. Spend some spare time learning about the differences in attention mechanisms. Start hoarding your own training data. Get your feet wet. If you have access to 16gb of VRAM, start experimenting.
All it takes is one of you having a crazy idea that works well at this size and by the grace of God happens to scale. We will collectively BRUTE FORCE lab competition. By decreasing the barrier to entry we can will more labs into existence. There are so many gains on the table still, and believe me, it is possible for you to discover them.
We can't let intelligence be monopolized by these people. We need as many people learning and experimenting as possible because I know there are heroes among them that don't even know it.

#KubeCon NA 2026 is a wrap, and I'm heading home from Salt Lake City grateful and more fired up to build than ever.
The best part, as always, was the people: new connections who are working on the same hard problems, and old friends I got to reunite with.
Huge thanks to everyone who came to my talk on turning Apple Silicon into production GPU nodes for LLM inference on Kubernetes. Your questions were sharp, and they've given me a lot to build on for LLMKube.
If we started a conversation and didn't finish it, my DMs are open.
Thank you @CloudNativeFdn and everyone who made this week happen. See you at the next one!
1
6
223

Doing some hacking with my portable inference setup at the hotel before heading out to hang with the Zarf crew for a bit. This kubecon has been amazing!

1
1
79
Apple shared the next chapter of its open source container framework at KubeCon, including an experimental plugin that spins up Kubernetes clusters right on your Mac.
So I tried it with LLMKube on my M6 MacBook Pro. The operator installed in 26 seconds, the Mac joined its own cluster in 15, and phi-4-mini answered on the GPU.
How the pieces fit:
→ container cluster create gives you a local Kubernetes cluster, no Docker Desktop needed
→ LLMKube's operator runs inside it
→ the Metal agent runs natively on the same Mac and serves the model with Metal
→ pods reach it through a normal Kubernetes Service
The agent ran as is. The only change was one Helm flag: Apple's cluster has no default StorageClass, so the model cache goes per service.
Big thanks to the Apple container team for building this in the open. Excited to see where it goes, and to keep LLMKube working well alongside it.
github.com/defilantech/LLMKu…

5
9
397
Docs are up if you want to try this on your own Mac. The one-Mac quickstart now covers Apple’s container cluster too, including the one flag it needs (no default StorageClass, so --set modelCache.mode=perService): llmkube.com/docs/getting-sta…

1
11
My KubeCon demo yesterday ran from my homelab, 700 miles away.
On stage in Salt Lake City, one Mac joined my Kubernetes cluster in Gig Harbor, WA with a single command. Another served inference with Metal through the cluster, and when I pulled the plug on it mid-traffic, LLMKube's router failed over to a GB10 back in my lab.
That's the whole idea behind LLMKube for me: start with the hardware you already have, and it holds up on a KubeCon stage.
The link home was a pocket-sized @Ubiquiti UniFi Travel Router Long Range running Teleport. It put the stage on my home network and stayed up the whole talk. Thanks to the UniFi crew for making a 700-mile demo feel like it ran in the next room.
#KubeCon
7
217
Every PR one of my models writes for me gets a second pair of eyes before I see it: a read-only Qwen3.8-Flash-Next reviewer, served by LLMKube on an AMD Strix Halo.
Today, 9 minutes on a Go security bump: the code was clean, but it caught a wrong claim in the PR description.
My #kubecon presentation is over, so now it’s time to hit the LLMKube backlog like a beast 😄
1
7
277
Last-minute benchmarks on my M5 Max before my talk tomorrow: @ashxhart's TensorFold ran Qwen3.8-27B at 129 tok/s across 162K tokens of long output, 5x the same model with drafting off (24 tok/s). Not a 256-token demo: 30 runs, 2.7K to 8.2K tokens each, three sampling settings.
Decode tok/s by workload, from TensorFold's own per-request stats:
Agent rewriting a Go file: 231 (up to 359)
K8s YAML: 160
Go package with tests: 144
Code review: 104
Prose essay: 69
That's 3x on prose, 6-7x on code and YAML, and 14x when the output copies its input. Sampling barely moved it: 129 / 134 / 125 overall at temp 0, 0.7 and 1.0. Greedy drafted output was byte-identical to undrafted, so the speedup costs no quality.
I also checked the outputs. 36/36 K8s objects pass strict schema validation, and the Go file edit builds and passes LLMKube's tests. Weak spots: unit tests written in one shot, and invented numbers in the essay. Check those with any model. In opencode it fixed its own jq errors and shipped a working kubectl plugin in under 2 minutes.
Setup: Qwen3.8-27B MLX 4-bit, thinking off, with z-lab's DFlash2 drafter, single stream, 128 GB M5 Max, served by LLMKube's Metal agent. TensorFold 0.3.4.1, because my demo has been pinned since September; 1.2.5 is current. Short templated YAML still hits 227 tok/s; long answers settle lower. Happy to share the script.


