

AI systems, Local LLMs, Agents, GPUs I test models, read code, and post the numbers.
Seoul, KR
Joined September 2013
- Tweets2.5K
- Following180
- Followers1.3K
- Likes6.4K



Pinned Tweet
I happily picked up two used Nvidia Tesla P40 GPUs.
I knew the P40 was old and ridiculously overbuilt.
What I did not expect was how long the GPUs would become once the coolers were attached.
Tried putting them in the case.
Nope.
The cooler end would not fit.
I thought about it for about 10 seconds.
Turns out the bottleneck was not the human.
It was the case.
So I grabbed a hammer and pliers and destroyed the front section of the case.
After that both P40 GPUs fit perfectly.
Put the cover back on and you cannot even tell from the outside.
Apparently hardware fits if you hit it hard enough.
Good experience.


TensorFold v1.2.2
Qwen3.8-27B prompt processing is up to 42% faster on a GB10
On a GB10, Qwen3.8-27B EXL3 now processes prompts 38% to 42% faster across 2K to 64K tokens, going from 494 to 705 tok/s at 2K.
Generation gets 5% to 12% faster too, and the output tokens stay identical.
Qwen3.8-Flash-Next on an M5 Max generates 36% to 39% faster when its embeddings live on SSD, rising from 75.8 to 105.1 tok/s on code.
On a Ryzen AI Max, Qwen3.6-35B-A3B chat generates about 18% faster with draft tokens on.
NVIDIA's own NVFP4 checkpoint of Flash Next now runs split across two NVIDIA GPUs.
GLM-OCR runs natively on AMD GPUs, without Python or libtorch.
Qwen3.5-9B now runs on Macs.
A server built for one GPU comes out about 69% smaller on NVIDIA cards.
Broken checkpoint files are now rejected instead of crashing the loader.
github.com/ashhart/TensorFol…

SolidCraft v0.30.1
Keep up to eight renders per design and compare them with a slider
SolidCraft is open source parametric 3D CAD written in pure Rust. It runs on the desktop, in the browser, as a CLI, or as an MCP server that AI agents can drive.
The 0.30 release adds a render workspace that keeps up to eight finished renders per design for the session.
Compare puts the live view or one render against another, with a draggable divider and a swap button.
Large designs now open in the web app without freezing, with a progress card and a Cancel button.
Measure reports radius and diameter on fillet and spherical faces, and Sketch Offset can stack several evenly spaced copies.
Patch 0.30.1 fixes a black screen in the browser version and adds security fixes for agent chat, lock files and API keys.
Designs saved in 0.30.1 use format 48 and don't open in 0.30.0 or older.
github.com/tangency-labs/sol…


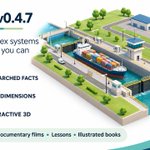
viz3d v0.4.7
Ask your agent how an airport turns a plane in 45 minutes and get a 3D world back
viz3d is a skill that turns hard-to-picture systems into live 3D apps, documentaries, lessons or embeds.
Layouts come from OpenStreetMap and models are built to real dimensions.
The latest releases add a book mode, an illustrated cutaway you orbit and fly into room by room.
A self review loop now checks the frames and fixes faults before you see the film.
There are seven modes and six looks. It installs in Claude Code, Codex or Cursor.
github.com/codepawl/viz3d


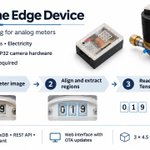
AI on the Edge Device
Read an old water, gas or power meter with a camera board under 10 EUR
AI on the Edge Device turns an ESP32 camera board into a meter reader.
It photographs the meter at set intervals, crops the digits and dials, and reads them with a TensorFlow Lite model on the board.
The value goes out over MQTT, into InfluxDB 1 or 2, or through a REST API. Home Assistant picks it up directly.
The device measures 3 x 4.5 x 2 cm. A web interface handles setup, alignment and firmware updates over the air, and there are printable cases for common meters.
The project started in 2020 and is still active. A recent change handles meters whose last digit rolls together with the first pointer.
github.com/jomjol/AI-on-the-…


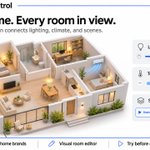
House Control v1.1.0
Your home as a live 3D model in the Mac menu bar, controlling real lights and ACs
Rooms, walls and furniture come from one JSON file. Lamps light the model like they light the room, and a running AC blows visible air.
Tap to toggle a light, drag to dim, or set an AC's mode and temperature.
It works with Smart Life, Home Assistant, Philips Hue and Apple Home in one home, and AI assistants can drive it over MCP.
v1.1.0 adds a Settings window and Open at Login on the Mac, a Control Center button on iOS 18, and fixes a crash on iOS 17.
github.com/0xProbabillity/ho…


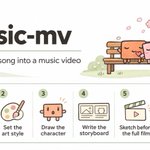
music-mv
Your coding agent makes a music video for a song, and every frame is drawn in code
Give it song.mp3 and it works in six steps: read the song, pick a style, draw the character, storyboard, sketch, then the full film. It stops for your OK at each step.
The skill measures BPM and beats, times the lyrics, and keeps the character in one code file so it stays on model.
Four native styles include 320x180 pixel art with a 24 color palette and pop-up paper.
A 1 to 1.5 minute video takes 7 to 10 hours, mostly review rounds. Works with Claude Code, Codex and similar agents.
github.com/Win-Hao/music-mv

Axolotl
Fine-tune large MoE models with YAML configs, then export straight to GGUF
Axolotl is a free, open source fine-tuning framework. October added Mistral Large 4 with merge aware NVFP4 LoRA and expert parallel training, and Reflection's Beam with QLoRA configs.
CPU-staged FSDP2 QLoRA loading lets you train models larger than one GPU's memory without a full quantized copy on every GPU.
Context parallelism now supports Ulysses and combined Ulysses and Ring attention with sample packing.
MixLoRA adds routed LoRA experts to dense models, and Dynamic Fine-Tuning is a new training option.
When you are done, axolotl export writes GGUF with optional quantization for llama.cpp and Ollama.
github.com/axolotl-ai-cloud/…

Null Motion v1.0.1
Watch a finished motion graphics ad play on top of the rough drafts it grew from, in sync
Each reference is split at its real scene cuts, and every section gets a plain HTML draft synced to the film frame by frame.
Export the whole breakdown as one MP4 at 24 Mbps with no dropped frames.
This release makes the first screen faster with WebP demos about 7x smaller, and adds drag to scrub, Space to pause and arrow keys to jump sections.
Node 22+, nothing to install, no API keys. MIT.
github.com/blixvip/NullMotio…

OfficeCLI
Let your agent create and edit Word, Excel and PowerPoint files, and see the result
OfficeCLI is a single binary with no Office install needed.
Agents can create, read and change text, formulas, charts and layout in .docx, .xlsx and .pptx files.
It renders each document to HTML or PNG, so the agent can look at the slide it just made and fix what is off.
A task that took 50 lines of Python and 3 libraries becomes one command.
Install it once and the skill is added to Claude Code, Cursor and Copilot automatically.
github.com/iOfficeAI/OfficeC…

Kilnframe v0.4.2
Plugin that animates your speech in Premiere and Resolve now renders 8K timelines at 4K
Mark a range, pick one of eleven styles, and Kilnframe turns your speech into code made animations with sound effects on your timeline.
Everything renders on your own computer.
In 0.4.2, inserts for 6K and 8K sequences are made at 4K and scaled to fill the frame.
8K has four times the pixels of 4K, so those renders are now much faster. A range past the end of your narration no longer fails.
github.com/erhanmeydan/kilnf…


CosmoEdge
Turn video AI models into camera apps on Sophon and Rockchip edge boxes
CosmoEdge is a C++ engine plus a web console for video analytics. You import models, wire them into scenes, set alarms and send events, and the same workflow runs on Sophon BM1688 and CV186X, Rockchip RK3576 and RV1126B, and x86.
Its own v1.1 report gives the numbers.
On BM1688 and RK3576, 8 channels ran for 72 hours at an average of about 5.1 FPS per task and passed.
A vision language model can watch cameras too. BM1688 passed at 0.1 FPS per channel up to 6 channels, and RK3576 up to 4.
The main branch adds ONVIF camera discovery and GB28181 device management.
github.com/cosmo-wander-ai/c…


CRAP w/ Gemma 4 E2B
AI now talks directly to CPUs, skipping source code.
CRAP is a fine tuned Gemma 4 E2B model that turns natural language into executable Linux x86_64 binaries.
No C, Rust, compiler, assembler, or linker.
The model generates machine code byte by byte.
For now, it is limited to simple programs.
github.com/matthewhaynesonli…

GLM-5.3-Flash BIZ
Run GLM-5.3-Flash as a single OpenAI compatible API across two or three DGX Spark systems using TensorFold and ConnectX-7.
Both TP=2 and TP=3 support a 1M token context with 4 and 8 concurrent streams.
Decode speeds reach 53.78 and 68.52 tok/s respectively.
The new Jammed XSFP4 checkpoint saves 6.58 GiB of memory per host at TP=2.
github.com/Bizuayeu/GLM-5.3-…

Project Maya v1.1.51
DeepSeek now uses every GPU's free VRAM in tensor parallel
In tensor parallel, each GPU now gets a share of DeepSeek's experts based on the room it has left, so no card sits with unused VRAM.
On the PCs it was measured on, about 10% more experts fit in VRAM and decode is up to 10% faster. Set DS4_TP_SHARES=off to keep the old even split.
With most experts in RAM on several GPUs, prompts from about 10K tokens read up to about 12% faster, while prompts near 8K are about 3% slower.
Stopping one answer no longer disturbs other conversations running at once.
The Qwen engine no longer fails every later request after a client abandons a prompt.
A dashboard page that lost its connection picks a long answer back up when you return.
DS4_RAM_MARGIN_GB sets how much system RAM DeepSeek leaves free, 8 GiB by default.
github.com/mw00/project-maya…
