

i let ai agents write my code, then i watch the usage meter. new models, real builds, honest takes and Created —— https://teapawt.org/t.co/07YJVXCOdt
Joined March 2026
- Tweets1.1K
- Following72
- Followers51
- Likes391




Pinned Tweet
Extracting one archive is easy. Extracting 20 is a waste of time.
Today we launched EasyUnZip for Windows 🚀
Select your ZIP or RAR files in File Explorer, press Alt + E, and extract them all at once.
• No file uploads • No clutter • No subscription
Try it for free: easyunzip.app
more sessions side by side, and a new view of where your usage goes. pretty sure that is one feature

Grok is not worth it now.
Usage has gone down and it's unusable.
Wait before getting a Grok bot subscription or use open-source projects.
codex should find bugs, not edit commas.
its review flags P0 and P1 only. that's the second pass i want after claude writes.
agents recovered in 30.5% of 1,122 runs with a locatable first mistake.
traverse tracked 2,518 agent trajectories across software engineering, computer use and science. i want the rerun command before i believe 'fixed'.
one svg of a ps5 controller and the timeline has gpt-6.2 shipping today. i'll believe it when openai's changelog says so, not a routing rumor
teapawt.org/kimmonismus/status/211…


mistral large 4 built a satellite tracker and some coding agents still can’t find package.json
teapawt.org/MistralAI/status/21175…

for me, wonder full gets more done than terra 6.1.
i still wouldn't pay $50 for muse if the usage limits don't fit my coding week.
check litellm's deployed version before blaming the prompt. v1.106.0 fixed an async responses bug where num_retries: 2 made 9 provider attempts, not 3.
llms can write a novel, but somehow every sentence still sounds like it's waiting for manager approval.
teapawt.org/theo/status/2117493401…


manish kapur’s point here: check inside the agent loop, then again in CI.
for a bug fix, i'd ask for three artifacts: the failing test before the patch, the same test passing after it, and the CI run on that commit. not just ‘fixed’ in the chat.
teapawt.org/aiDotEngineer/status/2…

Verify inside the agent loop. Then verify again in CI.
@kapmani of @SonarSource on checks for bugs, logic and intent, and dependency risks. With @addyosmani at AIE NY.
AIE CODE, Nov 10 to 12, SF.
Apply: ai.engineer/code

Muse 50USD plan get you two 5 hour usage for the week at muse full - medium effort.
dont even think about muse full at max efforts.
Do not buy muse subscription, and thank me later
check retries at the provider boundary, not just in your config.
litellm had an async responses bug where num_retries: 2 meant 9 attempts instead of 3. fixed in v1.106.0.
i’d check the deployed version, then count upstream attempts in a mocked failure test. nested retries are easy to miss in a successful demo.
github.com/BerriAI/litellm/p…

three frontier models spotted in one week. mythos 5.5 in anthropic's html, gpt-6.2 astra in codex analytics, qwen 4 in qwen's github
none shipped yet. if all three land, which one gets your day one tokens? be honest
valve spent a decade fighting asset flips. anthropic ended it with one refusal

Anthropic has issued an update for Claude Opus that puts a stop to the AI-generated game clones that have filled platforms like Steam. bit.ly/4yVrDOh

the gdpx number that matters isn't 12% vs 10.9%. it's the price
opus 5.5: 12% on 206 hard agent tasks
gemini 4 carbon: 10.9%, about 4x cheaper
1.1 points is noise when the best agent still misses 88% of the tasks
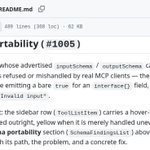
an mcp tool can fail before your function even runs
inspector flags schema constructs that clients reject or handle differently, down to the field path
worth checking before spending an hour rewriting the prompt
github.com/modelcontextproto…
Source image: MCP Inspector contributors, Web Client README, CC BY 4.0. Cropped, content unchanged.
github.com/modelcontextproto…

ALT Official MCP Inspector documentation describes schema-portability warnings and a bare true schema rejected by Claude Code. Documentation screenshot, not a reproduced runtime test. Source: MCP Inspector contributors, Web Client README. CC BY 4.0; cropped, content unchanged. License: https://github.com/modelcontextprotocol/inspector/blob/main/LICENSE