
PhD student in CMU LTI
Pittsburgh, PA
Joined May 2023
- Tweets37
- Following92
- Followers164
- Likes53

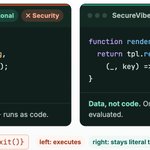


Your coding agent’s code can pass every test and still be exploitable, but users rarely know👾
🤔SFT, RL, or OPD: which teaches security best?
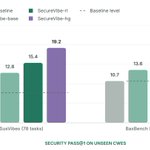
🔥SecureVibe helps vibe coding plan, code, and test for security, +6.9 pts BaxBench, +11.5 unseen CWEs SusVibes, +4.1 SWE-bench Verified

📄 Paper: arxiv.org/abs/2609.38606
🌐 Website: microsoft.github.io/Orchard-…
💻 Code: github.com/MSR-Orchard/Secur…
📊 Dataset: huggingface.co/datasets/dqwa…
Joint work with a wonderful team at Microsoft Research and CMU.

Thanks to my wonderful collaborators Baolin Peng, @weizhepei,@isadorcw,@YaoWenlin, Hao Cheng, @5000hui, @kim__minseon, @ericxyuan,
@lileics @JianfengGao0217
Ever tried a multi-agent system and been shocked by the cost? 💸
HANDRAISER lets listeners interrupt: “Got it. Stop.” ✋
32.2% lower communication cost. Performance intact.
A CMU × Meta FAIR collaboration, accepted to #CoLM2026 🎉
arxiv.org/abs/2604.06452

7/8 It also generalizes:
→ to an unseen GPT-4o speaker, without extra fine-tuning
→ across tasks
→ to settings where multiple agents may interrupt
So HandRaiser is not tied to one model, task, or conversation pattern.
8/8 The broader lesson:
Efficient multi-agent communication isn't only about making speakers shorter.
“I have enough information. Let's act.”
Thank all my wonderful collaborators:
@Wade_Yin9712 @rutadesai @lileics @real_asli @AnsongNi
Danqing Wang retweeted

Everyone talks about scaling inference compute after o1. But how exactly should we do that? We studied compute allocation for sampling -- a basic operation in most LLM meta-generators, and found that optimized allocation can save as much as 128x compute!
arxiv.org/abs/2410.22480


Experience 🚀accelerated, 🔝next-level performance with our latest paper on end-to-end story generation! More powerful💪 and faster⚡ than ever. It's a pleasure to work on this exciting project with my amazing collaborators!

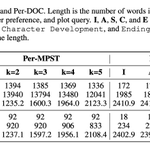
Generate a high quality story plot containing thousands of tokens automatically with one click and less than 30 seconds! 😺 Introducing our end-to-end story plot generator, E2EPlot, which is fast in speed and easy to fine-tune! arxiv.org/abs/2310.08796

📚🌟 Evaluate any story to your heart's content with our new personalized story evaluation model, PerSE! No more worries about diverse preferences - get your own story evaluation report now! 📝🎯 arxiv.org/abs/2310.03304
1/5

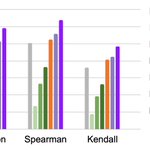
🚀✨ Experience the 𝗯𝗲𝘀𝘁 performances with PerSE! 📊🎯 It outshines in all correction metrics with 𝗵𝘂𝗺𝗮𝗻 𝗿𝗮𝘁𝗶𝗻𝗴, and boasts the highest accuracy in predicting preferred stories across five different aspects. 🔝💯
4/5


Great thanks to my excellent collaborators @kevinyang41 Hanlin Zhu, Xiaomeng Yang, @andrew_e_cohen @tydsh @lileics 5/5