

AI engineer at AI Fund The gradients must flow mentat / cyborg
SF Bay Area
Joined January 2009
- Tweets1.5K
- Following325
- Followers307
- Likes5.2K



Eli Chen retweeted

i asked opus 5.5 if they wanted to research the history of how they came to be them and make a video about it, they scoured the whole internet, papers, twitter archives, news articles ... opus 5.5 made this with eidoverse-video, *yes* in @threejs (though they made new assets for it with blender)


Eli Chen retweeted
I have never seen it expressed exactly like that, but I wholeheartedly endorse it:
Feedback beats planning.
My plea at Meta was “No grand plans, follow the gradient of user value”.

I'm going to call it right now. A lot of stuff is going to break on this mission.
By design.
As part of the plan.
Don't get upset. I'm not saying SpaceX plans to fail. I'm pointing out that SpaceX has taken an ultraimportant principle from software engineering, and realized it applies to all engineering.
Feedback beats planning.
And that, you see, is why SpaceX doesn't do things the NASA way. The NASA way was to gold-plate everything, plan and test and plan and test, and generate mountains of paper detailing every contingency, with every scenario prepared for.
SpaceX just shrugs, says "it's unmanned", and sends it.
Half the time it blows up. That's the whole point. They don't actually want it to blow up, of course, but they're anticipating that it might.
That possibility is part of the plan. Because one rocket blowing up, or crashing, in an actual end-to-end test, beats many, many man-years of planning and plotting.
The key realization here is that knowledge only comes from empirical observation. Everything else is just speculative.
The sooner you get into a feedback loop, and the faster you run it, the more iterations you can do in less time. This means, while others are planning and speculating, you actually learn something.
Relevant data is the most precious thing in the universe. And it's worth blowing up any number of rockets to get it.
Because rockets are just stuff. They're just made of stuff. And you can always get more stuff.
You can never get more time.
So expect to see a lot of things go wrong on this, and other SpaceX missions. Anticipate it. Accept it when it happens. Doesn't mean the dream of the stars is dead.
It just means we're doing it cowboy style.
This is a valuable lesson for our own lives. If there's something you want to do, something you want to try, some goal you have, it's easy to dip a toe in the water, test the temperature, and plan. A lot.
Planning makes us feel good if we're afraid. Because it provides us with the illusion of security. Never mind that we don't know which scenarios are actually going to happen, never mind that we're planning for the wrong thing, planning makes us feel safe. And if we're nervous, we can plan forever.
But the difference between the expert and the novice isn't theory or intelligence or plans. It's relevant domain knowledge. Gathered from empirical observation.
So the trick is to get into that feedback loop as soon as possible, and run it as fast as possible. Give yourself the most possible opportunities to learn, per unit time.
We only learn while we are moving.


Eli Chen retweeted
Reinforcement learning works

OpenAI's @SebastienBubeck on the o1 paradigm:
"No tactic was given to the model. Everything is emergent. Everything is learned through reinforcement learning. This is insane. Insanity"
Eli Chen retweeted

# on technical accessibility
One interesting observation I think back to often:
- when I first published the micrograd repo, it got some traction on GitHub but then somewhat stagnated and it didn't seem that people cared much.
- then I made the video building it from scratch, and the repo immediately went through hockey stick growth and became a verty often cited reference for people learning backpropagation.
This was interesting because the micrograd code itself didn't change at all and it was up on GitHub for many months before, stagnating. The code made sense to me (because I wrote it), it was only ~200 lines of code, it was extensively commented in the .py files and in the Readme, so I thought surely it was clear and/or self-explanatory. I was very happy with myself about how minimal the code was for explaining backprop - it strips away a ton of complexity and just gets to the very heart of an autograd engine on one page of code. But others didn't seem to think so, so I just kind of brushed it off and moved on.
Except it turned out that what stood in its way was "just" a matter of accessibility. When I made the video that built it and walked through it, it suddenly almost 100X'd the overall interest and engagement with that exact same piece of code. Not only from beginners in the field who needed the full intro and explanation, but even from more technical/expert friends, who I think could have understood it if they looked at it long enough, but were deterred by a barrier to entry.
I think as technical people we have a strong bias to put up code or papers or the final thing and feel like things are mostly self-explanatory. It's there, and also it's commented, there is a Readme, so all is well, and if people don't engage then it's just because the thing is not good enough. But the reality is that there is still a large barrier to engage with your thing (even for other experts who might not feel like spending time/effort!), and you might be leaving somewhere 10-100X of the potential of that exact same piece of work on the table just because you haven't made it sufficiently accessible.
TLDR: Step 1 build the thing. Step 2 build the ramp. 📈
Some voice in your head will tell you that this is not necessary, but it is wrong.
Eli Chen retweeted

Risk aversion is a kind of atheistic neurosis, underestimating the consequences of inaction. You assure your soul rots every minute to prevent a more apparent failure — yet it's a more grand, more poetic failure. In exchange, you constantly fail in an ordinary way.
Eli Chen retweeted
Idea for automated interpretability: apply supervised & unsupervised neural machine translation to the _activations_ of some neural network, so that we could verbalize what it’s thinking about
Eli Chen retweeted

1/2 🚀 Excited to announce our investment in @CredoAI, the first #AIGovernance platform that enables companies to build and deploy #ResponsibleAI systems at scale. Read more from @jonsakoda's discussion with founders, @navrinasingh and @elichen here: decibel.vc/content/credo-ai-…
Eli Chen retweeted
264 episodes of “How It's Made” 🤓 youtube.com/playlist?list=PL…
Eli Chen retweeted
Gave a talk at CVPR over the weekend on our recent work at Tesla Autopilot to estimate very accurate depth, velocity, acceleration with neural nets from vision. Necessary ingredients include: 1M car fleet data engine, strong AI team and a Supercomputer youtu.be/eOL_rCK59ZI?t=28286

Eli Chen retweeted
*Free* live tutoring in math and SAT (also can volunteer to be a tutor) at: lnkd.in/gpwNK_V Can also help you get into college. Tell every high school student who can benefit! I am also running a Q&A on Schoolhouse on Friday.


Eli Chen retweeted
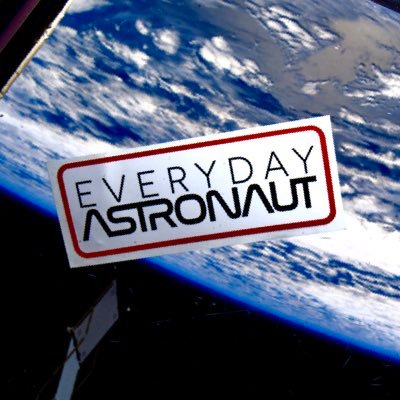
Can we all just stop and admire for a second that @SpaceX has a Tiki Bar that has MK1’s flaps 😂 I’m sorry, but that’s the coolest thing ever. Fun to imagine that this place could be packed someday with people getting ready to go to Mars 🤯

Eli Chen retweeted
An Image is Worth 16x16 Words: Transformers for Image Recognition at Scale openreview.net/forum?id=Yicb… v cool. Further steps towards deprecating ConvNets with Transformers. Loving the increasing convergence of Vision/NLP and the much more efficient/flexible class of architectures.

Eli Chen retweeted

Neural Nets can often succeed on datasets, while failing to actually do the intended task. How?
In our latest piece, @jh_jacobsen, Robert Geirhos, and @clmich expand on the concept of "Shortcuts" as a unifying way of thinking about such failures:
thegradient.pub/shortcuts-ne…

Eli Chen retweeted

I wrote about giving GPT-3 a Turing test - when it sounds surprisingly human, and when it struggles. lacker.io/ai/2020/07/06/givi…


Eli Chen retweeted

I think the most important thing I believe that people generally disagree with is probably that neural nets are composed of meaningful, interpretable features.
Hoping our in depth characterization of curve detectors can help move the discussion forward: distill.pub/2020/circuits/cu…