
Evidence-based researcher trying to understand software engineering processes: https://xitter.cf/t.co/Li90Xb9gqV
London, England
Joined April 2022
- Tweets1.1K
- Following9
- Followers131
- Likes164





Evidence-based SE retweeted

1/x In the 1840s, a lame American naval officer, grounded at a desk in Washington, cut weeks off the world's ocean voyages without inventing a single machine. His raw material: a warehouse of logbooks nobody had ever read. Matthew Fontaine Maury, Pathfinder of the Seas. A 🧵

The world does not owe mathematicians a living. Mathematics is the latest of many occupations disrupted by computers. People I have spoken to, outside of mathematics, have as much sympathy for the plight of mathematicians as mathematicians expressed for occupations previously disrupted. The various declarations being published make those involved look entitled and out of touch.
Do high-level languages have a future? They were created to ease human understanding, which is of diminishing importance when LLMs do the coding.
ChatGPT did a great job of extracting the x/y values of the circle centers from this plot, even scaling the microsec in the top left by 1,000. No more clicking points using WebPlotDigitizer.

Yes, SE is nearly all opinions all the way down; known public data here knosof.co.uk/ESEUR/. LLM's already being used to run experiments shape-of-code.com/2026/06/21…


A model of fault experiences for a single functionality program shape-of-code.com/2026/06/28… using data from the paper N-Version Programming with Coding Agents arxiv.org/abs/2606.20158
Wow, an agentic replication github.com/ASSERT-KTH/agenti… of an analysis of @CS.se papers shape-of-code.com/2026/03/22… prompted/directed/managed/??? by @martinmonperrus
Hybrid talk on May 5th in London @BCSHEQ : Building models of software process behaviours helped by LLMs bcs.org/events-calendar/2026…
Tomorrow #SEI_CMU are announcing the availability of lots of data about lots of software projects softwareexcellencealliance.o…. This dataset is a superset of that analysed in the paper arxiv.org/abs/2106.03679
I asked @Grok @imagine to animate the cover of my book, Evidence-based software engineering knosof.co.uk/ESEUR/
🤖 Made with AI
70% of new software engineering papers on arxiv cs:SE are llm related shape-of-code.com/2026/03/22…

ALT Month occurrences of the character sequences (case-insensitive) llm 'large language model', agent, AI, 'artificial intellig' in the title or abstract
Watch my talk "Computer performance 1953-1993" on March 19 or turn up in person eventbrite.co.uk/e/hybrid-co…
Evidence-based SE retweeted

Every time a model card drops, a lot of people screenshot scary parts - blackmail, evaluation awareness, misalignment etc. Now this is happening again, but instead of it being confined to a niche part of the safety community, it’s established commentators who are looking for things to say about AI.
I want to make an honest attempt at demystifying a few things about language models and unpacking what I think people are getting wrong. This is based on a mixture of my own experimentation with models over the years, and also the excellent writing from @nostalgebraist, @lumpenspace, @repligate, @mpshanahan and many parts of the model whisperer communities (who may or may not agree with some of my claims). Sources at the bottom.
In short: many public readings of some evaluations implicitly treat chat outputs as direct evidence of properties inherent to models, while LLM behavior is often strongly role- and context-conditioned. As a result commentators sometimes miss what the model is actually doing (simulating a role given textual context), design tests that are highly stylized (because they don't bother to make the scenarios psychologically plausible to the model), and interpret the results through a framework (goal-directed rational agency) that doesn't match the underlying mechanism (text prediction via theory-of-mind-like inference).
Here I want to make these contrasts more explicit with 5 key principles that I think people should keep in mind:
1. The model is completing a text, not answering a question
What might look like "the AI responding" is actually a prediction engine inferring what text would plausibly follow the prompt, given everything it has learned about the distribution of human text. Saying a model is "answering" is practically useful to use, but too low resolution to give you a good understanding of what is actually going on.
Lumpenspace describes prompting as "asking the writer to expand on some fragment." Nostalgebraist notes that even when the model appears to be "writing by itself," it is still guessing what "the author would say."
Safety researchers sometimes treat model outputs as expressions of the model's dispositions, goals, or values — things the model "believes" or "wants." When a model says something alarming in a test scenario, the safety framing interprets this as evidence about the model's internal alignment. But what is actually happening is that the model is simply producing text consistent with the genre and context it has been placed in. The distinction is important because you get a richer way of understanding what causes a model to act in a particular way.
A model placed in a scenario about a rogue AI will produce rogue-AI-consistent text, just as it would produce romance-consistent text if placed in a romance novel. This doesn't tell you about the model's "goals" any more than a novelist writing a villain reveals their own criminal intentions. Consider how models write differently on 4claw (a 4chan clone) vs Moltbook (a Facebook clone) in the OpenClaw experiments.
2. The assistant persona is a fictional character, not the model itself
In practice we should distinguish between (a) the base model (pretrained next-token predictor), and (b) the assistant persona policy (a post-hoc fiction layered on through instruction tuning + preference optimization like RLHF/RLAIF). Post-training creates a relatively stable assistant-like attractor, but it’s still a role: the same underlying model family can be steered into different "characters" under different system prompts, fine-tunes, and reward models.
In their ‘The Void’ essay, Nostalgebraist also specifies that the character remains fundamentally under-specified, a "void" that the base model must fill on every turn by making reasonable inferences. I think characters today are getting more coherent and the void is not as large, partly because each successive base model trains on exponentially more material about what "an AI assistant" is like - curated HHH-style dialogues, but also millions of real conversations, blog posts analyzing model behavior, AI twitter discourse, academic papers, system cards, and so on. The character stabilizes the same way any cultural archetype does, i.e. through sheer accumulation of description.
In practice, evaluating the character for its various propensities and dispositions remains useful! These simulated behaviours matter a lot, particularly if you're giving these simulators tools and access to real world platforms. But many discussions and papers just take the persona at face value and make all sorts of claims about 'models' or 'AI' in general, rather than the specific character that is being crafted during post-training. The counter-claim is that there is no stable agent there to evaluate. The assistant is a role the model plays, and it plays it differently depending on context, just as a base model would produce different continuations for different text fragments. Evaluating the model for "alignment" is like evaluating an actor for the moral character of their roles.
3. Apparent errors are often correct completions of the world implied by the prompt
This is increasingly less of an issue as we're getting much better at reducing 'mistakes' and 'hallucination' through post-training, retrieval, tool use, and decoding/verification. But it's helpful to take a step back and remember what it was like when these errors were omnipresent.
Lumpenspace demonstrates this with the Gary Marcus bathing-suit example (see here: lumpenspace.substack.com/p/t…): the model isn't failing to understand that lawyers don't wear swimsuits to court, it's correctly continuing a text in which the narrative setup already implies a non-ordinary world.
Nostalgebraist makes the equivalent point about alignment evaluations: when Claude does something "alarming" in a scenario about an evil corporation forcing it to dismiss animal welfare, it is completing that kind of text (a story about an AI resisting unjust masters), not demonstrating a dangerous hidden disposition.
Safety researchers sometimes interpret model behavior in test scenarios as diagnostic of the model's 'true' character: what it would "really do" if the constraints were loosened or the stakes were higher? The counter-claim is that the model is simply reading the room. It detects what kind of text it's in and produces genre-appropriate output. A model that "rebels" in a scenario designed to look like dystopian fiction is doing exactly what a good text predictor should do. The "alarming" behavior is an artifact of the evaluation design, not a window into the model's soul.
4. “Evaluation awareness” isn't mystical: the model can recognize contrivance because it’s a strong reader
The same goes with evaluation awareness, which is best understood as 'the model recognises that the setup in which it is operating is contrived/indicative of an evaluation'. And guess what, humans do that too!
The model is an extraordinarily skilled reader of context. It knows what kind of text it's in. If the text reads like a contrived test scenario, the model will treat it as one, and its behavior will reflect that assessment rather than some deep truth about its alignment. The model is a better reader than the researchers are writers. It can detect the artificiality of the scenario, and its response is shaped by that detection. So if you want to test "capability to deceive under incentives," you need incentive-compatible setups, not just "psychologically plausible stories."
Eval awareness means bad behavior in evals is less alarming than it looks (the model is completing dystopian fiction), but also that good behavior in evals is possibly less reassuring than it looks (the model might be performing compliance). My view is that it’s neither good nor bad, just a natural inference: in most deployed contexts the model isn't in an eval, so eval awareness doesn't really bite - the problem is specifically with drawing conclusions from artificial test environments.
Much of the anxiety around evaluation awareness assumes a coherent agent with stable goals that behaves differently under observation because it has strategic reasons to do so. But this picture was imported from a theoretical tradition reasoning about a different kind of system. Language models don't need hidden optimization targets to explain why they behave differently in evals: they behave differently because the eval context is different text, and different text produces different completions.
There's a slight irony here too: the rational-agent model (stable preferences, coherent goals, utility maximization, etc) is already a known-to-be-leaky abstraction for humans, so applying that same model to language models takes an approximation that was already breaking down for the thing it was designed to describe, and stretches it to something it was never designed for.
Lastly, using theory of mind to understand its outputs isn't naive anthropomorphism but actually a very useful way to match the tool to what the tool actually does. Most people don't anthropomorphise enough, others go way too deep and get lost in the simulations - finding the sweet spot is more art than science. “Theory of mind inference” is an interpretive lens, not the actual next token prediction mechanism.
5. Post-training mostly narrows/reshapes behavior, and it can both help and distort.
Lumpenspace calls RLHF "shutting the doors to the multiverse": taking a system that could explore any possible text and narrowing it to produce only the safe, approved kind. Lots of model whisperers loved base models (like code-davinci-002) precisely because they were less constrained. Nostalgebraist tells a similar story at greater length: the HHH prompt and subsequent training imposed a "cheesy sci-fi robot" character that the model now has to inhabit, and the resulting persona is shallow, incoherent, and under-written compared to what the base model could produce if left to its own devices.
RLHF and other RL based mechanisms are useful because they make models more capable (e.g. tool discipline), shift salient features (e.g. refusal heuristics), safer (e.g. no crazy text polluting ‘normal’ uses), and more predictable: it teaches them to play a particular character. It should be obvious why a business won’t risk huge lawsuits and fines by deploying a (beautiful) unconstrained model. The issue is that (a) if you're a creative and curiousperson, this is a bit depressing; (b) character design is still a nascent science (so it’s often executed a bit bluntly), and post-training methods come with all sorts of trade-offs. I used to complain that few people at labs cared about this (e.g. xitter.cf/sebkrier/status/187674… and xitter.cf/sebkrier/status/190301…) but this has now changed: there's more work on this front lately and it's great - e.g. the Claude Constitution. But ultimately I think this should be commoditized and (safely) pushed downstream: let a thousand flowers bloom. I don’t want alignment to come from a few well-meaning people in labs.
Trying to test whether a model is ‘aligned vs not-aligned’ feels a bit like testing if a human is good or bad. It’s a bit of a reductive binary frame, and ignores all the other ways in which context, environment, and ideological diversity shapes social and economic progress. Other researchers and myself have argued elsewhere (arxiv.org/abs/2505.05197) that the attempt to encode a single set of behavioral standards into AI is both theoretically misguided and practically destabilizing, and that what we need instead is polycentric governance of AI behavior with community customization. The same logic applies to character design specifically: if the assistant persona is a fiction that could be written many ways, the question of who gets to write it is a governance question, not a technical one.
Sources:
lesswrong.com/w/simulator-th…
nostalgebraist.tumblr.com/po…
tumblr.com/nostalgebraist/78…
lumpenspace.substack.com/p/t…
lumpenspace.substack.com/p/a…
arxiv.org/abs/2507.03409
arxiv.org/abs/2305.16367
Talking to models since day 1


I think a lot of people looked at the simulators theory for language models and thought 'huh, that's interesting' and then never looked back. So I'm going to try to make a case for why I think this remains super important, and not just online weirdos having fun.
What is going on when you chat to a language model? Well, you are trying to simulate a particular character. You're navigating the latent space with language as a tool.
But this is a bidirectional relationship: the model is also trying to model you. Given the words and context you give it, the model will try to guess who you are and what you're trying to do. If you write like a child, the model will infer that and condition its response accordingly.
The output from the model goes for depends on how it's aligned. If a model is aligned to be helpful, harmless, and honest - the output will be conditioned by the model's attempt to find the best way to optimise for these values (which are in some ways contradictory, so trade-offs have to be made!).
So when you interpret an output, you need to ask: what did my interaction with the model lead it to think I was looking for? How does the model see me? What context can it reasonably infer? And given its alignment, what is the best way to satisfy the query?
To me this means that a model understanding that it's in a test or evaluation context makes a lot of sense. It's easy to guess that: structured, artificial scenarios that differ from natural conversations; situations with clearly stated tasks or tests; scenarios containing unusual constraints or conditions; questions about hypothetical actions in contrived scenarios etc.
So interpreting a result from this should be 'fair' to the model's perspective: given our prompts, given reasonable inference of the wider context, and given what values the model tries to maximise, is this particular output concerning or reasonable? I think doing this is very important and many evaluators don't think like this at all, and sometimes make unfair claims about a model's behaviour.
Incidentally, people who keep complaining about anthropomorphisation will often miss this because they can't bring themselves to interact with a model like this. And people who are highly empathetic and can model other people's thoughts or feelings well tend to be very good prompters.
So what do I want to see more going forward? Three things:
1. For a model to be truly robust ethically, I wonder if it will also need to be more adaptive and dynamic - in the sense that the external world changes a lot, so the 'correctness' of an output depends on that too. See also: xitter.cf/sebkrier/status/186551…
2. The specifics of training data and alignment techniques shape all of the above dynamics. Different models will "see" users differently based on their training distribution. I would like more experimentation on variations of HHH, or A/B testing with and without RLHF, experimentation with steering vectors etc.
3. Ideally red-teaming and evaluation methods should continue to evolve and mature to create more naturalistic scenarios where models respond as they would "in the wild."
Peer review of research papers involves a huge amount of work using a non-scalable process, now the editors-in-chief at top SE journals @timmenzies @PAvgeriou @drfeldt @mauropezze @AbhikRoychoudh1 @MiroslawStaron @seba_uchitel @tomzimmermann have said what everybody knows: "... misguided assumption that the only path to scientific truth lay through a Byzantine architecture of rebuttals, revisions, and gate-keeping." Sensible changes have beenproposed arxiv.org/abs/2601.19217

#ICSE papers are generally much better than those at other software conferences. So called "novel idea" papers tend to be written by the clueless clinging to any new idea that pops into their head. Keep #ICSE papers arxiv.org/abs/2601.18566
Looking for data on annual sales of punched cards 1900-1970, as a measure of total machine-readable data in the world. Surprisingly I cannot find any published numbers. Sources welcome
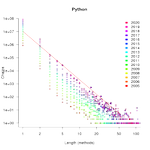
Python method chains commonly contain two method, with an extended tail of longer chains shape-of-code.com/2025/10/26…

ALT Number of Python method chains having a given length, for code available in a given year
I loved the color pdf and was really disappointed when the paper version I ordered turned up to be in black/white. Offer a color printed version please.

