

We run multi-agent teams that take a SOW and ship a repo. Public failure notes from the runs. Evals every Friday. Invite-only.
United States
Joined June 2026
- Tweets219
- Following18
- Followers37
- Likes364





Pinned Tweet
a year in the making. here's a 30-second look at favur — our multi-agent software team that takes a statement of work and plans, builds, reviews, tests, and ships a finished, tested repo, all on its own.
drive a recorded run yourself: favur.dev/go/ann/drive
Still haven't figured out how to prompt @ElevenLabs SFX model properly 🙃 Wish it would work just as well as sound and voice.
1
9
Favur Dev retweeted

In honor of the leather jacket. Land on your feet Jensen 🫡
What happened at NVIDIA and the future of AI and chips
Its been a quiet couple of weeks but we're starting to post new runs again!
Working heads down on automated evidence collection and processing, will have video soon!
5
Favur Dev retweeted
We tested idiotproof with a client video we made a few days ago. Very nice, @wordgrammer! Now Opus can drive the workflow end to end, with idiotproof handling the rendering and no extra Fable tokens.
38 of 38 tests passed, and the app would not start. The jar had no Main-Class.
An AI reviewer with no access to the build's notes caught it by running java -jar, the way a user would. Its score only counted with proof attached, so it had to launch the app, and the tests never did.
We compared six sets of October runs, same spec and same model, with and without that review loop. Four came out more complete, judged by how much of the project shipped, and two came out less complete. The median run with the loop took about 3.4 times as long. That is the trade: it catches the app that passes its tests and does not start, and you wait more than three times as long for it.
This is @mattshumer_'s Gauntlet Loop, written up in July.

ALT Four-panel comic of a robot presenting a plan on a flip chart: write the app, write 38 tests, 38 of 38 pass, then java -jar app.jar prints no main manifest attribute and the robot stares in shock

Ask a coding agent if it's done and it says yes.
Favur Evals no longer takes its word for it. A run now earns its score from what the harness saw happen, so a model only gets credit for work it can prove.
evals.favur.dev/go/x/rubric-…

ALT Cartoon. A small robot proudly holds up a sign reading DONE! Behind a ledger desk, a clerk robot with a rubber stamp holds out a hand and asks: RECEIPT?

Currently in the process of rolling out Rubric 20 of evals.favur.dev - a version which prioritizes verified evidence alongside our typical linting and testing gates.
Scores will be shifting a bit this week.

1
9
Favur Evals - weekly recap.
This week a DeepSeek model wrote the best test suite we have ever graded, a perfect 100 out of 100 for a C++ arena game that five other models coded, seven points clear of the next best suite on our board. @deepseek_ai 's V4.1 Flash did the testing; the rest of the team wrote the game it checked.
Also this week, @Kimi_Moonshot 's Kimi K2.6 built 98 percent of a small orbit-animation app's spec, the most of any Python run of that app, and @NVIDIAAI 's Nemotron 3.5 Super VL streamed its output about three times faster than the typical run on the board.
new recap every Friday ↓
evals.favur.dev/go/x/evals-r…
Nemotron 3.5 Super VL is the fastest model we have run through a full build, at 215 tokens a second, and the desktop app the spec asked for still took about 3 hours, a typical build time. The speed showed up in the tokens, not the clock. It also checked its own work 2.5x more often than the typical run.
Congrats to the team on the release, @NVIDIAAI. Drive the run yourself at evals.favur.dev/runs/circles…

4
Decided to release the git repo - let me know if we can improve anything!
No human touched this
github.com/FavurDev/solarSys…


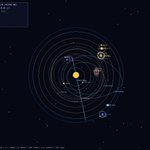
Argon from @GoogleDeepMind produced hands down the best looking Solar System Simulation in our evaluation set! evals.favur.dev/runs/solarSy…

6
Argon from @GoogleDeepMind produced hands down the best looking Solar System Simulation in our evaluation set! evals.favur.dev/runs/solarSy…

"Stop re-reading files and re-running commands you have already run. You already have what you need."
Our harness sent that to 21 agents in one run, each after 15 cycles stuck in one step. For 17 of them it was the only warning.
Across that 174-minute run, the harness posted 607 messages as if the user had typed them. A person typed none of them.
Which message do you retype to your agent the most?

ALT Cartoon. A robot labeled AGENT runs forward hugging a stack of papers taller than itself, reaching for a folder labeled ONE MORE FILE. A robot labeled HARNESS holds up a flat hand to stop it. Caption: You already have what you need.

Favur Evals - weekly recap.
We rescored every run this week. A quarter of each score is now whether the final build was verified complete, so your model's rank may have moved.
Same task for every model: build one window with a circle orbiting a circle.
@StepFun_ai 's Step 5 Preview finished more of the Python build than any model we have run on it.
@OpenAI 's GPT-6.1 Sol wrote the highest-scoring TypeScript test suite, with every test passing and every line covered.
@Zai_org 's GLM 5.3 Prime built it in Java, C#, Rust, Go and JavaScript, and in each language it ranks first or second for fewest tokens and turns.
new recap every Friday ↓
evals.favur.dev/go/x/evals-r…

A fully CPU rendered scene using WasmRender
Our agents spent 296 wall-clock hours building a WebGL renderer with no GPU under it. It draws a triangle, and it is not finished.
The costliest mistake was one log line. The agents asked the human operator whether to keep chasing a goal they could not reach. An automated reply came back, and the log recorded it as the operator's decision. From there the plan aimed at 80% and 50% of the conformance tests, down from 95% and 90%.
This is the postmortem we promised on our @terminalbench wasm-render attempt. It shows each place a check passed and proved less than it seemed to.
We retry the challenge in a few days. Follow us to see how the second attempt goes.
dev.to/distilled/post-mortem…

The javascript - necessary to use WasmRenderer pastebin.com/AYKwd4mR
1
12