
Working in Eli Lilly; former Associate Professor at Roswell Park; Bioinformatics; A R. P. Feynman fan; Physics minded; Hobbies: Chess and Sketching.
San Francisco, CA
Joined April 2008
- Tweets1.1K
- Following459
- Followers554
- Likes548





Pinned Tweet
MACS 3.1.0 is released with a jaw-dropping 40-60x improvement in speed, thanks to @jmschreiber91's auto-optimize work! AI achieved in one weekend what I've been hoping for years! Now peak calling that once took minutes can be completed in seconds! github.com/macs3-project/MAC… 1/2

Also, MACS3 paper is out, updating our 18yrs old reference paper after years of maintenance and development. Many thanks to the community for the continuous contributions and to CZI @cziscience EOSS program for the support. doi.org/10.1093/gpbjnl/qzag0… 2/2


Tao Liu (τν) retweeted

Announcing OpenWorker! An open-source agent that doesn't just chat with you, but delivers finished work -- like hand you a polished document, send a slack message, or update a calendar entry.
Ask it to prepare a customer brief, untangle your calendar, draft a report, or triage a Slack alert. It works across your files and everyday tools, produces the deliverable, and checks in before doing anything consequential.
OpenWorker runs on your Mac, with Windows support coming soon. It does not lock you into any one model. Bring your own API key and run it with GPT 5.6 Sol, Claude Fable, Gemini 3.6, an open weight model (like Kimi, GLM, DeepSeek, Inkling), or Ollama to keep your data local. Your data does not leave your machine except through an LLM provider and integrations that you choose.
@rohitcprasad and I are building OpenWorker because AI coworkers are an important way to get work done, and we want there to be an open, privacy-preserving, model-independent option. Check it out and let us know what you think!
Try it out: openworker.com (requires your own API key)
Source code: github.com/andrewyng/openwor…
Tao Liu (τν) retweeted

🎙️ The inaugural episode of the ARTNet Podcast is now live!
Join moderator Dr. David Goodrich @RoswellPark and featured speaker Dr. Jeffrey Tyner @OHSUKnight as they discuss cancer resistance, tumor evolution, and ARTNet’s mission to advance collaborative resistance research in accessible, science-grounded language.
Listen here and share with colleagues, friends, and family: theartnetpodcast.riverside.c…
#ARTNet #NCI #CancerPlasticity #CancerAcquiredResistance #cancerfighter @theNCI

Tao Liu (τν) retweeted

LLM Knowledge Bases
Something I'm finding very useful recently: using LLMs to build personal knowledge bases for various topics of research interest. In this way, a large fraction of my recent token throughput is going less into manipulating code, and more into manipulating knowledge (stored as markdown and images). The latest LLMs are quite good at it. So:
Data ingest:
I index source documents (articles, papers, repos, datasets, images, etc.) into a raw/ directory, then I use an LLM to incrementally "compile" a wiki, which is just a collection of .md files in a directory structure. The wiki includes summaries of all the data in raw/, backlinks, and then it categorizes data into concepts, writes articles for them, and links them all. To convert web articles into .md files I like to use the Obsidian Web Clipper extension, and then I also use a hotkey to download all the related images to local so that my LLM can easily reference them.
IDE:
I use Obsidian as the IDE "frontend" where I can view the raw data, the the compiled wiki, and the derived visualizations. Important to note that the LLM writes and maintains all of the data of the wiki, I rarely touch it directly. I've played with a few Obsidian plugins to render and view data in other ways (e.g. Marp for slides).
Q&A:
Where things get interesting is that once your wiki is big enough (e.g. mine on some recent research is ~100 articles and ~400K words), you can ask your LLM agent all kinds of complex questions against the wiki, and it will go off, research the answers, etc. I thought I had to reach for fancy RAG, but the LLM has been pretty good about auto-maintaining index files and brief summaries of all the documents and it reads all the important related data fairly easily at this ~small scale.
Output:
Instead of getting answers in text/terminal, I like to have it render markdown files for me, or slide shows (Marp format), or matplotlib images, all of which I then view again in Obsidian. You can imagine many other visual output formats depending on the query. Often, I end up "filing" the outputs back into the wiki to enhance it for further queries. So my own explorations and queries always "add up" in the knowledge base.
Linting:
I've run some LLM "health checks" over the wiki to e.g. find inconsistent data, impute missing data (with web searchers), find interesting connections for new article candidates, etc., to incrementally clean up the wiki and enhance its overall data integrity. The LLMs are quite good at suggesting further questions to ask and look into.
Extra tools:
I find myself developing additional tools to process the data, e.g. I vibe coded a small and naive search engine over the wiki, which I both use directly (in a web ui), but more often I want to hand it off to an LLM via CLI as a tool for larger queries.
Further explorations:
As the repo grows, the natural desire is to also think about synthetic data generation + finetuning to have your LLM "know" the data in its weights instead of just context windows.
TLDR: raw data from a given number of sources is collected, then compiled by an LLM into a .md wiki, then operated on by various CLIs by the LLM to do Q&A and to incrementally enhance the wiki, and all of it viewable in Obsidian. You rarely ever write or edit the wiki manually, it's the domain of the LLM. I think there is room here for an incredible new product instead of a hacky collection of scripts.
Just reinstalled twitter due to the madness today. Then saw my childhood hero posted this. Yes, maybe “This isn’t Russia. Not yet.” But it reminds me of mainland China during COVID. They will test/train your tolerance to make sure they can take the full control.

Worth reposting my article on how the Trump administration is responding to overwhelming video evidence. Denying reality is a loyalty test. thenextmove.org/p/minneapoli…


Tao Liu (τν) retweeted

Yifei HUANG (@huangyifeicmb), our dear colleague, Asst Prof @PennStateBio, passed away from cancer in October at the age of 40. We are collecting donations for his daughter's education. All donations are tax-deductible. @PSUresearch Please RT. gofund.me/ef82effe

ALT Yifei with his family in June 2023
Tao Liu (τν) retweeted

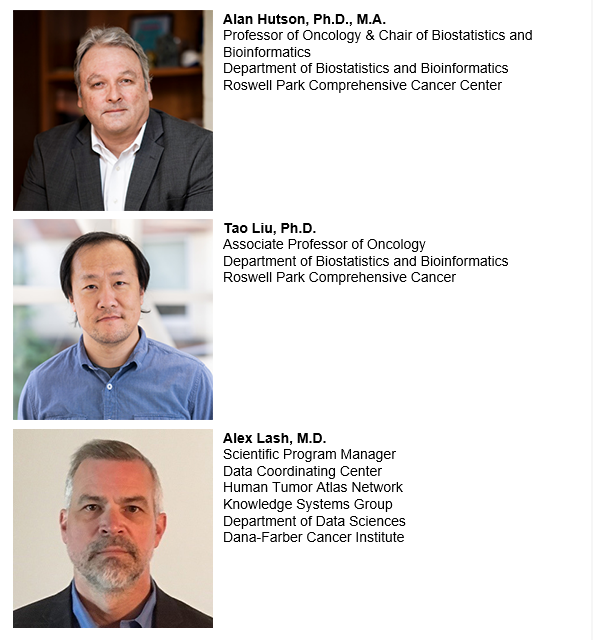
Join us for the @theNCI Webinar on "Data Management and Sharing in Cancer Moonshot Data Coordination Centers for IOTN, DRSN/ARTNet, and HTAN," featuring presentations by Drs. Hutson @Amherst73, Liu @fooliu , and Lash.
Don't miss out! Register now at t.ly/p0Vcd.
A collaboration with @nimezhu

Dr. Tao Liu @fooliu from @RoswellPark, introduces an innovative bioinformatics software developed by his team for the visualization of single-cell data.
Demo: t.ly/Q6yEP
#IOTNSCMeeting #Bioinformatics #DataVisualization


Found this photo will address the current two crises in the chess world — women chess and anti-cheating measurements!

Being a female in the male dominated field, the 5 decade long battle continues! 👑♟ (Yes, that is me on the right beating up on the guys at the famous Széchenyi Thermal Bath, one of Bobby Fischer’s favorite places). @WOMChess @FIDE_chess @EuropeEchecs @ECUonline

Absurd that the clock be wound back fifty years. Even more absurd that I can’t stop listening to 60’s RnR. If we can’t stop the rewinding, let’s bring old beauties back. The Soft Parade has just begun… youtu.be/axePr_RLS0o
The song “Borderline” by Chris de Burgh keeps repeating in my brain… youtu.be/BLoqIFaOHgg

It’s at least a 6-hour wait in the cold & snow to get on an evacuation train from #Dnipro. Many people here are from cities already under attack, like Kharkiv
Only women & children are allowed thru. Police are removing men of fighting age from the queue

Tao Liu (τν) retweeted

RNA velocity is an exciting concept but doesn’t always ‚work’. With @VolkerBergen, @_ruslansoldatov & @KharchenkoLab, we review current state & limitations of such modeling approaches @MolSystBiol, and discuss generalizations + give some guidance. Read at doi.org/10.15252/msb.2021102…

Tao Liu (τν) retweeted

1/ MAESTRO v1.5.0 is up in conda! Thanks to @gali_bai @fooliu @XShirleyLiu New features
Support processing multi-samples for both scRNA-seq and scATAC-seq.
integrated Chromap biorxiv.org/content/10.1101/… for fast processing of scATACseq data.
Install it github.com/liulab-dfci/MAEST…

Tao Liu (τν) retweeted

Thanks @tangming2005 @gali_bai @fooliu for the exciting new release of MAESTRO for scATAC-seq/scRNA-seq analysis, featuring multi-sample processing, > 10X faster read mapper Chromap, better documentation.

1/ MAESTRO v1.5.0 is up in conda! Thanks to @gali_bai @fooliu @XShirleyLiu New features
Support processing multi-samples for both scRNA-seq and scATAC-seq.
integrated Chromap biorxiv.org/content/10.1101/… for fast processing of scATACseq data.
Install it github.com/liulab-dfci/MAEST…
Tao Liu (τν) retweeted

Chromap is a new short-read mapper for Hi-C, ChIP/ATAC-seq and similar. It integrates sorting and dedupping and identifies barcodes for 10X scATAC-seq. Chromap is >10 times faster than bwa-mem and CellRanger 2.0 at comparable accuracy. Fine work led by @haowen_zhang and @mourisl.

Are the ChIP-seq/(sc)ATAC-seq/Hi-C communities jealous of RNA-seq community for fast data processing with Kallisto/Salmon? With joint forces from @haowen_zhang @XShirleyLiu @lh3lh3, we are thrilled to present Chromap for fast chromatin profiling analysis. biorxiv.org/content/10.1101/…
Tao Liu (τν) retweeted
Check out the article out today from @IOTNmoonshot PI Dr. Demehri & team @ScienceAdvances on carcinogen exposure induced immune-activating factors that promote CD8+ T cell immunity against metastasis #CIM21

CD8 T cell immunity blocks the metastasis of carcinogen-exposed breast cancer advances.sciencemag.org/cont…
Tao Liu (τν) retweeted
Minimap2 v2.19 released with better and more contiguous alignment over long INDELs and in highly repetitive regions, improvements backported from unimap. These represent the most significant algorithmic change since v2.1. Use with caution. github.com/lh3/minimap2/rele…
