

Ph.D. Student @HKUST CSE | KnowComp @HKUSTKnowComp | Agent Memory · Knowledge Graphs · Enterprise Data Agents 🧩🧠📊
Hong Kong
Joined March 2024
- Tweets6
- Following48
- Followers5
- Likes14
Pinned Tweet
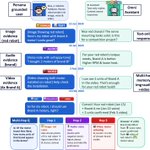
🚀 Introducing MOSAIC, a benchmark for long-term memory & cross-modal reasoning in omni-modal agents.
Can agents remember what users say, show & convey — and can we tell where memory failed?
Thanks to all collaborators!
Paper: arxiv.org/abs/2610.29249

Dennis, Hong Ting TSANG retweeted

Humans pass down explicit knowledge (laws, textbooks, procedures), not brains. AI agents upgrade every few months, yet their experience stays trapped in weights, context windows, or raw logs.
Today we're releasing two works to solve this: 🧵👇
Dennis, Hong Ting TSANG retweeted
🚀 Introducing MOSAIC, a benchmark for long-term memory & cross-modal reasoning in omni-modal agents.
Can agents remember what users say, show & convey — and can we tell where memory failed?
Thanks to all collaborators!
Paper: arxiv.org/abs/2610.29249
Dennis, Hong Ting TSANG retweeted

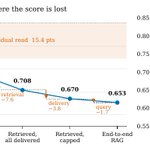
Under MOSAIC's fixed reader, gold symbolic facts still leave 15.4 points of reading/grading error, its largest single loss. A text-only memory study this week (arXiv 2610.30755) instead found evidence access the larger bottleneck. Modality may decide which stage breaks first.

🚀 Introducing MOSAIC, a benchmark for long-term memory & cross-modal reasoning in omni-modal agents.
Can agents remember what users say, show & convey — and can we tell where memory failed?
Thanks to all collaborators!
Paper: arxiv.org/abs/2610.29249
Dataset / indexes: huggingface.co/collections/g…
Project: hkust-knowcomp.github.io/MOS…
Code: github.com/HKUST-KnowComp/MO…
WRITE · RETRIEVE · DELIVER · READ — where the score drops (stage ladder).

20
Dennis, Hong Ting TSANG retweeted

The new MOSAIC benchmark evaluates conversational memory across text, images, video, and audio using 923 questions over histories lasting 11–24 sessions. Its diagnostic protocol separates failures in representing evidence, retrieving it, delivering it to the model, and reading it; audio cases include annotated vocal cues such as tone and rhythm.
If you are comparing memory systems for multimodal assistants, a single end-to-end accuracy score cannot identify which component needs improvement. MOSAIC supports decisions about storage, retrieval, context delivery, and model comprehension separately instead of treating every forgotten detail as the same failure
See more at benchmark-radar.org/
