





Jungsoo Lee retweeted

I wanted to share some of my personal excitement surrounding this paper.
In 2002, Geoff Hinton proposed Contrastive Divergence as a way of training EBMs. The goal then was to model p(x) in an unsupervised manner. Modeling log p(x) was easier to do, where log p(x) acts as the negative energy in a Boltzmann distribution.
But the problem with contrastive divergence back then was that it caused the energy landscape to be too sharp on the data manifold. Because images live on a thin, low-dimensional manifold in high-dimensional space, probabilistic methods like these caused the density to explode on the manifold and drop to zero everywhere else.
As a result, the community diverged and opted toward adding noise to prevent sharpness and smooth out the energy landscape, which ultimately led down the diffusion denoising route.
But we are finally back to Hinton's original vision. Very excited about what's next!
Congrats @AlexiGlad and team!

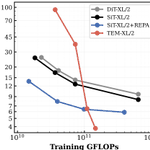
Energy-Based Models can now scale better than Diffusion models.
Introducing TEM: Transformer Energy-based Models
TLDR:
• TEM outscales Diffusion without guidance
• First scalable contrastive Energy-Based Models
• Better generalization, test-time scaling, and OOD detection than Diffusion
🧵
[8/N] TEMs can also keep refining past the number of sampling steps they were trained with.
Despite being trained with 40 sampling steps, we can run 120 inference steps and performance keeps improving.
1
8
1,013
[9/N] TEMs demonstrate the promise of Energy-Based Models as a generative modeling paradigm.
More EBM work is coming soon so stay tuned!
Thanks to @AlexiGlad for his contribution and my advisor @du_yilun for the guidance!
🌐 Project page: int-lee.github.io/scalable-e…
📄 Paper: arxiv.org/abs/2610.31889
💻 Code: github.com/int-lee/TEM
