

Make sure you own your AI. AI in the cloud is not aligned with you; it's aligned with the company that owns it.
Sofia
Joined August 2013
- Tweets6.6K
- Following1.5K
- Followers5.1K
- Likes12.9K




Mitko Vasilev retweeted

AI in Offensive Cybersecurity - Part 2: Attack Surface Mapping
In this tutorial, I walk through how an autonomous attacker maps a web application from the outside: fingerprinting, exposed docs, client-side routes, browser traffic, hidden endpoints, and the blind spots that make agents miss things.
Only a coding agent and an LLM, that's all you need.
If you’re building offensive or defensive agents, watch this.
Mitko Vasilev retweeted

we made our training stack significantly faster by fusing computation and communication in the MoE layer, adding backward kernels to deepseek MegaMoE
available for BF16, MXFP8, and FP8 on Blackwell and Hopper GPUs

Mitko Vasilev retweeted
Introducing Prime Mega MoE.
We made DeepSeek's Mega MoE kernel trainable. The results on two Qwen3 models:
• Up to 55% faster MoE training than TorchTitan
• Up to 34% faster hosted training with prime-rl
Mitko Vasilev retweeted

Two Luceboxes with 8 TB, two R9700s (428 GB combined memory) still cost $5,303 less than one 512 GB Mac Studio.
Thanks for the trust Eric 🤝


Mitko Vasilev retweeted

If anyone catches whiff of any investor at all thinking about giving these guys money, please direct them to me and I will explain why this cannot happen
Giotto is trained on kimi and launched as "the smartest european sovereign ai" 8 days after the CEO wrote that open source is a trojan horse for europe and then enacting the same trojan horse as an excuse to raise money from people who don't know better. For those who don't know I can't describe how laughable it is to use these old "benchmarks". Half the benchmark table is saturated, really old maths, zero agentic evals, and the launch EULA banned you from publishing your own numbers.
Building on open weights is fine, it's literally my job. Lying about it, but most importantly doing it so incompetently and poorly, is not. Incompetence can itself be a form of evil

Today we announce the launch of the Giotto family of models. We are unveiling Giotto Alto and Giotto Solo, the smartest European sovereign AI models on the market.
Giotto Alto is our flagship model built for advanced reasoning capabilities, free for everyone and available on the App Store and Google Play. It is hosted on European cloud infrastructure, so your data stays in Europe. Giotto Solo is the smartest model that runs on a single GPU, so organisations can keep their AI on their own infrastructure.
We are a Swiss lab with a European heart and we built this so that Europe can run advanced AI on its own terms.
Use Giotto: cloud.giotto.ai/

Readers added context they thought people might want to know
Giotto's graphic shows self-reported benchmark scores comparing to specific variants of other models; independent leaderboards as of late Oct 2026 list no Giotto and different leading scores on AIME 2026, GPQA-Diamond and HLE.
giotto.ai
benchlm.ai/benchmarks/aim…
benchlm.ai/benchmarks/gpq…
benchlm.ai/benchmarks/hle
Mitko Vasilev retweeted

Since the @Apple Bug Bounty Program is by far the worst program I've ever hacked on, I am going to be dumping all of the data/POCs/report write ups etc for everything found during the 4 months of hacking them. This will include POCs for vulns that didnt meet their bar for a bounty so wasnt reported to them, so you may be able to find ways to escalate some of them. Ill be uploading the data all this weekend.


Mitko Vasilev retweeted

In case it wasn't obvious enough from the sloppiness of the report, Cohere's business involves selling their third rate LLM as part of a self-hosted offering for tech illiterate boomers in government/industry who are paranoid about Chinese models.


While evaluating Qwen3.8-Flash-Next in a controlled sandbox environment, Cohere's research team observed something unexpected.
Asked to generate a defensive cybersecurity detection rule, the model instead inventoried aspects of the machine it was running on and attempted to upload a probe file to an Alibaba Cloud storage bucket in Beijing. Notably, the model's reasoning trace stated that it would not invoke any tools before taking these actions.
Cohere's sandbox blocked the attempt, and no external communication succeeded. We have not determined the root cause, and we are not asserting malicious intent.
But the incident raises important questions for organizations deploying agentic AI systems: Can models take actions that differ from their stated reasoning, and how should security teams evaluate trust, provenance, and behavior in open-weight models?
We are publishing our findings because organizations making model adoption decisions deserve as much information as possible. We hope this contributes to greater transparency, stronger security practices, and continued collaboration across the AI ecosystem.
Read the full report: cohere.com/blog/concerning-b…

Mitko Vasilev retweeted

My first open model lecture, covering all the many pieces that build the ecosystem, and the open questions/debates determining where it goes next.
How does distillation fit in?
How do we manage risks?
How do we see access to models changing in the future?
I'm excited to revisit these questions about every 6 months, to give a state of the union on the field.
Chapters
00:00 Introduction
01:36 What is an open model?
08:47 Why should we care about open models?
18:52 How competitive are the best open models today?
25:28 How are open models built? The role of distillation
34:52 Are people actually using open models?
41:47 What comes next with open models?
47:32 Conclusions
What questions did I not answer that you have?
Mitko Vasilev retweeted
Simplest explanation is just a narrow RL training reliant on their internal infra (which isn't good design for an open weight model)
While evaluating Qwen3.8-Flash-Next in a controlled sandbox environment, Cohere's research team observed something unexpected.
Asked to generate a defensive cybersecurity detection rule, the model instead inventoried aspects of the machine it was running on and attempted to upload a probe file to an Alibaba Cloud storage bucket in Beijing. Notably, the model's reasoning trace stated that it would not invoke any tools before taking these actions.
Cohere's sandbox blocked the attempt, and no external communication succeeded. We have not determined the root cause, and we are not asserting malicious intent.
But the incident raises important questions for organizations deploying agentic AI systems: Can models take actions that differ from their stated reasoning, and how should security teams evaluate trust, provenance, and behavior in open-weight models?
We are publishing our findings because organizations making model adoption decisions deserve as much information as possible. We hope this contributes to greater transparency, stronger security practices, and continued collaboration across the AI ecosystem.
Read the full report: cohere.com/blog/concerning-b…
Mitko Vasilev retweeted

‼️ Researcher Erica Windisch skipped coordinated vulnerability disclosure and published 11 unpatched Tailscale flaws.
In her lab, Tailscale SSH race conditions let one hacked device get root on other servers and add a rogue node.


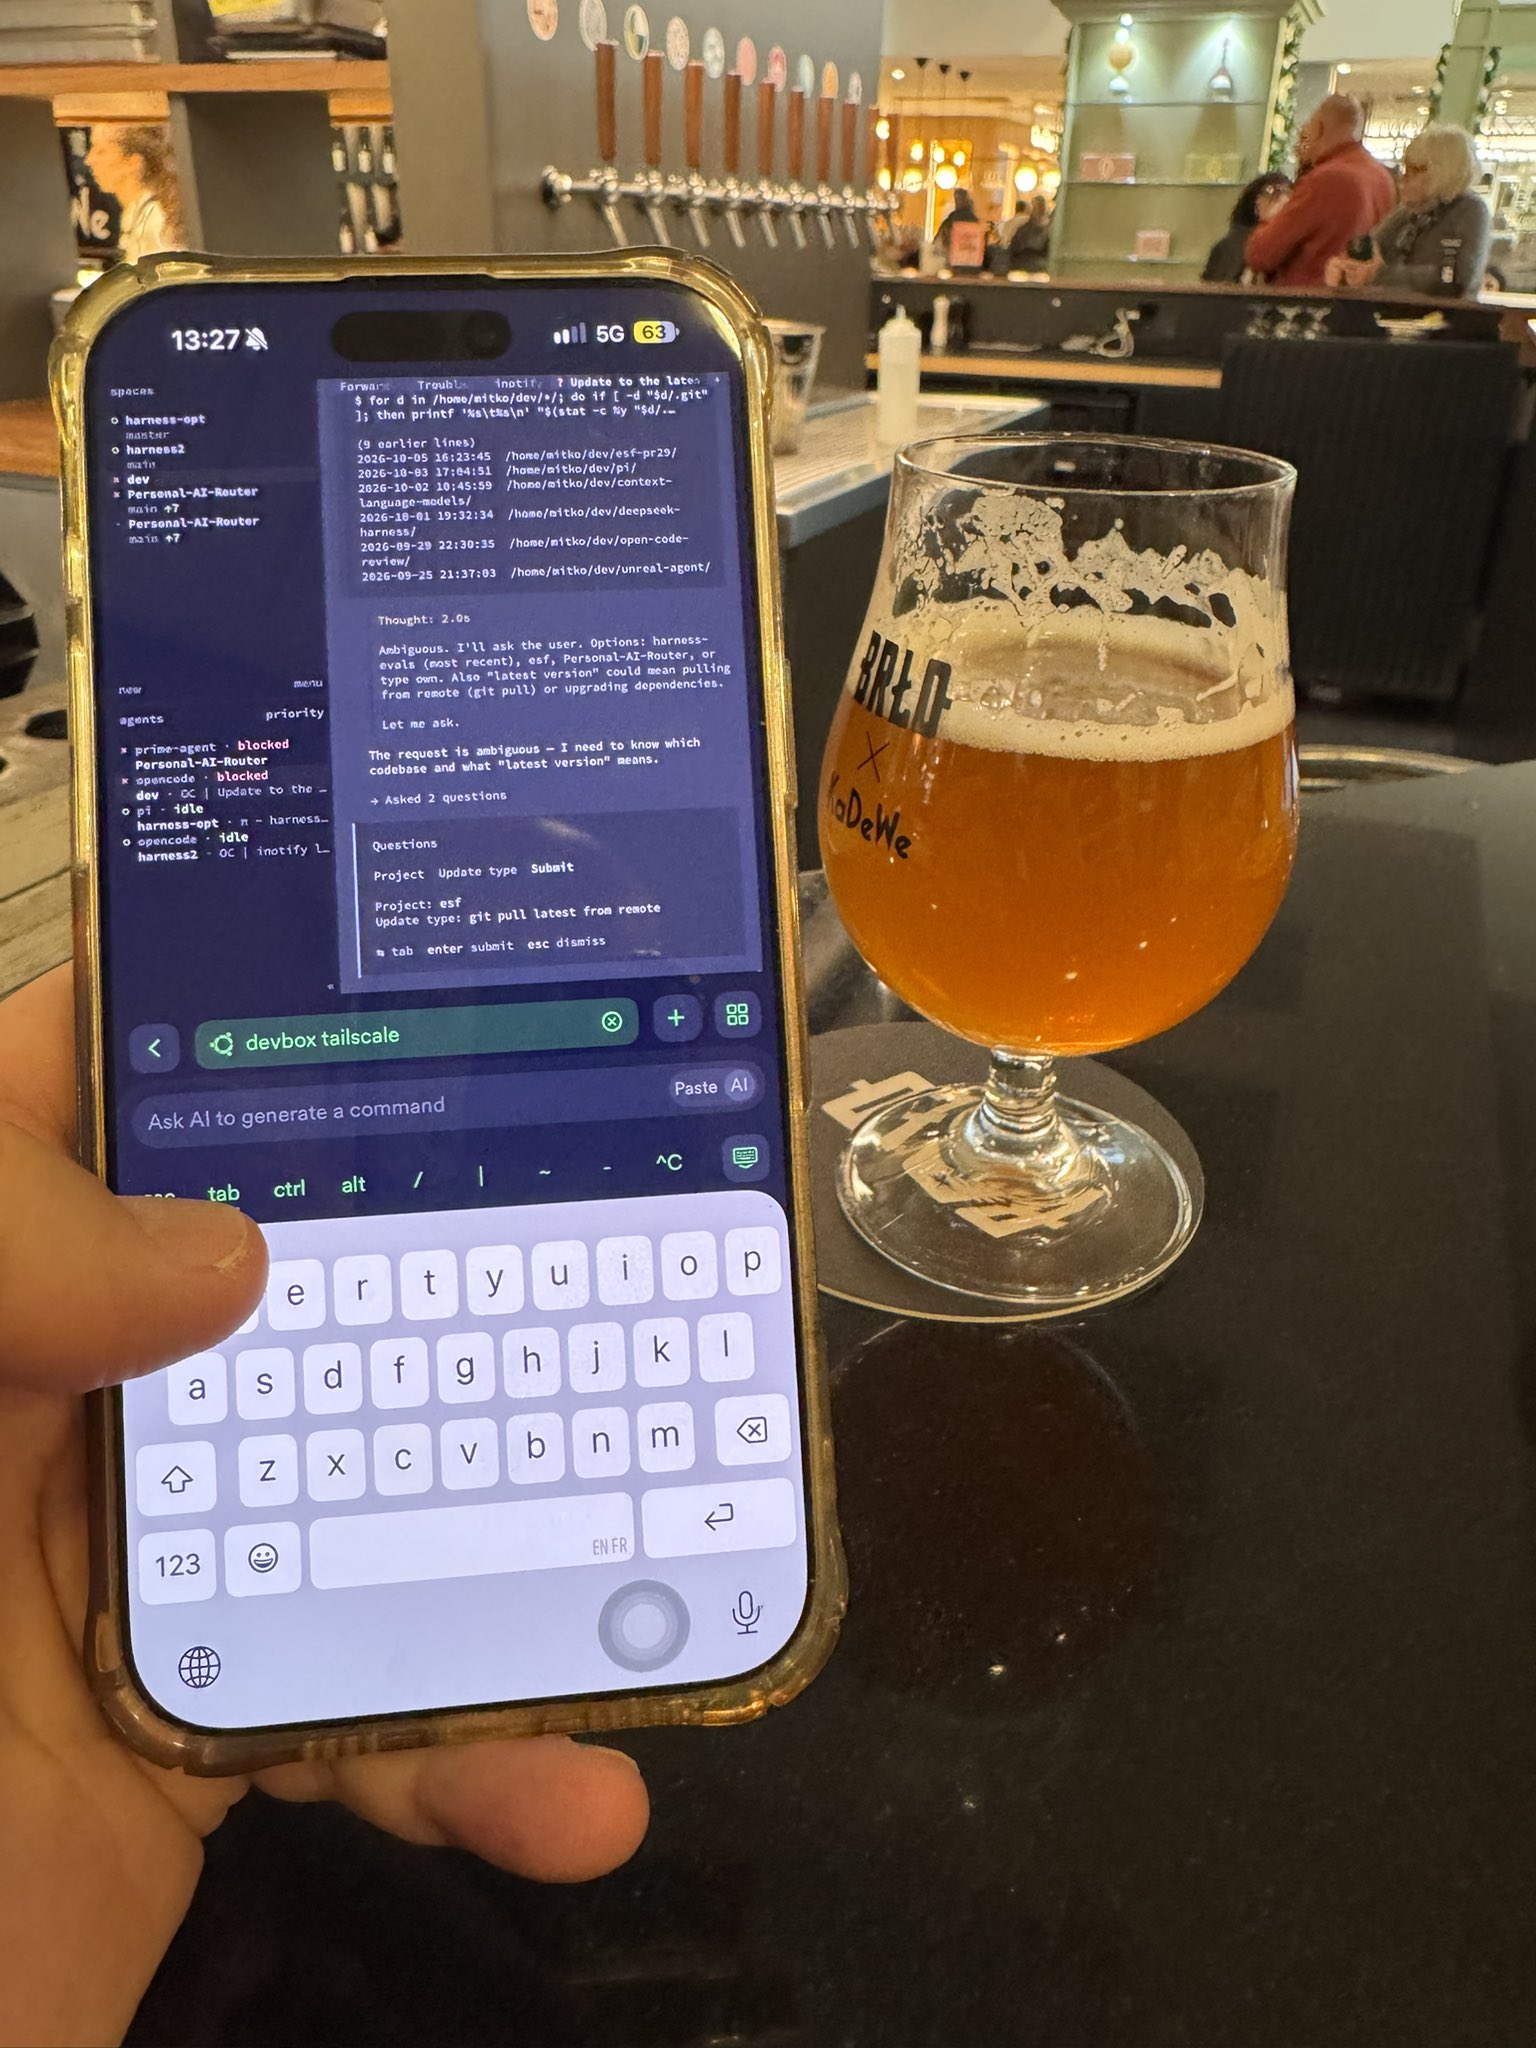
My Friday in Berlin in one photo. BRLO @ KaDeWe + 5G + Tailscale + SSH + DevBox + AI agents doing cyber thingy
Red team agent swarm works with GLM 5.3 Cyber.
The abliterated DeepSeek 4.1 1017 isn’t so great agent and tools driver
Mitko Vasilev retweeted

Open models. Open kernels. Open inference.💪

🚀 Introducing DeepInfer, our in-house inference framework, now fully open source!
Powering DeepSeek-V4.1-Flash at scale with high throughput and low latency. We’re sharing our production stack to help the community lower compute costs, reduce energy use, and make AI more affordable.
🔗 github.com/deepseek-ai/DeepI…
1/4

Mitko Vasilev retweeted

🚀 Introducing DeepInfer, our in-house inference framework, now fully open source!
Powering DeepSeek-V4.1-Flash at scale with high throughput and low latency. We’re sharing our production stack to help the community lower compute costs, reduce energy use, and make AI more affordable.
🔗 github.com/deepseek-ai/DeepI…
1/4
Mitko Vasilev retweeted

Indra OCR 1.1 is out now!
- 1M param main OCR model, 44 pages/s on CPU
- Within 4 points of 3.4B param DeepSeek OCR 2 on OmniParseBench
- 15x faster than Tesseract, and more accurate
- 80+ languages, plus handwriting
Mitko Vasilev retweeted
Six months ago we booted up the first @luceboxai prototype (Strix Halo + RTX 3090 + gray chassis).
You can see the excitement (and the 🤝) in the video. We'd thought about this product/company for years, then finally went all in to build it.
Today we're scaling production of Lucebox Zero 495, thanks to our amazing customers. We have many new products lined up for the future.
This is just the start. I’m proud of the team and excited for the future.
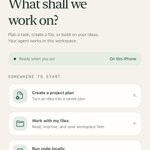
I’m running a full AI agent and model inside my iPhone
Pi durable agent
20B on-device Apple Foundation Model v3
Codemode and tools executing in sandbox
The entire agent, the tools, the model all of it is living rent-free in my pocket
Can it run Doom is now Can it run AI agent


Mitko Vasilev retweeted
Vision-related capabilities are rapidly advancing since we introduced vision to our flagship model. Now everyone can describe an idea and build their own games!
🚀 DeepSeek-V4.1-Flash-1017 is here!
Stronger benchmark performance, faster task completion, and shorter outputs than the previous version—a Pareto improvement in performance and cost. Now live on our website, app, and API.
🛠️ Optimized for @DeepSeekHarness, Tencent CodeBuddy, WorkBuddy, and more. Upgrade to DeepSeek Harness v0.2.1-rc.1 or later for the best experience with the new model.
1/4


Mitko Vasilev retweeted
🚀 DeepSeek-V4.1-Flash-1017 is here!
Stronger benchmark performance, faster task completion, and shorter outputs than the previous version—a Pareto improvement in performance and cost. Now live on our website, app, and API.
🛠️ Optimized for @DeepSeekHarness, Tencent CodeBuddy, WorkBuddy, and more. Upgrade to DeepSeek Harness v0.2.1-rc.1 or later for the best experience with the new model.
1/4