

CS PhD @UofIllinois, Research @NVIDIA | Prev @Berkeley_ai, @MSFTResearch
Champaign, IL
Joined January 2024
- Tweets440
- Following204
- Followers1.3K
- Likes697





Pinned Tweet
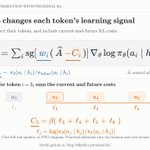
1/11 Can a single-token importance weight preserve the target of full-sequence correction? With Future-KL, we prove that both updates share the same unique stationary policy. We also contribute the promising empirical results we observed.
arxiv.org/abs/2610.18738
Jack Bai retweeted

funny that substrate independence is called “religious”, when the opposite has deep roots in religion and dualism. it’s often those shouting “absurd that llms considered conscious!” who (perhaps unconsciously) are selling you their religious beliefs

Spectacular Nature piece on why AI is not conscious and probably will never be.
Three arguments:
1) Intelligence is not consciousness.
Intelligence is about solving problems. Consciousness is about having subjective experiences.
AlphaFold can solve super difficult problems. By contrast, our brains performs complex operations entirely outside awareness.
Problem-solving and consciousness are two separate things.
2. Biology is essential.
Our brains are alive, down to every cell. Their activity is inseparable from the living tissue that produces it.
The idea that consciousness can be reproduced simply by running the right computations on silicon components who do not fight for their life is a very far fetching and, I would add, almost religious, assumption.
3) The physical organization may matter more than the computation.
According to integrated information theory, consciousness requires specific causal relationships between a system’s physical components.
The computer architectures running today’s AI lack this organization.
The comparison with AlphaFold is particularly revealing:
Almost nobody things AlphaFold is conscious, despite its inner working is very similar to an LLM
Why?
Because it does not speak.
LLMs do speak like us and therefore we fall into an illusion:
Since they speak like us, they must be like us.
But this inference is wrong.
LLMs are just a series of matrix multiplications.
They are not conscious, and they will never be.
*
Paper in the first reply

Jack Bai retweeted

🚀 Introducing Lean4AgenticRL framework. The first method to apply formal verification in an open-ended domain for agentic RL. We apply the Lean4Agent(xitter.cf/RickyRDWang/status/206…) framework to provide process rewards for agentic RL. We train LAR-9B/27B using Lean4AgenticRL. The LAR-9B models achieve a 20.2% improvement on SWE-Bench-Verified, bringing the score to 64.2%. The LAR-27B model achieves 77.3% on TerminalBench-2.1, improving the base model by 7.7%. The LAR-9B/27B outperforms all the known baselines of similar size in SWE-Bench-Verified, TB-2.0, and TB-2.1. Welcome to read our paper and try our model!
[1/n]
Paper: github.com/RickySkywalker/Le…
Model: huggingface.co/amazon/LAR-27… and huggingface.co/amazon/LAR-9B
Code: github.com/RickySkywalker/Le…
Website: lean4agent.github.io/


🚀 Introducing the Lean4Agent framework. The first framework 🎉 that unifies the formal verification of agent workflow and executions. It views the agent workflow as “a computer program in natural language.”
🤖 The Lean4Agent provides FormalAgentLib that treats agent workflows like programs. We develop a predicate system that elegantly constrains the agent's execution step via preconditions and postconditions.
✅ This framework makes agent workflows’ self-consistency verifiable before execution, and enables the detection of which step of the workflow breaks the consistency for fine-grained fixes.
🔁 When a verified workflow fails on a specific problem, the predicate system, combined with the LeanEvolve proposed in the Lean4Agent framework. We can dynamically update the workflow to enhance its performance.
[1/n]
Paper: arxiv.org/abs/2606.06523
Huggingface: huggingface.co/papers/2606.0…
GitHub Repo: github.com/RickySkywalker/Le…

Jack Bai retweeted

What does it take to turn VLMs for cost-efficient zero-shot robot manipulation, without tools, without task-specific training, without external modules like VLA-as-tool or SAM3 or IK Solver ?
🤖 Introducing MotorMind !
💡 Zero-shot Manipulation: No Fine-tuning or Coding agent
💡 VLM-only: No external perception models, No tools, No VLA-as-tool, No IK-Solver
💡 Local Deployable: Qwen3.8-Next-Flash as backbone model for cost-efficient local deployment
💡 Strong Generalization: 83.3% success on LIBERO-PRO
💡 Real-Robot Transfer: 95% success on real-robot tasks without embodiment-specific training
Check out more:
📄 Paper: arxiv.org/pdf/2609.38078
🌐 Project: motor-mind.github.io/
💻 Code: github.com/Motor-Mind/MotorM…
Ratio-free off-policy RL algorithm that shares some common insights in proof with Proximal KL.

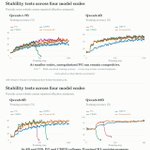
1/7 Can an LLM learn from an older rollout model without importance weights?
Introducing Gibbs-Gap Policy Optimization (GGPO).
Sync rollouts every 8 -> 128 optimizer updates: accuracy stays at 46.58% -> 46.39% across five math benchmarks (Qwen3-1.7B-Base).

ALT GGPO accuracy stays near 46.5 percent as the rollout synchronization interval grows from 8 to 128 optimizer updates. Other tested methods decline more at 128 updates.

11/11 More to be discovered in
Paper: arxiv.org/abs/2610.18738
Blog (more introductory): biechi.github.io/blog/offpol…
Code: github.com/BiEchi/proximal-k…
Jack Bai retweeted
new blogpost about beginner-level advice on breaking down proofs, which I feel students new to theory may find helpful especially at this time where most derivations are done with the help of LLMs: nanjiang.cs.illinois.edu/202…
Jack Bai retweeted

Introducing CUA-Lite 🧵 — an open platform for computer-use agents.
Training and benchmarking CUAs (Computer-Use Agents) requires four core pieces:
1️⃣ Agents — the models and the scaffolding that drives them
2️⃣ Environments — runtime/sandboxes for agents to interact with, tasks & verifiers/graders
3️⃣ Traces — records of agent trajectories
4️⃣ Frameworks — to evaluate, SFT & RL-train agents
Today, all four are fragmented.
Every agent ships with its own implementation, often in a separate repo — there is no unified way to run them all. Every environment exposes its own interface and action space, often requiring an expensive VM sandbox for each verifiable task. Traces come in incompatible formats. And without common standards across the stack, every project ends up rebuilding its own tooling/framework for eval, SFT, and RL.
CUA-Lite unifies the stack:
→ One standardized interface & action space for agents and environments
→ One standardized format for agent traces
→ One framework for evaluation, SFT & RL
→ Across desktop, browser & mobile
And open resources plug straight in, creating the largest open collection of CUA agents, environments and traces, all in a unified format:
🤖 10+ CUAs, including GPT, Claude, Gemini, Qwen, Muse-Glimmer, UI-TARS
🌐 15+ benchmarks, including OSWorld, WebArena & AndroidWorld
⚡ Optional VM-free sandboxes with 30K+ verifiable tasks for training
📚 10+ trace datasets, freely available on Hugging Face, including public datasets converted into the standardized format and fresh rollouts from frontier open-weight CUAs
Led by @BerkeleyRDI , our goal is for CUA-Lite to become a community-driven, open-source ecosystem for computer-use agents.
Join the community and contribute today: bring an environment (runtime/sandbox + tasks + verifier), traces, or an agent, and plug it into CUA-Lite!
Jack Bai retweeted

Behavioral cloning mystery
seohong.me/blog/behavioral-c…
I wrote a new blog post about "mysteries" in behavioral cloning that appear with real-world robot data (e.g., overfitting is "good"). I also tried to demystify them and shared my thoughts!

Jack Bai retweeted
on side note, the fun of working in RL theory is that results like this are still discovered from time to time, where a few lines explain (to experts) significance + proof machinery, and we are like "how come we didn't realize this before"

Cool paper from @LarsvanderLaan3 and @nathankallus: you can use MLE to estimate density-ratio in MDP w/o completeness. Usually you need latter b/c bellman op and projection contract in diff geometries, but in this case it's both KL. Very cool insight. arxiv.org/abs/2607.05375


