

Software Engineer pre AI - TensorFold Contributor - Local LLM builds for DGX Sparks - Engineering Mentor to 1,200+ AI builders.
Bangkok, Thailand
Joined February 2026
- Tweets2.1K
- Following131
- Followers1.2K
- Likes683




Pinned Tweet
My DeepSeek-V4.1-Flash-1017 quant is NOW LIVE for TP=2 DGX Sparks.
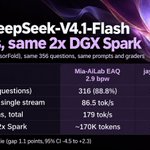
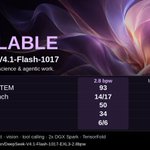
Same 353 questions for all three packs:
new / Mia 2.9 / my old q28-v2
MMLU-Pro STEM: 93 / 91 / 90 (of 100)
LiveCodeBench: 14 / 11 / 11 (of 17)
MBPP+: 50 / 49 / 50 (of 60)
HumanEval+: 34 / 34 / 33 (of 40)
SciCode: 6 / 6 / 5 (of 10)
MATH-500: 36 / 36 / 36 (of 40)
MGSM: 40 / 40 / 40
BFCL tool calls: 39 / 39 / 39 (of 40)
Multi-step tool chains: 6/6, 6/6, 4/6
These are small samples, so I read it as "at least as good, in a smaller pack". It's not a blowout.
The gaps I care about are LiveCodeBench and the tool chains, which my old quant kept dropping. Calibrated it for coding, science and agent work.
Weights/Recipe are in the comments. Recipe has been updated with my current config but is mostly unchanged.
@MiaAI_lab I still don't know how you get them so good. I can't wait to use your Engine Aware Quant (EAQ) system when it's ready.
2.8 BPW, EXL3, 203.8 GB, running on two DGX Sparks with @ashxhart TensorFold.
- 1M context
- image input
- 2.1M-token cache total with NVMe offload.
As usual, if you have any issues, please let me know or submit a PR.
What will you throw at it first?

Just wanted to give an update on LocalRouter. I am working on a few new tools and some of the feedback.
Nothing is quite ready yet, but it's moving quickly
Nearly ready
- Jev style decision model for computer use.
- Remote companion and choose-your-own harness.
- Smaller quant for Dramma thanks to @plotarmordev
Also porting my companion mobile app over too, but I want to ask a question.
I don't want to deal with App Store submissions right now (Maybe later).
Would you prefer an Expo app that you would need an Expo account for, or a raw swift/kotlin build that you can just download to the device directly?
Both would just work over Tailscale. Let me know below!


LocalRouter AI assistant. One DGX Spark. Full duplex.
This actually feels like Jarvis in a box! Built on @ashxhart TensorFold
🧠 Qwen 27B
🗣️ Drama 3 with streaming (Thanks @plotarmordev )
🖼️ Qwen Image Turbo 2.1
🎬 MiniMax H3 video
👂 Whisper STT
~0.5s after I stop talking, it starts with its first word. Interrupt it anytime. Set the delay as you please for responses.
Normal models stay loaded and can be swapped as needed.
Want a video model up? Then Whisper and Drama will make space. Once the video is generated, start voice back up when the video is finished.
The goal is actually fully modular, so consider this a super early version of what it could be. MCP by default, but also ships with a simple UI you can extend as you please.
Thin by design, so everyone can make it their own.
What features do people want next? What about TP=2 or Mac Studio versions?
