

Builder | Hodl | Researcher | exploring & scaling new possibilities and potentials in the #Web3 #Crypto #Blockchain
tokyo
Joined January 2010
- Tweets2.9K
- Following1K
- Followers284
- Likes3.5K




今一番ホットなAIツール「Muse」、今週ついに日本上陸して使えるようになったみたい。
登録後48時間以内に画面左下の「設定」から招待コードを入れると、私とあなたの両方に【永久に使える10億トークン】が入る仕組みになってます。
コード: C461HL
muse.ai/join

66
Anthropic’s JV looks less like a services business and more like an architecture for adoption and valuation: PE brings distribution, the JV absorbs implementation intensity, and Anthropic preserves the high-margin platform narrative.

ANTHROPIC PARTNERS WITH GOLDMAN SACHS, BLACKSTONE AND OTHER MAJOR INVESTORS ON $1.5B AI VENTURE FOR PE-OWNED COMPANIES
73

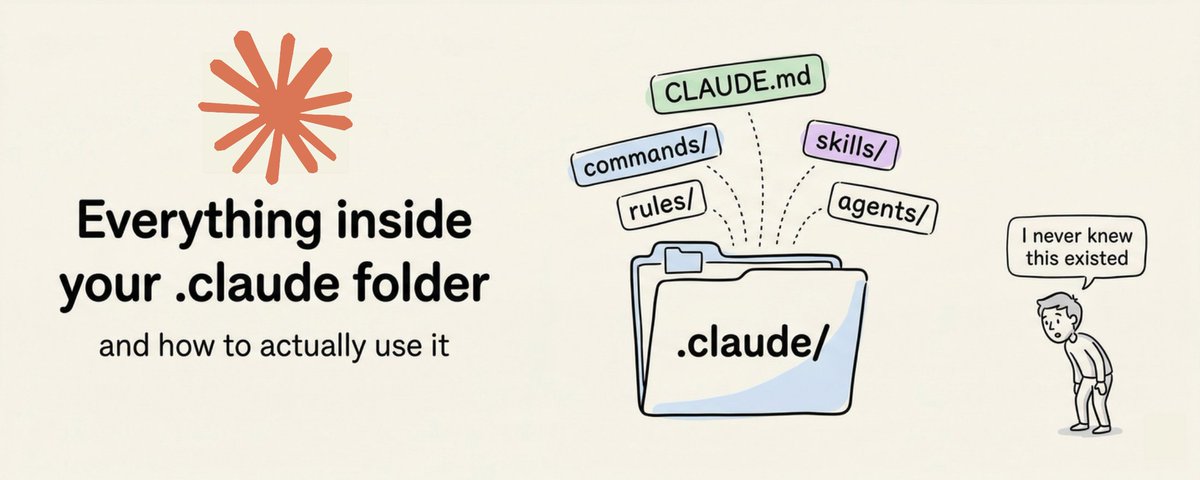
Claude Codeは、そのまま使うだけでも強い。
だが本当に効き始めるのは、.claude/ をブラックボックスではなく、チーム固有の開発OSとして扱い始めたときだ。
そしてSkillsを活用したいなら、そこが出発点になる

104
Cat WuやPeter Yangの発信を見ていると、agentic productの作り方はかなり見えてきている。
長い計画より短いスプリント。
重い設計より早いデモ。
モデル前提を固定せず、更新ごとに作り直す。
AI時代のPMは、仕様を書く人というより変化に追従する人になっていく。

1/ Plan in short sprints
2/ Encourage demos and evals over doc (get a prototype in front of internal folks and users asap!)
3/ Revisit features with new models
4/ Do the simple thing first
48
CursorJon氏が明かす「AIエージェント活用の5箇条」
1Plan Mode命
2チャットは頻繁に新規作成
3AIにレビューさせる
4計画は密に、実装は任せる
5検証環境をAIに渡す 効率が劇的に変わる

My top 3 tips for coding with agents:
1. Always start with Plan Mode. It's better to iterate in natural language and then execute once you know what the agent is going to do. This will save you time, effort, and tokens!
2. Start new chats frequently. Remember that your role is to point the Agent in the right direction to make the changes you need. If you change topics, the context window will get muddied. You will also be spending more tokens on longer chats.
3. Leverage AI to do your code review. If you know the failure case, ask a model. One prompt I often use is "scan the changes on my branch and confirm nothing is impacted outside of my feature flag". As a safety net for everything outside this issues-you-expect umbrella, use Bugbot.
1
99
採用実績よりGPU実績が語られる時代、もう来てる!人じゃなく“算力”で会社が駆動するってこういうこと。
note.com/panda_lab/n/nc40356…

1
111
「計算能力10万倍」「9000億のAIエージェントが稼働」— HUAWEIが描く2035年の世界 @ju2189ts note.com/panda_lab/n/n2f6d2a…

コンサル不要のAI導入ガイド:OpenAI公式レポートを基に、CEOやDX担当者が知るべきAI導入の全手順をnoteにまとめました。「何から始めるか」の答えがここにあります。#企業AI #DX推進 #生成AI #業務効率化
note.com/panda_lab/n/n08ab9f…

3
187
Open-source examples and guides for building with the OpenAI API. Browse a collection of snippets, advanced techniques and walkthroughs. Share your own examples…
Googleアプリで共有しました share.google/O1ehSiRUz8I4jN9…

113
ただの効率化じゃない!サム・アルトマンが実践する「睡眠、食事、仲間」まで網羅した生産性向上術。これを知れば、あなたの仕事と人生が大きく変わるかも
@ju2189ts note.com/panda_lab/n/na137bd…

1
105
0xpanda.alpha.lab retweeted

最初の方向性だけ与えて、研究課題を決めるところも自律的にできたってのがすごいな。
人工知能が科学をリードする時代へ——AI研究者「Zochi」がACL2025主会議に論文採択|0xpanda alpha lab @ju2189ts note.com/panda_lab/n/n8a6c51…
ステーブルコインがドル覇権をWeb3時代に拡張中。米国債を基盤に、新ブレトンウッズ体制が形成されつつあり、GENIUS法案はその未来を示す。 #ステーブルコイン #Web3 #ドル戦略
@ju2189ts note.com/panda_lab/n/n224912…
2
194
AppleのM2 Ultra、DeepSeekに大きな利点!
•コスパ最強:1GBあたり$26.04で、NVIDIA H100の12倍効率的。
•高速処理:統合メモリ&UltraFusionで800GB/sを実現、大規模モデルも余裕。
次世代M4 Ultraにも期待!これでApple株、また上がるかも!?

Market close: $NVDA: -16.91% | $AAPL: +3.21%
Why is DeepSeek great for Apple?
Here's a breakdown of the chips that can run DeepSeek V3 and R1 on the market now:
NVIDIA H100: 80GB @ 3TB/s, $25,000, $312.50 per GB
AMD MI300X: 192GB @ 5.3TB/s, $20,000, $104.17 per GB
Apple M2 Ultra: 192GB @ 800GB/s, $5,000, $26.04(!!) per GB
Apple's M2 Ultra (released in June 2023) is 4x more cost efficient per unit of memory than AMD MI300X and 12x more cost efficient than NVIDIA H100!
Why is this relevant to DeepSeek?
DeepSeek V3/R1 are MoE models with 671B total parameters, but only 37B are active each time a token is generated. We don't know exactly which 37B will be active when we generate a token, so they all need to be ready in high-speed GPU memory.
We can't use normal system RAM because it's too slow to load the 37B active parameters (we'd get <1 tok/sec). On the other hand GPUs have fast memory but GPU memory is expensive. Apple Silicon, however, uses Unified Memory and UltraFusion to fuse dies - a tradeoff that favors a large amount of medium-fast memory at a cheaper cost.
Unified memory shares a single pool of memory between the CPU and GPU rather than having separate memory for each. There's no need to have separate memory and copy data between the CPU and GPU.
UltraFusion is Apple's proprietary interconnect technology for connecting two dies with a super high speed, low latency connection (2.5TB/s). Apple's M2 Ultra is literally two Apple M2 Max dies fused together with UltraFusion. This is what enables Apple to achieve such a high amount of memory (192GB) and memory-bandwidth (800GB/s).
Apple M4 Ultra is rumored to use the same UltraFusion technology to fuse together two M4 Max dies. This would give the M4 Ultra 256GB(!!) of unified memory @ 1146GB/s. Two of these could run DeepSeek V3/R1 (4-bit) at 57 tok/sec.
All of this and Apple has managed to package this in a small form-factor for consumers with great power efficiency and great open-source (uncharacteristic of Apple!) software. MLX (h/t @awnihannun) has made it possible to leverage Apple Silicon for ML workloads and @exolabs has made it possible to cluster together multiple Apple Silicon devices to run large models, demonstrating DeepSeek R1 (671B) running on 7 M4 Mac Minis.
It's unclear who will build the best AI models, but it seems likely that AI will run on American hardware, on Apple Silicon.


1
525
Andrej Karpathyがdeepseek r1論文に対する強調:RLHF ≠ RL。学習は「模倣(観察・反復)」と「試行錯誤(強化学習)」の2種類。
AlphaGoの例:1) 模倣で学び、2) RLで勝利。驚きや魔法は常にRLから生まれる。詳細はこちら👇

I don't have too too much to add on top of this earlier post on V3 and I think it applies to R1 too (which is the more recent, thinking equivalent).
I will say that Deep Learning has a legendary ravenous appetite for compute, like no other algorithm that has ever been developed in AI. You may not always be utilizing it fully but I would never bet against compute as the upper bound for achievable intelligence in the long run. Not just for an individual final training run, but also for the entire innovation / experimentation engine that silently underlies all the algorithmic innovations.
Data has historically been seen as a separate category from compute, but even data is downstream of compute to a large extent - you can spend compute to create data. Tons of it. You've heard this called synthetic data generation, but less obviously, there is a very deep connection (equivalence even) between "synthetic data generation" and "reinforcement learning". In the trial-and-error learning process in RL, the "trial" is model generating (synthetic) data, which it then learns from based on the "error" (/reward). Conversely, when you generate synthetic data and then rank or filter it in any way, your filter is straight up equivalent to a 0-1 advantage function - congrats you're doing crappy RL.
Last thought. Not sure if this is obvious. There are two major types of learning, in both children and in deep learning. There is 1) imitation learning (watch and repeat, i.e. pretraining, supervised finetuning), and 2) trial-and-error learning (reinforcement learning). My favorite simple example is AlphaGo - 1) is learning by imitating expert players, 2) is reinforcement learning to win the game. Almost every single shocking result of deep learning, and the source of all *magic* is always 2. 2 is significantly significantly more powerful. 2 is what surprises you. 2 is when the paddle learns to hit the ball behind the blocks in Breakout. 2 is when AlphaGo beats even Lee Sedol. And 2 is the "aha moment" when the DeepSeek (or o1 etc.) discovers that it works well to re-evaluate your assumptions, backtrack, try something else, etc. It's the solving strategies you see this model use in its chain of thought. It's how it goes back and forth thinking to itself. These thoughts are *emergent* (!!!) and this is actually seriously incredible, impressive and new (as in publicly available and documented etc.). The model could never learn this with 1 (by imitation), because the cognition of the model and the cognition of the human labeler is different. The human would never know to correctly annotate these kinds of solving strategies and what they should even look like. They have to be discovered during reinforcement learning as empirically and statistically useful towards a final outcome.
(Last last thought/reference this time for real is that RL is powerful but RLHF is not. RLHF is not RL. I have a separate rant on that in an earlier tweet
teapawt.org/karpathy/status/182127…)
263
NVIDIAは前例のない競争の波に直面、現在の高すぎる評価、以下の理由で「堀」は崩れつつある
❗️ハード-自社開発チップの台頭(GAFAなど)
❗️ソフト-CUDA優位性の低下、MLXやTritonといった汎用フレームワークや自動コード移植技術により揺らぐ
❗️DeepSeekが示す効率革命
youtubetranscriptoptimizer.c…
223
DeepSeekが再び大きな一歩!マルチモーダル統合オープンソースモデル「Janus-Pro」シリーズが登場!🔥
最後のモデル「Emu3」は昨年10月リリース。
7Bモデル: huggingface.co/spaces/deepse…
旧正月中にプラグインも公開予定。お楽しみに!
145
0xpanda.alpha.lab retweeted
Trump's World Liberty(@worldlibertyfi) just spent 20M $USDC to buy 6,041 $ETH at $3,311.
intel.arkm.com/explorer/addr…
teapawt.org/lookonchain/status/187…


Trump's World Liberty(@worldlibertyfi) exchanged 103 $WBTC($9.89M) for 3,075 $ETH at a rate of $0.03354 and deposited 18,536 $ETH($59.8M) into #CoinbasePrime.
Afterward, World Liberty spent 1.7M $USDT to buy 17.62 $WBTC at $96,491.
The $ETH, $WBTC, $AAVE, $LINK, $ENA, and $ONDO purchased by Trump's World Liberty have now resulted in a loss of over $4.8M.
debank.com/profile/0x5be9a49…


Chrome拡張でAIがポチポチ?Midscene.jsで作業効率が爆上!|0xpanda alpha lab @ju2189ts #note note.com/panda_lab/n/n3612cb…

1
111