
NLP researcher (question answering, information extraction)
Japan
Joined April 2018
- Tweets1.6K
- Following277
- Followers381
- Likes2.3K


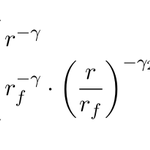

Pinned Tweet
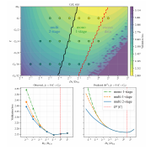
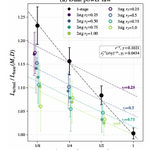
We just posted our paper: “M^3 Scaling Law: Optimizing Multi-Epoch, Multi-Lingual, and Multi-Stage Training for Low-Resource Language Models.”
Joint work with @kanaheinousagi and @stillpedant.
In this thread, I’ll explain the main idea and key findings. (1/N)

K. Akimoto retweeted

EACL 2027 Findingsに採択されました!
広範な文書種別・リアルな質問での評価を追求した、日本語視覚文書理解ベンチマーク(Omni-JDocVQA)に関する研究です。

RP 事前学習の改善がデータの改善によるというのはその通りだけど、品質という1軸ではなく時間経過による経験の蓄積というもう一つの軸があるよな
モデルがタスクを解いた経験データが事前学習に入って学ばれる。
今までは人類と論文・技術文章が担っていた部分がモデルとドラジェクトリになり加速する
1
181
K. Akimoto retweeted
Pretraining progress seems to be coming mostly from data improvements.
@who_is_jerbear and I pretrained combinations of year-representative open model recipes and data corpuses across 2019 to 2025 at various small scales.
Data improvements contributed 3.24x as many compute multipliers as model improvements did (12.0x vs 3.7x).
And the gains stack independently - a better dataset helps every architecture about equally, and vice versa.
Here are full results, plus what we think this means for the future of AI progress:
dwarkesh.com/p/pretraining-p…


I will present my research about scaling law analysis for multi-epoch, multi-lingual, and multi-stage training at poster session F (Hall H, 9:00-10:30) at #EMNLP2026 !!
Feel free to stop by and chat. I'd love to hear your thoughts!


K. Akimoto retweeted

🎉 Excited to share that our paper, conducted during my research internship at NEC, was selected as a Best Paper Candidate at #MIPR2026!
The paper is now available on IEEE Xplore:
ieeexplore.ieee.org/document…
Huge thanks to my mentors and collaborators at NEC🙏