

@scaleyazilim - https://teapawt.org/t.co/NfdD3QdRnG
Ankara, Türkiye
Joined May 2008
- Tweets7K
- Following798
- Followers1K
- Likes6.3K





Pinned Tweet
a Postgres rewrite in Rust that passes all 46,066 regression tests. 100 percent compatibility, not a toy clone.
it even compiles Postgres in your browser via WASM, so you get a real REPL in a tab.
experimental, but that number is wild.
pgrust.com/

I'm turning learning Qdrant into a sea voyage. An interactive course where you sail island to island, each one a module, running real searches on a live @qdrant_engine cluster as you go. 14 modules, from the basics to hybrid search and ranking. ⚓
komshoo.training

1
124
My friend @alpervision built the Machine from Person of Interest, basically. His Claude Code agent calls his iPhone when it gets stuck, a permission prompt or a question, and he answers by voice from anywhere.
github.com/wutlu/callmeclaud…
Added an Insights tab to Corral. It reads my own agent logs and scores how I build. Apparently I'm 'The Navigator', steers hard and argues back when the agent drifts. 13 badges in 7 days, plus nudges to the ones I'm missing. All local, nothing uploaded.
github.com/popyapp/corral


Half the music in my YouTube feed feels AI now. Over 50% of Deezer's daily uploads are AI, but actual listens stay around 1-3%. When you can't tell, does it matter?
techcrunch.com/2026/07/21/mu…

104
The quiet win in 1.20: BM25 now runs on the text you already store. Keyword ranking in @qdrant_engine used to mean an extra sparse-vector step per doc and query, plus tracking avg doc length by hand. Now it's native. Hybrid without a second pipeline. teapawt.org/andre_z/status/2113559…

The @qdrant_engine v1.20 release is here and brings improvements for full-text search. While we still believe that the sparse vectors are super powerful when using neural sparse models like SPLADE, sometimes it just has to be simple and fast. You asked, we did it.
From now on, Qdrant scores BM25 directly on the full-text index. => qdrant.tech/blog/qdrant-1.20…

102
PHP2Shell dropped this week. Unauth RCE in PHP, CVSS 9.2, hitting 5.4 up to 8.5. Patching fixes it, but I wanted to know if a box was already hit. So I wrote a checker: versions, processes, session dirs, log IOCs.
gist.github.com/hkulekci/b7d…

2
238
saw someone build a fast little Spotify desktop app and loved it, but I live in YouTube Music. so I spent a weekend making my own in Rust.
way lighter on memory and cpu. not open sourcing it for now, but happy to send a build if you want to try.
meet Youtufast.

6
206
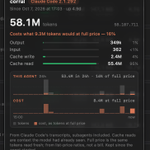
58M tokens. 16% of the price.
95% of this Claude Code agent's tokens were cache reads, so it cost about what ~9.3M fresh tokens would run. I added cost tracking to Corral to see that gap per project.

open source: github.com/popyapp/corral

1
47
got @StartupDealco into the Claude Startups program right before this. now reading "we let way too many people in" with one eye closed, hoping I'm not in the batch they reconsider
teapawt.org/sarahzorah/status/2108…

We didn’t anticipate the demand for the Claude Startups program. In the first 48 hours of the program, we received 21x the number of applications compared to the last 5 months it’s been live.
We let way too many people in this time, so we’ll need to pause on giving out the Team plan and API credits benefits. The other benefits (Startup Stack, Applied AI office hours/events) will remain. If you’ve already claimed the Claude offers, they’ll still remain in your account.
We didn’t properly tune the acceptance criteria at the start, and many non-startups were accepted this time around. We’re fixing this now. We’re sending an email now to everybody who hasn’t claimed their benefits yet, and will re-verify those applications so we can keep Claude Startups for startups 🙏
1
3
180
77x less vector RAM for 94.5% of the quality. the Matryoshka play: truncate the embedding, quantize, then rescore your top candidates at full precision. that rescore step is what stops recall falling off a cliff. quietly a big deal for RAG memory budgets.
teapawt.org/qdrant_engine/status/2…

77× less vector RAM. 94.5% of baseline retrieval quality.
We got early access to Google EmbeddingGemma 2 and tested how far its Matryoshka-compatible embeddings could be compressed in Qdrant.
With shorter vectors + quantization + rescoring, we reduced the vector memory footprint by ~77× while retaining 94.5% of baseline retrieval quality.
Google also featured our work in their EmbeddingGemma 2 announcement.
Qdrant deep dive: qdrant.tech/blog/embeddingge…
Google’s announcement: blog.google/innovation-and-a…

2
1
154
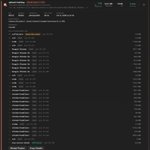
a multi-agent build with Claude Code was eating resources. Corral showed me why in one view.
one agent, 30 child processes under it, mostly headless Chrome it spawned. 3GB total, all hidden behind a single 'claude'.
Activity Monitor never connects those.

open source: github.com/popyapp/corral
3
198
the open models quietly got good. things like GLM are strong enough now that a lot of real coding and tooling work does not need a frontier model or a bill.
worth actually trying one, especially when people are handing out free access. the gap is smaller than the pricing suggests.
teapawt.org/silennai/status/210618…

ok fine, here's free GLM 5.3 Flash uncensored
~13m TPM shared
~360 TPS peak
use it for cybersec, coding, whatever
live at platform.xplabs.ai

77
your client library is already on disk, pinned to a version, and encodes what is valid for it. for Qdrant, parameters shift between releases.
so why trust stale training or latest web docs? the installed package is the version-matched truth. ship the AI context inside it.
1
2
109
llms.txt and AGENTS.md don't quite cover this, the package-local, version-matched case. is anyone standardizing it?
my attempt for qdrant-php: github.com/hkulekci/qdrant-p…
1
41
building AI products with PHP? LLPhant is your LangChain. I contributed to its @qdrant_engine integration, updating it to a current Qdrant version, so PHP teams get proper vector search in their RAG stack.
github.com/LLPhant/LLPhant

3
103
put Laya to work at @startupdealco. as applications come in, I score two things: quality and program fit, instead of asking a chat model to rate them.
Laya returns a calibrated decision, not prose. runs locally with ollaya, a local decision-model runner.
2
3
308
ollaya: github.com/ollaya-dev/ollaya

1
47