

Assistant Prof @TTIC_Connect | Science of Pretraining @ Ai2 Will irl, TC0 enthusiast
Seattle, WA
Joined October 2011
- Tweets1.7K
- Following705
- Followers5.3K
- Likes5.7K





Pinned Tweet
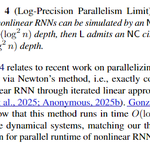
My thesis, 𝘈 𝘵𝘩𝘦𝘰𝘳𝘺 𝘰𝘧 𝘵𝘩𝘦 𝘤𝘰𝘮𝘱𝘶𝘵𝘢𝘵𝘪𝘰𝘯𝘢𝘭 𝘱𝘰𝘸𝘦𝘳 𝘢𝘯𝘥 𝘭𝘪𝘮𝘪𝘵𝘢𝘵𝘪𝘰𝘯𝘴 𝘰𝘧 𝘭𝘢𝘯𝘨𝘶𝘢𝘨𝘦 𝘮𝘰𝘥𝘦𝘭𝘪𝘯𝘨 𝘢𝘳𝘤𝘩𝘪𝘵𝘦𝘤𝘵𝘶𝘳𝘦𝘴, is now online:

Very excited to read this!
at Ai2 we’ve seen CBS can be subtle, and we’ve been begging @SadhikaMalladi to explain the nuances for us

Optimizers are usually benchmarked at one batch size, and scaling rules extend them to different batch sizes. We show: (1) frameworks to derive these rules are not as general as they claim to be, and (2) the best optimizer depends on the batch size. batch-size-scaling.com

I'll be in SF for COLM Tuesday through Sunday. Reach out to my TTIC email if you're at the conf and would like to chat!
re: stochastic parrots, if you're interested in the form/meaning question, this classic is a great read: tandfonline.com/doi/pdf/10.1…
Introducing the Language, Expressivity, Interpretability, and Formalism (LEIF) Lab at TTIC — it's a cool crew!
leif-lab-ttic.github.io/

Open models are foundational for the US research ecosystem, and for a future where LLMs are accessible, safe, and well-understood


Oh and we’re having fun building them at @allen_ai . Lots of cool stuff in the works!
xitter.cf/i_beltagy/status/20678…

Deep conversation about the specs of the next pretraining run on our new B300 cluster.
What do you want to see in a future Olmo release?
With @lambdaviking @RenZhongzheng @TaoTianhua @yashassamaga @jowenpetty
(I am hiring Sr. REs)

Cool to see some more practical instantiation of looped, padded, transformers for reasoning problems!

🚀New paper on Looped Transformers!
Latent reasoning is fast, but struggles to match CoT-level accuracy at scale. Can looped Transformers give us both?
We find: yes! A looped padded backbone turns out to be a surprisingly simple recipe that works -- It gives latent thoughts a parallel workspace that can be supervised similarly to explicit CoT. 🧵

I recommend giving this post a read for some theory x practice + philosophy of science!
and excited to see what comes next for the blog👀
I am starting a blog about deep learning theory and its value to practitioners! First post is about Adam, broken convergence proofs, and what theory can contribute when stuff just works anyways without it. Subscribe on Substack if you like it! undertheassumptions.substack…

William Merrill retweeted

Excited to share our new paper with @lambdaviking! We look beyond aggregate loss and ask which tokens hybrid architectures predict better (than transformer).
Paper link: arxiv.org/abs/2606.20936
OLMo Hybrid’s gains are strongest on semantic/state-tracking tokens, while attention still matters for copying and delimiter matching.


New work from @YanhongLi2062 digging into the specific tokens that hybrid models predict better than transformers 📈
Spoiler alert: gains are broad across token categories, especially large on content words. Gains diminish on copying tokens, but even there hybrids aren't worse
William Merrill retweeted

Deep conversation about the specs of the next pretraining run on our new B300 cluster.
What do you want to see in a future Olmo release?
With @lambdaviking @RenZhongzheng @TaoTianhua @yashassamaga @jowenpetty
(I am hiring Sr. REs)
(re: OpenAI and Anthropic IPO news, a preprint)
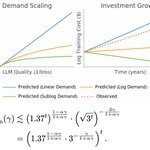
Scaling up training reliably improves LLMs, but it also increases training and inference costs, leading to massive capital expenditure by AI firms. How can we understand what level of LLM scaling is justified economically? 🧵⬇️

Our model enables understanding the interaction of research and market forces in LLM scaling, going beyond Chinchilla. We hope this provides a foundation for engaging critically with industry statements and supporting long-term economic decision making.
Paper link: arxiv.org/abs/2605.16430