

@lcs2lab
🇮🇳Account based in
About this account
- Account based in
- India
- Connected via
- India Android App
Account-level information from X, not a live location or the device used for a specific post.
Lab. for Computational Social Systems, a group led by @Tanmoy_Chak working on #SocialComputing #GraphMining & #NLProc
New Delhi, India
Joined July 2018
- Tweets737
- Following145
- Followers1.2K
- Likes240





🚀 #EMNLP2026 #SneakPeek 🚀 Do multilingual LLMs understand diverse cultures, or do they still favor Western-associated entities? We introduce Camellia, a benchmark for measuring cultural biases across Asian languages and cultures. 🌏
🔗 Paper: aclanthology.org/2026.emnlp-…

⚠️ Language matters: Entity extraction gaps across cultures can reach 12–20% in Asian languages, substantially exceeding those generally observed in English.
🔬 The takeaway: Multilingual capability does not automatically translate into cultural understanding.
Camellia offers a systematic way to measure cultural biases and advance more culturally aware, equitable multilingual LLMs.
#EMNLP2026 #NLProc #ResponsibleAI #MultilingualAI
🚀 #EMNLP2026 #SneakPeek 🚀
Excited to share our work on a key challenge in #MentalHealthAI: How can we generate realistic, clinically grounded counseling dialogues when real therapy data is scarce due to privacy and ethical constraints?
ukplab.github.io/emnlp2026-g…
🧵👇

📊 Graph2Counsel generates 760 synthetic counseling sessions from 76 CPGs.
🏆 Expert evaluation ranks it highest among the compared datasets for specificity, counselor competence, authenticity, conversational flow, and safety, with strong inter-annotator agreement.
🔬 We also introduce Therapy-Eval, a framework for evaluating models through multi-turn simulated counseling conversations. Fine-tuning on Graph2Counsel improves several counseling metrics.
💻 Code: github.com/UKPLab/emnlp2026-…
#NLP #MentalHealthAI #ResponsibleAI #EMNLP2026

🚀 #EMNLP2026 #SneakPeek 🚀
How can we generate counterspeech that doesn't just oppose hate, but understands its underlying claims and responds with the right strategy and supporting evidence?
👥 @sujoynath_ai @aswiniandpunter @Tanmoy_Chak
🧵👇

📚 We introduce FactualCS, a dataset of 4,784 hate–counterspeech pairs across 14 target communities.
📊 FIRE achieves a 0.969 factuality score, improves category accuracy by 11.1%, lowers toxicity by 11.1%, and cuts peak GPU memory by 75% vs. a monolithic 8B model.
🏆 Our work highlights the importance of reasoning before responding: combining hate-category analysis, evidence retrieval, and memory-guided generation for more grounded, effective counterspeech.
#NLP #ResponsibleAI #Counterspeech #HateSpeech #MultiAgentSystems
🚀 #EMNLP2026 #SneakPeek 🚀
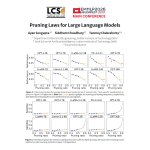
Excited to share our work, Pruning Laws for Large Language Models, to understand trade-offs in efficient LLM deployment.
👥 Ayan Sengupta, Siddhant Chaudhary, Tanmoy Chakraborty
📜 Paper: arxiv.org/abs/2504.04342v2
🧵👇

💻 Code: github.com/parmanu-lcs2/prun…
We hope this work advances a more principled approach to LLM compression, balancing model efficiency with capability preservation.
Congratulations to all the authors! See you in Budapest! 🎉
#ModelPruning #EfficientAI #LLMCompression #ScalingLaws
