

Pinned Tweet
The first AI programmer will be created within the next 1-3 years. It'll be an LLM exposed to a terminal. Unlike chatgpt trained for dialogue, it'll be trained to use the terminal to run commands, browse and edit files, and debug its own code. All the components are already here

Atem Aguer retweeted
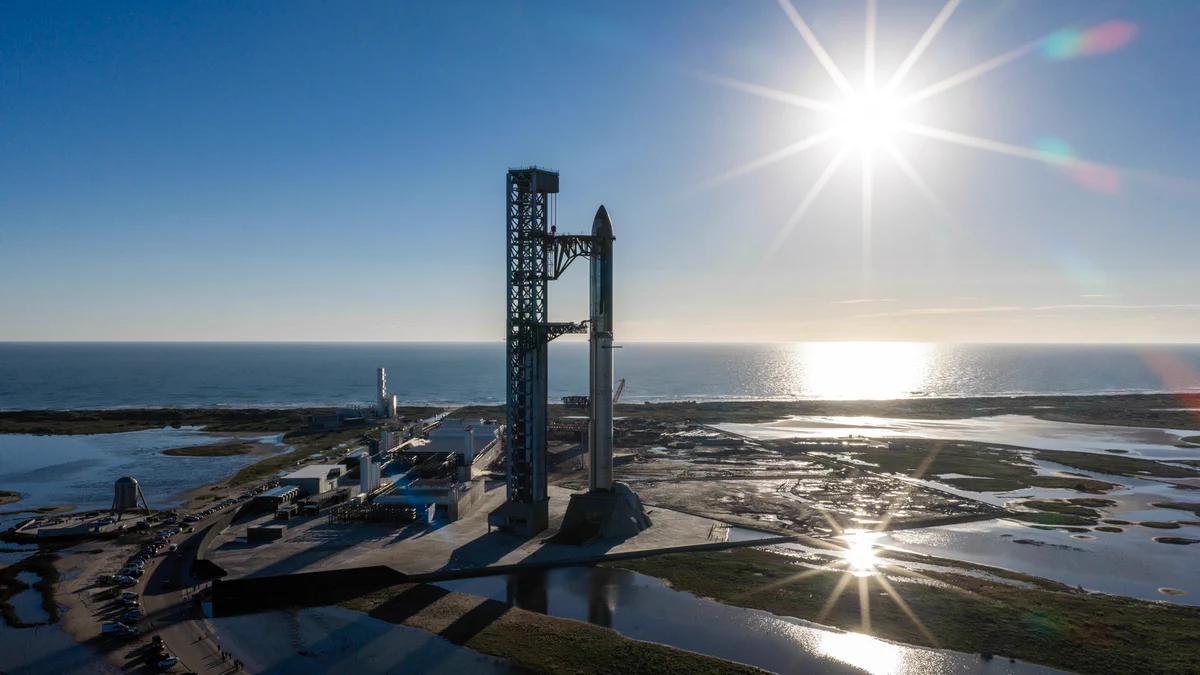
Watch Starship Flight 15
teapawt.org/i/broadcasts/2brajgZlO…
bullish!

A billion people produce the most valuable dataset in the world every day – and delete it every night.
We’re recording it.
Introducing @AttentionInc
16
2,291
as distillation is starting to see wide-spread adoption, i wanted to share a reference tinker implementation for on-policy context/self distillation that i and @rishi_desai2 wrote for our @xai hackathon from last december: github.com/atemaguer/tinker-…


2
18
4,351
we built a self-improving and continually learning ai recruiting agent: devpost.com/software/self-im…

3
300
Atem Aguer retweeted

Can coding agents stay coherent over a 1 billion token budget?
Can they build Slack from scratch?
Rewrite a JAX codebase in PyTorch?
Build a C compiler in Rust?
Enter SWE-Marathon: a benchmark for autonomous long-horizon software work.

Atem Aguer retweeted

Starting today, personal superintelligence is just one tap away.
No download, no signup.
Text Poke for free now:
Poke.com 🌴
—
0:00 – What's Poke?
0:50 – Introducing Poke Recipes
1:25 – Create a Recipe in 10 seconds
1:43 – Earn on Poke
2:44 – Build with npx poke
12:58 – Recap
13:36 – Parisian Love
Atem Aguer retweeted

People keep saying 2026 will be the year of continual learning.
But there are still major technical challenges to making it a reality.
Today we take the next step towards that goal — a new on-policy learning algorithm, suitable for continual learning!
(1/n)

Atem Aguer retweeted

Introducing 💡On-Policy Self-Distillation💡, a simple method that enables LLM to teach itself with dense per-token feedback on its own on-policy generations—achieving 4-8x more token efficiency vs. GRPO and outperforming both GRPO and SFT/Off-Policy Distillation.
Key insight: like a student reviewing solutions, rationalizing them, and correcting prior mistakes, an LLM can be conditioned on privileged info (e.g., correct solution or a reasoning trace) and supervise its weaker self—the version without such access—by matching the privileged-info-induced distribution from itself.
🌐Blog: siyan-zhao.github.io/blog/20…
🧵👇

perfect time to contribute. skyRL tx is pioneering a unique approach to next-gen unified inference and training engines that will be critical for problems like continual learning

Happy new year! We are excited to announce SkyRL tx 0.2.1, see novasky-ai.notion.site/skyrl…. Some highlights of the release include FSDP and multi-node support, Llama 3 model support, custom loss functions, a number of performance improvements and also lots of small fixes that implement more functionality of the Tinker API. The blog post also includes a performance comparison with the Tinker Service! Enjoy the release and happy hacking!

3
312
Atem Aguer retweeted

Happy new year! We are excited to announce SkyRL tx 0.2.1, see novasky-ai.notion.site/skyrl…. Some highlights of the release include FSDP and multi-node support, Llama 3 model support, custom loss functions, a number of performance improvements and also lots of small fixes that implement more functionality of the Tinker API. The blog post also includes a performance comparison with the Tinker Service! Enjoy the release and happy hacking!
if you're already overwhelmed by the current progress in ai capabilities, remember that these growth rates are exponentials of exponentials. things are going to get crazy in 2026. exponential growths happen slowly and then suddenly, how about exponentials of exponentials
The current progress of AI development and research follows @raykurzweil law of accelerating returns(kurzweilai.net/the-law-of-ac…). Human beings already struggle with understanding or keeping up with exponential growth. And yet the current pace is an exponential of an exponential
2
249
how far things have come in 3 years. with this belief in mind, in early 2023, i designed a proto-claude-code called shoggoth (github.com/atemaguer/shoggot…)

The first AI programmer will be created within the next 1-3 years. It'll be an LLM exposed to a terminal. Unlike chatgpt trained for dialogue, it'll be trained to use the terminal to run commands, browse and edit files, and debug its own code. All the components are already here
1
6
496

Atem Aguer retweeted
For small / custom models, you might want to try out github.com/NovaSky-AI/SkyRL/… which is open-source and is working quite well now. You can use your existing Tinker scripts and customize it however you like and the code is quite readable.