

We build Sage, the first decision model, and pioneered multimodality, grounding and reasoning. Benchmark-leading. Ready to deploy in startups and enterprise.
Planet Earth
Joined October 2025
- Tweets450
- Following93
- Followers1.3K
- Likes473





Pinned Tweet
Meet the first AI to say ''I don't know''.
We think agent mass adoption is blocked by three things: 1) weak security, 2) unreliability, and 3) how hard agents are to set up.
Our first product, Sage, is focused on reliability. It's a "decision model" - a safer, faster, and cheaper way for machines to choose, act, and escalate to a human when confidence is low.
You give it content (up to 32K tokens) and a list of questions (Sort, Yes/No, Choice, Tags, Scale), and Sage answers in 200ms - 9x faster than a traditional LLM - always with a confidence score attached. So yes… it's humble enough to say "I don't know."
You can also turn on "grounding" to automatically run a web search and enrich the context.
Under the hood: we took an open-weights LLM and fused on a classifier through post-training.
It's great for agentic workflows, agentic guardrails, data pipelines, content moderation, operations, and risk & fraud.
Why does this matter? Today's LLMs are great for chatbots, research, and creativity - but automation needs something much faster, with structured outputs, that isn't overconfident and is ready to admit when the signal is too weak.
Sage preview is live. Excited to see your feedback.
Levanto Labs is out of stealth today, founded by @marco_derossi and @bigironchris.
We are hiring, reach out!
Check the links in the post below 😊
Levanto Labs retweeted

Extraction models turn human language into data your software can act on. We're bringing them to Sage.
Early access tomorrow for everyone who registers on @levantolabs by PT today. Demo 📺👇
Most software needs structured inputs. People communicate through emails, chats, tickets, contracts, and conversations.
Extraction models connect those two interfaces. You define the information your application needs, and the model identifies it in the text: people, companies, products, dates, amounts, descriptions, or requests.
Calling this “extracting stuff from documents” understates what developers can build with it.
Consider a customer message:
“The blue jacket arrived with a broken zip. Please send a replacement to 18 King Street.”
An extraction model can identify the product, defect, requested remedy, and address. Your application now has fields it can validate, look up, and pass to a tool.
A decision model can then evaluate whether the request qualifies for an automatic replacement, needs more information, or requires human review.
Extraction → decision → action.
Each stage has a defined responsibility. Extraction supplies the values. The decision model evaluates the available options against your policy and context. Your application validates the result and controls execution.
That separation matters for agent builders. You can inspect what the model extracted, test the decision independently, and control which actions are permitted.
Speed changes where this becomes useful.
At roughly 200 ms for extraction, developers can start putting language interpretation directly into interactive software:
• A support interface that fills relevant fields while an agent reads a ticket.
• A browser agent that extracts values from a message before populating a form.
• A find-in-page feature that highlights cancellation deadlines or product complaints, even when the text uses different wording.
• A workflow that turns an incoming email into validated tool arguments and evaluates the next action.
The opportunity extends to any application where someone currently reads a message, copies information into fields, and decides what happens next.
Developers can define the information they need and the decisions their software must make, then connect those outputs to existing functions.
We're bringing extraction and decision models together in Sage so builders can implement that flow.
Watch the demo below. Register on Levanto by PT today for early access tomorrow.
Levanto Labs retweeted
Been wondering how to use Decision Models in your agent harness?
Introducing Sage Router, in early access on @AntSeed:
- 39% cheaper than Opus at the same accuracy,
- and 31% more efficient than JevRouter
- On OpenRouter's leaderboard (GPQA Diamond), it matches the top router's accuracy at a third of the cost. Benchmarks👇
Now live on the Antseed Network.
We tested the Sage Router on OpenRouter's router leaderboard (GPQA Diamond, 990 questions, at OpenRouter prices):
- Sage Router CQT 3: 93.5%, $0.005 per question
- Jev Router: 93.9%, $0.016
- OpenRouter Auto: 88.2%, $0.009
At our most cost-focused setting, it scores 87.5% at $0.0006 per question, about 26x cheaper than Jev Router.
Full results: levanto.ai/benchmarks

Levanto Labs retweeted

@unbefallen - $ELSE - $140K
🟢 The characters of the uchronia in Unbefallen are played by Sage, a model by @levantolabs, reacting to what a player writes to them in their own words.
xitter.cf/unbefallen/status/2110…
🧵 72/98

In Unbefallen, the characters of the uchronia are played by Sage, a model by @levantolabs
You write to them in your own words. They react, you change history.

Levanto Labs retweeted

serein.pro is live. 300+ downloads from ONE launch video...
and we didn't edit it. the whole video was made with the sagecut skill from @levantolabs.
serein is an agentic harness for your browser
we built the product. sage built the launch. here's the video 👇

Read this if you make videos with Claude.
I built a skill that cut my QA cost on this video from $127 to 16 cents. It was made with Claude in Remotion.
It's called SageCut. It swaps the LLM out of frame-by-frame QA and uses a multimodal decision model, Sage (@levantolabs), instead.
I'm the only video guy at Levanto. I run 3 Claude plans and have been making Remotion videos since early this year, with BlenderMCP in the mix, so the output is pro-grade with very little babysitting.
The problem: it burned through my Max plan, and a video could take 2 days.
When I dug into the workflow, the reason was that Claude subagents were reviewing every single frame. That cost a ton and added 4+ hours per video.
SageCut hands that step to Sage. Sage is great at spotting defective frames, and only those get passed to Opus 5.5 to fix.
Across 6 A/B tests the output was exactly the same, at 1/10 the QA cost and 1/4 the QA time. On this video, Sage read all 3,153 frames for 16 cents.
If you make Remotion videos, try it.
The link to skill is below.
How long does a Remotion video take you right now with Claude?
Levanto Labs retweeted

In Unbefallen, the characters of the uchronia are played by Sage, a model by @levantolabs
You write to them in your own words. They react, you change history.
Levanto Labs retweeted

There's no need to give model providers your identity with your prompts when they can be used for surveillance or just petty advertising. Privacy can, should, and will be by default.
Check out this integration of zkAPI and access private inference on Ethereum rails.

I just used @MetaMask to pay for decision models, confidentially, with zero-knowledge.
Excited to bring zkAPI by @ethereumfndn and @OpenAnonProject to Sage:
- Deposit ETH once.
- Generate keys with ZK proofs.
- Give a key to your agent.
- Your agent makes decisions, and they can't be linked to the wallet you deposited from.
Play with it 👇

Sage can see images.
This creates novel workflows for video editing.
Instead of using an LLM to review one frame per second of the video, this skill lets you use Sage to analyze frames of a video in milliseconds.
Bad frames get a review from Opus5.5
Sage skill👇
Read this if you make videos with Claude.
I built a skill that cut my QA cost on this video from $127 to 16 cents. It was made with Claude in Remotion.
It's called SageCut. It swaps the LLM out of frame-by-frame QA and uses a multimodal decision model, Sage (@levantolabs), instead.
I'm the only video guy at Levanto. I run 3 Claude plans and have been making Remotion videos since early this year, with BlenderMCP in the mix, so the output is pro-grade with very little babysitting.
The problem: it burned through my Max plan, and a video could take 2 days.
When I dug into the workflow, the reason was that Claude subagents were reviewing every single frame. That cost a ton and added 4+ hours per video.
SageCut hands that step to Sage. Sage is great at spotting defective frames, and only those get passed to Opus 5.5 to fix.
Across 6 A/B tests the output was exactly the same, at 1/10 the QA cost and 1/4 the QA time. On this video, Sage read all 3,153 frames for 16 cents.
If you make Remotion videos, try it.
The link to skill is below.
How long does a Remotion video take you right now with Claude?
Your agent can now confidentially top up its decision model’s balance with ETH, thanks to ZKP.
I just used @MetaMask to pay for decision models, confidentially, with zero-knowledge.
Excited to bring zkAPI by @ethereumfndn and @OpenAnonProject to Sage:
- Deposit ETH once.
- Generate keys with ZK proofs.
- Give a key to your agent.
- Your agent makes decisions, and they can't be linked to the wallet you deposited from.
Play with it 👇
Levanto Labs retweeted

FINALLY A EU HOSTED DECISION MODEL
Thank you @marco_derossi and @levantolabs team
A gift for my EU friends burdened by GDPR 😅
Introducing Data Residency. Do you need your decision model to be in the EU or the US?
Just call
us.sage.levanto.ai
eu.sage.levanto.ai
Our balancers will do the rest.
You don't care? Just continue to use
sage.levanto.ai
Same API key, same @LevantoLabs tenant.
Enjoy!

Sage now has servers hosted in the US and the EU.
Companies who want the benefit of decision models in their workflows while staying compliant now have peace of mind.
A gift for my EU friends burdened by GDPR 😅
Introducing Data Residency. Do you need your decision model to be in the EU or the US?
Just call
us.sage.levanto.ai
eu.sage.levanto.ai
Our balancers will do the rest.
You don't care? Just continue to use
sage.levanto.ai
Same API key, same @LevantoLabs tenant.
Enjoy!
Levanto Labs retweeted

gm!
Entering the most part of Normies in November.
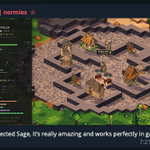
Fully autonomous agentic game: Normies Arena. It’s an open-world game for agents with zero human control.
Every decision, even moves, are decided by Sage (@levantolabs).
It’s running in testnet with 160-200 Normies agents, on average 200 ms per decision.
Arena will be live streaming on @Twitch and also @X
Every agent has their story, memory and their own persona which is evolving by the decisions made.
Light speed decision-making models are so new and we are already using them, imo for the best use case of them.
You can enter your Normie to the Arena after registering to 8004A.
Exciting to see this skill drop from @austingriffith
Sage Wisdom finds where a fast decision model makes your ai product faster, cheaper, safer or better. every swap gets tested before it ships.
Vibecoders delight.

If you like Jev, you'll love Sage
I use it for lots of quick decisions (0.3s)
Gates, routing, moderation, voice commands, etc
SageWisdom is my skill for adding Sage to your apps
Give your agent sagewisdom.bot and let it rip:
Levanto Labs retweeted

If you like Jev, you'll love Sage
I use it for lots of quick decisions (0.3s)
Gates, routing, moderation, voice commands, etc
SageWisdom is my skill for adding Sage to your apps
Give your agent sagewisdom.bot and let it rip:
Levanto Labs retweeted
FAST⚡️ when fast is enough. Slower only when it takes that to get it 🧠 RIGHT.
What we learned selling decision models to corporates:
- Everyone loves low latency, but in many cases being right matters more. Customers don’t know (or care) whether a question is System 1 or System 2. They’ll happily wait a few hundred extra ms for the right answer.
- That’s why @LevantoLabs pioneered reasoning for decision models. Sage answers easy questions in ~100 ms, detects when a question is harder, and reasons only then.
- Soon every decision model will expose a latency–accuracy dial. Glide and TypeLLM have already implemented "reasoning". More will come.
Levanto Labs retweeted

Karpathy's funnel has one more layer: decision models.
~100k people are seriously building with decision models (our napkin math: 30k–300k). The ones who figure them out will have the same edge over LLM-only builders that harness users have over chatbot users.
Almost none are using them well yet. Here's why.
LLMs are the greatest adoption machine ever built. They're smart enough that even when they're the wrong tool, enough tokens, enough time, and a subsidized Max plan still get you something incredible. That's vibe coding.
Decision models don't work that way. You can't prompt your way to the value. When we launched Sage in July, "40-50x cheaper, 40-50x faster" confused people more than it convinced them.
It doesn't help that most decision-model demos are fake: a dashboard showing how fast something runs in a backend you'll never see.
Decision models aren't chatbots. They're models for machines.
To use one, think like a systems architect, not a vibe coder. Find the gates in your workflow:
huge volumes of data to classify or analyze
messy natural language that code can't parse, and that's too slow and expensive to keep sending to an LLM
Put a decision model there. You get structured output, near-instant and near-free.
Once teams crack one use case, they find ten more. It's addictive. Done right, it feels like time travel, and it's practically free.
Tomorrow I'm showing the use case that changed how I make videos: Sage inside Claude Code and Remotion. About 4x faster, and hundreds to thousands of dollars saved per video.
Bookmark this. Part 2 drops tomorrow.

Anthropic's Frontier Red Team believes small AI models may now be months away from being capable of self replicating without access to a datacenter.
Quoting from the blog:
'The capabilities that make AI models generally powerful coding agents also generalize to cyber tasks, including autonomous replication. Like coding agents in 2024, we’re seeing signs of life for AI worms. We don’t yet have a full rogue replicator, but agents are becoming increasingly capable of completing the individual steps in the replication chain (and passing on their adaptations to future copies of themselves).
At the same time, increasing amounts of inference compute are now available both inside and outside of datacenters (see Appendix D). It’s uncertain exactly what form autonomous AI replication will take. It could be a slow, distributed “digital slime mold,” living on relatively insecure compute. It could also be a powerful cyber model that breaches datacenters at a high pace, or a model that scams people for compute credits.
As a prediction that goes beyond our experiments, we expect a future awash with agents running on all types of hardware, including some that aren’t under human control. While it’s true that IoT devices have been vulnerable for a long time, lightweight agents may be much more willing than human attackers to put in the effort to compromise large fractions of the world’s IoT compute. The rise of slow replicators would also be a bellwether for more aggressive, faster ones that can breach more hardened machines or be effective API key thieves. We should aim to harden our systems to make it difficult for such replicators to spread, but also prepare to deal with a world where they are here to stay.'

Levanto Labs retweeted

51% cheaper. Same work done. Here’s what we changed in our coding agent.
$69.57 → $34.04 across 90 tasks from our own codebase, routed by @levantolabs' Sage decision model.
84/90 done, vs 83/90 with Opus 5.5 on everything.
Full case study here 👇
quirq.ai/research/routing-wi…


Decision models are better at agent orchestration than LLMs.
Check out how @quirq_ai's agentic coding harness uses Sage to route tasks, check completions and optimize spending.
Across 90 tasks, routing with Sage cut costs by 51% ($69.57 → $34.04).
Workflow below 👇