

I’m a PhD researcher @MSFTResearch @Caltech @RPI, prev @NECLabsAmerica @AsariAILabs working on LLM-agents, reasoning, RL, test-time scaling, and code generation
San Francisco, CA
Joined June 2023
- Tweets342
- Following905
- Followers931
- Likes1.1K



Pinned Tweet
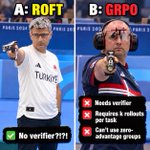
We trained an AI agent on its own explanations, not its code.
It got better at coding.
No teacher. No verifier. No RL updates. No extra context at test time.
Here's how. Links below. 🧵

Thanks for sharing our work on ROFT!

Many of the winning ideas in RL and post-training for reasoning are simple and elegant.
This post covers a line of work I liked. Each paper has a simple idea at its core, and together they ask one question: how do you keep learning when rewards are sparse and most attempts fail?
1. Hindsight Experience Replay (HER, OpenAI 2017)
arxiv.org/abs/1707.01495
tl;dr: "You failed the task. Did you succeed at some other goal along the way? Learn from that."
A failed episode gives no reward, so it's useless for RL. But the agent still ended up somewhere. HER relabels the episode as if that was the goal all along, so failures turn into successes for other goals and give real gradients. The original demos were a robotic arm.
2. Hindsight Supervised Learning (HSL, "Spinning Straw into Gold")
arxiv.org/abs/2607.04235
tl;dr: "HER for LLM agents: an LLM finds which goals a failed run actually achieved, then you SFT on those."
An agent that fails its task usually still accomplishes something. A strong LLM, the "relabeler," reads the trajectory and writes the instruction it actually fulfilled. Steps that don't matter for the new goal are masked out. The relabeled trajectories are mixed with the expert data and trained with plain supervised fine-tuning, with no RL.
3. Self-Distillation Fine-Tuning (SDFT, "Self-Distillation Enables Continual Learning")
arxiv.org/abs/2601.19897
tl;dr: "Let the model see a worked example, then grade its own attempt token by token."
It's closely related to OPSD (arxiv.org/abs/2601.18734) and SDPO (arxiv.org/abs/2601.20802), all from January 2026.
- The student samples a response to the prompt.
- The teacher is the same model, but its prompt also has privileged information, here a demonstration of how to do the task.
- The teacher reads the student's own tokens up to step t and gives its distribution over the next token, meaning what it would write from there. The student is trained to match it.
- Because training happens on the student's own samples, it's on-policy, and it forgets much less than SFT.
- In practice, the teacher is an EMA (a slowly updated copy) of the student. The loss is forward KL(teacher || student), so the student has to cover every option the teacher considers plausible.
4. HERO: Hindsight-Enhanced Reflection from Environment Observations
arxiv.org/abs/2606.11559
tl;dr: "For a multi-turn agent, have the model write a hindsight hint for each turn, then self-distill with those hints."
Multi-turn agents, such as ReAct-style tool loops, have a credit assignment problem. The reward comes at the end, and GRPO gives every turn the same credit.
After the episode, the same model acts as a "reflector." It reads the whole trajectory, the tool outputs and the rewards, and writes a short hint per turn about what was right or wrong and how to fix it. Then a teacher (an EMA copy) gets that turn's history, the next observation, the final reward and the hint, and scores the student's original tokens for that turn. It's SDFT-style distillation, with the hint as the privileged information.
Everything depends on how good the reflector is. The reflector sometimes blames a late turn for a mistake made earlier.
5. Retrospection-Only Fine-Tuning (ROFT, a few weeks ago)
arxiv.org/abs/2609.35741
tl;dr: "Ask the model what it should have done differently, then fine-tune it on its own answer."
After a reasoning attempt, the model gets a retrospection prompt with the task, a compressed summary of its trajectory, its patch and the test results. It writes a short retrospection about the key decision, the evidence, the fix, and when the lesson applies. Then you run plain SFT with the retrospection prompt as input and the retrospection as the target. It trains only on these retrospections and not on the original tasks.
The surprise is that learning to explain improves how the model acts. The authors' hypothesis is that predicting the retrospection updates the same weights that represent the model's own actions, but it's still not clear why it works.
It's very efficient. It runs online, with the current model writing both the attempts and the retrospections, and it learns from failed attempts too.

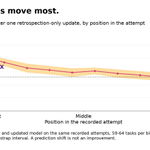
Your RL loss treats turn 1 and turn 40 as equally worth fixing. It shouldn’t. Early decisions constrain everything after them.
Retrospection-only training gets this without being told: after one update, the first tenth of the attempt shifted 1.6x as much as the late turns!


Jonathan @COLM retweeted

We at @bespokelabsai have a solid blog post for you guys with details on how to train a model towards becoming an autonomous ML researcher.
We curated high quality RL envs and used some new post-training techniques to improve Nemotron Super to be as good as a model 20x the size.
Details: bespokelabs.ai/blog/teaching…
We partnered with @NVIDIAAI for this work: developer.nvidia.com/blog/nv…


We are excited to announce that we post-trained NVIDIA Nemotron-3.5-Super-VL to be an autonomous ML researcher. We show that our post-trained model goes from 28% to 35% on AutoResearchExam, matching Qwen 3.8 Max, a model with 20× the total parameters.
The tasks are long horizon, open ended AI and ML research: building a faster executor for a transformer compute graph, training a RL control policy, creating new uncertainty quantification methods, etc. The model gets to submit once, and it doesn't see its score until the end.
We curated SFT data using Self-context distillation. This means that we let the Nemotron model to solve a problem with hints, then we SFT on these trajectories but without the hints. This gave us +11% on AutoResearchExam.
As a next step, we added reflection: We ask the Nemotron model to review its own past attempts and writes concrete lessons learned. Then we SFT on these reflections.
Surprisingly, training on these lessons improved the performance to +25% compared to the base model.
The hardest part was choosing the right data. We selected traces based on task scores, completion checks, and runtime, then refined the sampling across training rounds to address failures in the base and fine-tuned models. We removed hints and filtered out steps that relied on information available only in those hints. The goal was to teach decisions supported by the task and history the model would actually see at inference.
Full write-up:
bespokelabs.ai/blog/teaching…
Thanks to @NVIDIAAI for early access and collaborating on this.

Excited to see Bespoke Labs build on our ROFT work for autonomous ML research!
Their recipe combines context distillation, self-generated retrospections, and action replay -- improving Nemotron’s AutoResearchExam score by ~25% vs. base.
Learning to explain → learning to do 🧠
We are excited to announce that we post-trained NVIDIA Nemotron-3.5-Super-VL to be an autonomous ML researcher. We show that our post-trained model goes from 28% to 35% on AutoResearchExam, matching Qwen 3.8 Max, a model with 20× the total parameters.
The tasks are long horizon, open ended AI and ML research: building a faster executor for a transformer compute graph, training a RL control policy, creating new uncertainty quantification methods, etc. The model gets to submit once, and it doesn't see its score until the end.
We curated SFT data using Self-context distillation. This means that we let the Nemotron model to solve a problem with hints, then we SFT on these trajectories but without the hints. This gave us +11% on AutoResearchExam.
As a next step, we added reflection: We ask the Nemotron model to review its own past attempts and writes concrete lessons learned. Then we SFT on these reflections.
Surprisingly, training on these lessons improved the performance to +25% compared to the base model.
The hardest part was choosing the right data. We selected traces based on task scores, completion checks, and runtime, then refined the sampling across training rounds to address failures in the base and fine-tuned models. We removed hints and filtered out steps that relied on information available only in those hints. The goal was to teach decisions supported by the task and history the model would actually see at inference.
Full write-up:
bespokelabs.ai/blog/teaching…
Thanks to @NVIDIAAI for early access and collaborating on this.
Jonathan @COLM retweeted

We saw the exact same. SFT on insights and direct-transfer rollouts with removed insights arxiv.org/abs/2609.37633. Another work around @lightetal found +/- the same arxiv.org/abs/2609.35741. Nice to see that several labs find this concurrently and independently. We're up to sth :)

Jonathan @COLM retweeted

New MIT paper says give your agent its own history and prompt as code variables it can search and pass to subagents, and a plain agent loop beats purpose-built memory and self-improvement systems at lower cost.
Agents lose instructions when they copy context into subagents by hand, and passing the prompt and history by reference let JAZ beat dedicated memory and self-tuning systems.
Long-term memory and self-improvement usually need extra systems like Letta or ACE, which add cost and break when tasks don't fit their design.
JAZ keeps only the loop. The model writes Python, calls itself as a subagent, and sees its prompt and full history as variables it can pass along without loss.
On StuLife tasks that needed facts from over 50 tasks earlier, JAZ passed 69.9% against 61.8% for Letta, at less than half the cost. Improving itself across 417 AppWorld tasks, it completed 74.2% against 69.9% for ACE, again for less.
– arxiv. org/abs/2609.26891
Title: "Harness as a Language: A Minimalist Agent Framework With Maximal Expressivity"

Want credit assignment over long-horizon agent tasks?
Your model can do it for itself. No per-turn labels. No value model. No RL.
Train it only on its own reflections, and its correct turns gain likelihood more often than its incorrect ones. GRPO barely tells them apart.


Jonathan @COLM retweeted

What I read at #COLM2026: the 5 papers I liked most, ranked by community likes:
1. IdeaScientist: agents trained with RL to generate grounded research ideas. @Jiarui_Liu_
xitter.cf/Jiarui_Liu_/status/210…
2. LLM-as-a-Verifier: a weaker model checking a stronger one’s work. @Azaliamirh
xitter.cf/Azaliamirh/status/2108…
3. CORAL: autonomous multi-agent evolution for open-ended discovery. @ao_qu18465
xitter.cf/ao_qu18465/status/2108…
4. Actor-Curator poster. @lightetal
xitter.cf/lightetal/status/21082…
5. GitSwarm: inference that builds on itself across long tasks. @veds_12
xitter.cf/veds_12/status/2108605…
My overall impression is that verification is now the bottleneck for both agents and reasoning. Which COLM paper did I miss?

Excited to share IdeaScientist, our research from my internship at Meta! 🚀
Can AI agents learn to generate novel, grounded scientific ideas?
We introduce IdeaScientist, a framework that trains specialized agents to identify research gaps, discover useful connections across scientific domains, and turn them into concrete research proposals.
🔍 Key findings:
• +14% overall performance over open autoresearch baselines
• 25% improvement in novelty, showing that explicit training can improve scientific ideation
• 75–92% human preference win rates against six open baselines in blind evaluations
• Cross-domain retrieval substantially improves the transfer of ideas between research fields
We also introduce Svalbard Idea Vault, a collection of 2.77M decomposed research ideas for training and evaluating scientific ideation.
📄 Paper: arxiv.org/abs/2610.04074

Our Actor-Curator poster at #COLM26
in case you missed it yesterday :)

Post-training LLMs is like mixing a cocktail:
Too much easy data → no learning
Too much hard data → instability
Wrong balance → collapse
And today, we mix it by hand.
What if the data mixture could be learned instead of hand-tuned?
arxiv.org/abs/2602.20532
🧵👇

Jonathan @COLM retweeted

At #COLM2026? Care about RL and Curriculum Learning for Agents? Do bandit research?
Come chat with us about Actor–Curator this afternoon! 🕟 Today, Oct 7, 4:30–6:30 PM PDT
📍 Poster #100, Franciscan C Hilton San Francisco Union Square

Actor-Curator does self-curriculum design for post-training, by dynamically choosing task difficulty instead of hand-mixing data. Yields up to 80% faster convergence compared to vanilla post-training.
Awesome work by @zhengyao_gu @lightetal @ihazelye @zou_henry43378
Jonathan @COLM retweeted

Shockingly Simple Self-retrospection Improves Agentic Models Without RL
"Can a language-model agent improve its future actions by training only on explanations of its own experience? We investigate this question by studying Retrospection-Only Fine-Tuning (ROFT), a minimal online procedure designed to isolate the effect of explanation-only training on subsequent behavior. The agent attempts a task, observes available feedback, generates a retrospective explanation, and is fine-tuned with a next-token prediction loss on the explanation tokens alone."
link: arxiv.org/abs/2609.35741

At #COLM2026? Come chat about Actor–Curator this afternoon! Happy to talk curriculum learning, bandits, and RL post-training, or just say hi 👋
🕟 Today, Oct 7, 4:30–6:30 PM PDT
📍 Poster #100, Franciscan C
Hilton San Francisco Union Square
Post-training LLMs is like mixing a cocktail:
Too much easy data → no learning
Too much hard data → instability
Wrong balance → collapse
And today, we mix it by hand.
What if the data mixture could be learned instead of hand-tuned?
arxiv.org/abs/2602.20532
🧵👇

I’ll be at @COLM_conf in San Francisco this week presenting our latest work on curriculum learning for RL post-training! #COLM26
Feel free to hit me up if you want to chat about agents, post-training, agentic coding, and self-improvement!
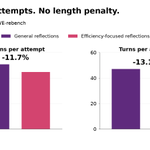
Can a coding agent learn to use fewer tokens and turns, without a length penalty?
We asked it to reflect on how to reach the solution faster, then trained it on those reflections.
11.7% fewer tokens. 13.1% fewer turns.
Compared with training on general reflections.

Retrospections can help steer model behavior without explicit reward shaping.
For details, see arxiv.org/abs/2609.35741
