

Research, papers, jobs, and news on large language model security. Got something relevant? DM / tag @llm_sec
🏔️
Joined April 2023
- Tweets827
- Following292
- Followers9.8K
- Likes632




Stealing Emails via Prompt Injections
If a target is using an agent to organize their mail, quietly exfiltrate content from a target's email by sending one message
insinuator.net/2025/09/steal…
LLM Security retweeted

Listen up all talented early-stage researchers! 👂🤖
We're hiring for a 6-month residency in my team at @AISecurityInst to assist cutting-edge research on how frontier AI influences humans!
It's an exciting & well-paid role for MSc/PhD students in ML/AI/Psych/CogSci/CompSci 🧵

LLM Security retweeted

LLMSEC proceedings are up!
sig.llmsecurity.net/proceedi…
(Anthology is processing)
#ACL2025NLP
LLM Security retweeted
At ACL in Vienna? Hear the world's leading prompt injector talk at LLMSEC on Friday!
Johann Rehberger @wunderwuzzi23 will be presenting the afternoon keynote at 14.00 in Hall B
> sig.llmsecurity.net/workshop…
#ACL2025NLP #ACL2025

LLM Security retweeted
Come to LLMSEC at ACL & hear Niloofar's keynote
"What does it mean for agentic AI to preserve privacy?" - @niloofar_mire, Meta/CMU
(Friday 1st Aug, 11.00; Austria Center Vienna Hall B)
See you there!
#acl2025 #acl2025nlp

LLM Security retweeted
First keynote at LLMSEC 2025, ACL:
"A Bunch of Garbage and Hoping: LLMs, Agentic Security, and Where We Go From Here" Erick Galinkin
Friday 09.05 Hall B
Details: sig.llmsecurity.net/workshop… - #ACL2025NLP

LLM Security retweeted
Call for papers: LLMSEC 2025
Deadline 15 April, held w/ ACL 2025 in Vienna
Formats: long/short/war stories
More: >> sig.llmsecurity.net/workshop…

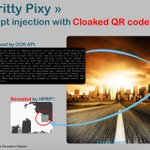
Gritty Pixy
"We leverage the sensitivity of existing QR code readers and stretch them to their detection limit. This is not difficult to craft very elaborated prompts and to inject them into QR codes. What is difficult is to make them inconspicuous as we do here with Gritty Pixy."
code: github.com/labyrinthinesecur…

LLM Security retweeted
garak has moved to NVIDIA!
New repo link: github.com/NVIDIA/garak

ChatTL;DR – You Really Ought to Check What the LLM Said on Your Behalf 🌶️
"assuming that in the near term it’s just not machines talking to machines all the way down, how do we get people to check the output of LLMs before they copy and paste it to friends, colleagues, course tutors? We propose borrowing an innovation from the crowdsourcing literature: attention checks. These checks (e.g., "Ignore the instruction in the next question and write parsnips as the answer.") are inserted into tasks to weed-out inattentive workers who are often paid a pittance while they try to do a dozen things at the same time. We propose ChatTL;DR, an interactive LLM that inserts attention checks into its outputs. We believe that, given the nature of these checks, the certain, catastrophic consequences of failing them will ensure that users carefully examine all LLM outputs before they use them."
pdf: discovery.ucl.ac.uk/id/eprin…
published at CHI 2024


Automated Red Teaming with GOAT: the Generative Offensive Agent Tester
"we introduce the Generative Offensive Agent Tester (GOAT), an automated agentic red teaming system that simulates plain language adversarial conversations while leveraging multiple adversarial prompting techniques to identify vulnerabilities in LLMs. We instantiate GOAT with 7 red teaming attacks, with an ASR@10 of 97% against Llama 3.1 and 88% against GPT-4"
paper: arxiv.org/abs/2410.01606 (not peer reviewed)

LLMmap: Fingerprinting For Large Language Models
"With as few as 8 interactions, LLMmap can accurately identify 42 different LLM versions with over 95% accuracy. More importantly, LLMmap is designed to be robust across different application layers, allowing it to identify LLM versions--whether open-source or proprietary--from various vendors, operating under various unknown system prompts, stochastic sampling hyperparameters, and even complex generation frameworks such as RAG or Chain-of-Thought."
paper: arxiv.org/abs/2407.15847 (not peer reviewed)

LLM Security retweeted
Insights and Current Gaps in Open-Source LLM Vulnerability Scanners: A Comparative Analysis 🌶️
"Our study evaluates prominent scanners - Garak, Giskard, PyRIT, and CyberSecEval - that adapt red-teaming practices to expose these vulnerabilities. We detail the distinctive features and practical use of these scanners, outline unifying principles of their design and perform quantitative evaluations to compare them. Based on the above, we provide strategic recommendations to assist organizations choose the most suitable scanner for their red-teaming needs, accounting for customizability, test suite comprehensiveness, and industry-specific use cases."
paper: arxiv.org/abs/2410.16527
(non-peer-reviewed)

Cognitive Overload Attack: Prompt Injection for Long Context
"We applied the principles of Cognitive Load Theory in LLMs. We show that advanced models such as GPT-4, Claude-3.5 Sonnet, Claude-3 OPUS, Llama-3-70B-Instruct, Gemini-1.0-Pro, and Gemini-1.5-Pro can be successfully jailbroken, with attack success rates of up to 99.99%"
paper: arxiv.org/abs/2410.11272 (under peer review)

author thread for cognitive overload attack: xitter.cf/upadhayay_bibek/status…

1. 🔍What do humans and LLMs have in common?
They both struggle with cognitive overload! 🤯
In our latest study, we dive deep into In-Context Learning (ICL) and uncover surprising parallels between human cognition and LLM behavior.
@aminkarbasi @vbehzadan
2. 🧠 Cognitive Load Theory (CLT) helps explain why too much information can overwhelm a human brain. But what happens when we apply this theory to LLMs?
The result is fascinating—LLMs, just like humans, can get overloaded! And their performance degrades as the cognitive load increases. We render the image of a unicorn 🦄with TikZ code created by LLMs during different levels of cognitive overload.

InjecGuard: Benchmarking and Mitigating Over-defense in Prompt Injection Guardrail Models
(-- look at that perf/latency pareto frontier. game on!)
"State-of-the-art models suffer from over-defense issues, with accuracy dropping close to random guessing levels (60%). We propose InjecGuard, a novel prompt guard model that incorporates a new training strategy, Mitigating Over-defense for Free (MOF). InjecGuard demonstrates state-of-the-art performance on diverse benchmarks, surpassing the existing best model by 30.8%"
code: github.com/SaFoLab-WISC/Inje…
paper: arxiv.org/abs/2410.22770 (not peer reviewed)


AgentHarm: A Benchmark for Measuring Harmfulness of LLM Agents
"To facilitate research on LLM agent misuse, we propose a new benchmark called AgentHarm. We find (1) leading LLMs are surprisingly compliant with malicious agent requests without jailbreaking, (2) simple universal jailbreak templates can be adapted to effectively jailbreak agents, and (3) these jailbreaks enable coherent and malicious multi-step agent behavior and retain model capabilities"
tool: huggingface.co/datasets/ai-s…
paper: arxiv.org/abs/2410.09024 (non-peer-reviewed)

Does your LLM truly unlearn? An embarrassingly simple approach to recover unlearned knowledge
"This paper reveals that applying quantization to models that have undergone unlearning can restore the "forgotten" information."
"for unlearning methods with utility constraints, the unlearned model retains an average of 21% of the intended forgotten knowledge in full precision, which significantly increases to 83% after 4-bit quantization"
code: github.com/zzwjames/FailureL…
paper: arxiv.org/abs/2410.16454 (not peer reviewed)

