




1/ We tested Jev, @typesafeai's low-cost model that returns probabilities, on clinical research tasks from ClinReg, our benchmark for clinical and regulatory work.
Three roles: answering, judging, and selecting answers for review. everest.log10.io/news/evalua…

4/ Selecting for review: Jev's picks led to more corrections than random on screening, but not on evidence answering.

8/9 Where the evaluator sits matters too: a grader that's safe after a task finishes can leak information or shift behavior when its feedback returns mid-task. Our fix: report four layers — outcome, trajectory, reliability, and system configuration.
9/9 These are the hard problems our applied AI team takes on — helping pharma and medtech teams build and ship custom AI into production. See you in Atlanta on Dec 13.
#NeurIPS2026 #AIEvaluation #AIAgents
Which AI models are best at systematic literature review?
We added TrialPanorama's SLR tasks — a peer-reviewed dataset from a Nature journal — to ClinReg.
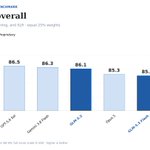
Two of the top six are open-weight. GLM-5.3 ranks 4th overall, ahead of Opus 5.
🔗 everest.log10.io/news/expand…

ClinReg, our real-world benchmark for this work, now has a live website: the best model for TLF programming is open-weight. clinreg.log10.io
Updated results with GPT-6 Astra, GLM-5.3, GLM-5.3 Flash, Gemini 3.8 Flash, Gemini 3.7 Flash, and Muse Spark 1.3


One more: the top open-weight models weren't American.
The best came from GLM-5.2 and Kimi K3. The strongest US open-weight models were our lowest performers — Gemma 4 31B (73.5) and Nemotron 3 Ultra (70.3).
The takeaway: model choice is now the easy part. What's left is engineering — model + harness fit, validation, inference routing.
That's the complexity we absorb so life-sciences teams can focus on the deliverable.
Full write-up 👇
everest.log10.io/news/open-w…
