

Président de https://xitter.cf/t.co/cBlYWR3VC5, passionné par l'innovation technologique.
- Tweets451
- Following88
- Followers87
- Likes127


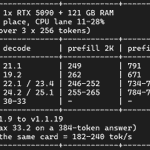



ALT Benchmark table ( RTX 5090 32 GB · 121 GB RAM · DeepSeek-V4.1-Flash-1017, IST-DAS 2.25bpw IQ2_XS pack · single user, warm cache, Oct 25 2026)

ALT Strata 0.2.4.2, IST-DAS 2.25 bpw · auto = streams from NVMe · --mmap-experts off = copies 11,666/12,983 experts into RAM (113 GB) · RTX 5090, 121 GB RAM, 24 Oct 2026.


ALT Benchmark table comparing two local inference engines on the same hardware, decode speed in tokens per second. DeepSeek-V4.1-Flash (748B MoE) on a single RTX 5090: Maya v1.1.26 at 31.6 tok/s measured, Strata 0.2.4 pending with the 274 GB model still downloading. Qwen MoE on the same RTX 5090: Strata at 185 to 225 tok/s. Qwen MoE on two 2016 Tesla P40 GPUs: Strata at about 40 tok/s. Measured 21–23 October 2026 on our own hardware.

ALT Table: Maya (DeepSeek maya-ds4) on one RTX 5090 with 121 GB RAM. Decode tokens/s: v1.1.9 on Oct 20 gives 21.1, fp16 19.2, the DSpark drafter 22.1 and 23.4, v1.1.19 on Oct 23 gives 24.2 and 25.1, and live use 30 to 33. Prefill at 2K prompt: 249 to 265; at 8K: 671 to 792. 147.6 GB of experts read in place, CPU lane 11 to 28 percent. Notes: decode up 15 to 19 percent from v1.1.9 to v1.1.19; Strata IQ3_S on the same card reaches 182 to 240 tokens per second.

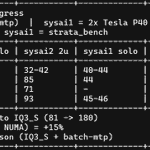
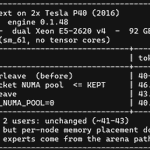
ALT Text table comparing Strata decode speeds on two servers, Oct 16-23 2026. 5090 server: solo 80-86 tok/s, then 180 after switching the model to IQ3_S, then 182 on engine 0.1.48; per user at two users: 32-42, 85, 93. Two Tesla P40 server: solo 40-44 on engines 0.1.44-0.1.45.3, 45-46 today on 0.1.48, where the NUMA pool adds about 15 percent.


ALT Strata dashboard showing Qwen3.8 Flash Next running at 49.8 t/s with 100% utilization across dual Tesla P40 GPUs