

Ph.D. student @umdcs @ClipUmd NLP, Retrievers, Human-AI, Efficient Methods Past: @ContextualAI @Cohere @GoogleAI @theteamatx 🚀 he/him 🏳️🌈
College Park, MD
Joined January 2011
- Tweets344
- Following615
- Followers430
- Likes953



Pinned Tweet
Can you spot when AI bluffs?🤖 Can you outguess AI—or work with one to dominate trivia?🏁
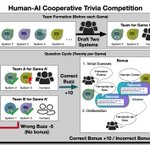
🏆 We are hosting the first Human–AI coop trivia (Quizzing) competition.
🎲Play, 🛠️build, or ✍🏼write questions...
..and win prizes 🎁.
🥳 It’s fun, free, and happening this June 🧠🤖👇

Maharshi Gor @ ACL2026 🏝️ retweeted

🚨 New Paper! 🚨
Multiple-choice benchmarks use accuracy (boring), but education has way cooler scoring schemes! 🤩
👎 Lose points if wrong
🔁 Try until you're right
🃏 Wager points
At #EMNLP2026, we show these schemes shift LLM ranks, align with LLM Arena, + unmask LLM quirks

Maharshi Gor @ ACL2026 🏝️ retweeted
🚨 New Paper! 🚨
Your agent is writing code faster than you can understand it 😬
In our controlled online study, coding agents helped users finish tasks quickly, but reduced how well they understood the code they just “wrote”
We also find three ways to avoid this tradeoff 👇🧵

Maharshi Gor @ ACL2026 🏝️ retweeted

Introducing Voice Arena STT Leaderboard.
LibriSpeech is older than the transformer.
FLEURS is people reading translated Wikipedia sentences aloud.
This is still how the industry ranks speech models. In 2026.
Today we're releasing the Voice Arena STT Leaderboard - a human-verified benchmark for STT accuracy on real, spontaneous conversation, across 7 languages: 🇺🇸 US English, 🇮🇳 Hindi, 🇧🇩 Bangla, 🇧🇷 Brazilian Portuguese, 🇻🇳 Vietnamese, 🇷🇴 Romanian & 🇸🇦 Arabic 🧵
US English Leaderboard ⬇️

📍 Presenting this on July 5 at 11:00 AM in Poster Session A at #acl2026nlp.
📜: arxiv.org/pdf/2605.28255
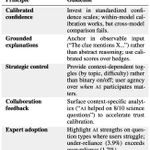
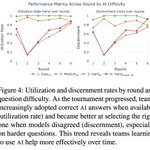
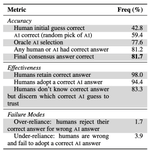
Come chat about when humans should let AI take the wheel, when they should push back, and what live human-AI collaboration reveals that static benchmarks miss.


Maharshi Gor @ ACL2026 🏝️ retweeted

We made a trivia game that has humans and computers cooperate: humans could let AIs buzz in for them to answer trivia questions (complete delegation) and then they worked with computers to answer other trivia questions collaboratively.
Come to #acl2026nlp Poster Session A!

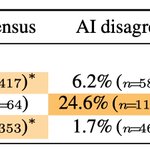
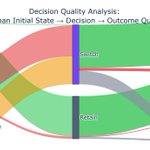
🧵 Trusting AI is not one decision.
In our ACL 2026 paper, expert trivia players had to decide when to let AI answer, when to ignore it, and when to change their minds because of it.
The main failure mode was not blind trust.


🙏 Huge thanks to everyone without whom this wouldn't be possible: my amazing co-authors: @YooYeonSung1, @houyu0930, @enfleisig, Irene Ying, @zhoutianyi, and @boydgraber; the UMD CLIP group; all participants and question writers/editors.
Maharshi Gor @ ACL2026 🏝️ retweeted

Earlier this month I successfully defended my PhD and graduated from UMD! 🐢 Thanks to everyone who played large or small role in making these last 5 years an amazing experience. Next stop, Toronto!
Defense recording: youtu.be/j8YIv25ge9Q

Maharshi Gor @ ACL2026 🏝️ retweeted
Our work on human-computer QA is the cover of UMD's Enterprise Magazine, featuring the work of @YooYeonSung1 , @enfleisig , @maharshigor, @h__j___han, @EntilZhaPR , @ihsgnef, @MohitIyyer (and many others).
Links below. We need people for next competition!

Maharshi Gor @ ACL2026 🏝️ retweeted

How2Everything will appear in ICML 2026! See you in Korea 🫡
We mine the web's procedural knowledge to better evaluate & train LLMs to generate valid step-by-step instructions, read more at:
🔗 arxiv.org/pdf/2602.08808


Maharshi Gor @ ACL2026 🏝️ retweeted
Can you spot when AI bluffs? Can you outguess AI or work with one to dominate trivia? Can you make an AI that can figure out tricky visual questions?

ALT Logo of a human and a computer looking at a Korean painting together, advertising the ICML 2026 workshop.
Maharshi Gor @ ACL2026 🏝️ retweeted
Super grateful to have four papers at #ACL2026 main! Thanks to all my co-authors from UMD, NYU, Ai2 + more 🎉🥹
Expect lots of "🚨 NEW PAPER" posts coming from me soon 😅
