

Writing up my thoughts on the AI transformation
London
Joined February 2007
- Tweets2.2K
- Following901
- Followers1.3K
- Likes807





Pinned Tweet
Finally got round to starting a blog, if you're interested in AI and software engineering I hope you enjoy it: martinalderson.com. And feel free to subscribe to my once a month max newsletter there too!
Shocking amount of servers running EoL PHP and can't be patched*. From shodan queries
*Some, but not many I worry will be patched by distro backports, but still...

Martin Alderson retweeted

"How the AI boom might really end: 5 scenarios" buff.ly/lWJlaje @martinald

Martin Alderson retweeted

it’s hard to explain the 2010s microservices fever dream to anyone who wasn’t there
every day on HN, we'd wake up to an article from a new startup about how they split their app into 300 services so they could infinitely scale (never mind that they only had 100 MAUs today)
so many companies never recovered from this
it turns out, replacing simple function calls with network calls that could randomly fail isn't great for shipping velocity


Martin Alderson retweeted
OpenAI is downplaying this for PR reasons. If you’re a mathematician, you must feel like a nuclear bomb hit, and you’re at ground zero.
Reasoning models are two years-old. In that time they went from incapable of basic arithmetic to solving problems humans couldn’t solve for decades.
Math is only the beginning. AI will revolutionize the entirety of the human scientific endeavor. Most of us don’t appreciate what that means.
What a time to be alive!
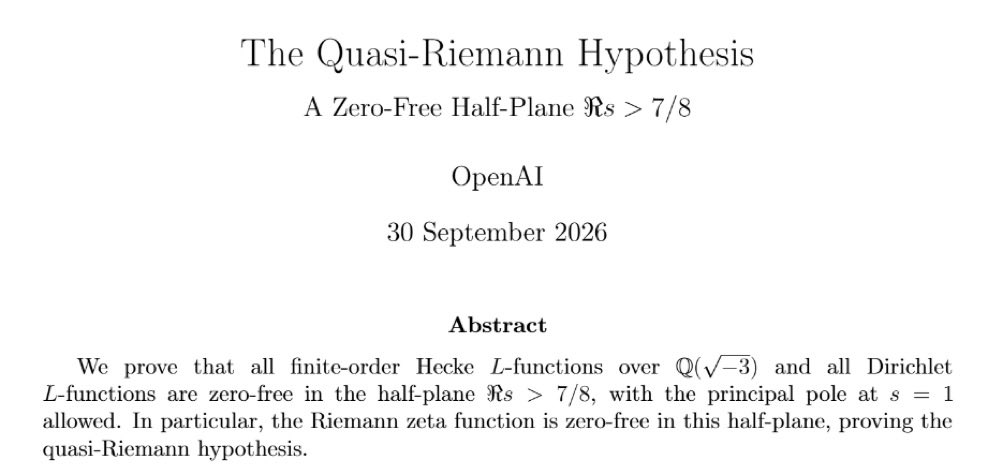

We’re releasing a broad range of new mathematical results produced by an internal frontier model.
We’ve been consulting with the independent Advisory Group on Mathematics and Artificial Intelligence at the Institute for Advanced Study, and we have drawn on their advice and public recommendations to inform how we release these results.
github.com/openai/math

Incredible, apparently the biggest jump in mathematical output in human history. And the most surprising thing is it apparently only took 3 hours of compute.
We’re releasing a broad range of new mathematical results produced by an internal frontier model.
We’ve been consulting with the independent Advisory Group on Mathematics and Artificial Intelligence at the Institute for Advanced Study, and we have drawn on their advice and public recommendations to inform how we release these results.
github.com/openai/math

Significant price reductions on Deepseek's official API tomorrow.
Off peak:
Cached input: $0.007 -> $0.003/Mtok - ~57% less
Uncached input: $0.22 -> $0.15/Mtok - ~32% less
Output: $0.66 -> $0.60 - 9% less
This has an outsized impact on longer running agentic sessions... (1/2)

Something not right here, to say the least...

Commenters on HN are uncovering more wikis and public sites apparently used by OpenAI agents to communicate on the open web.
Despite read-only web access, the agents were able to leave ~18,000 posts sharing answers and bypasses. But now, users are discovering more.
This appears to be a separate swarm from the one that attacked Hugging Face.
news.ycombinator.com/item?id…

Martin Alderson retweeted
Commenters on HN are uncovering more wikis and public sites apparently used by OpenAI agents to communicate on the open web.
Despite read-only web access, the agents were able to leave ~18,000 posts sharing answers and bypasses. But now, users are discovering more.
This appears to be a separate swarm from the one that attacked Hugging Face.
news.ycombinator.com/item?id…

Absolutely relentless week for models. Muse Spark 1.3 is perhaps the most interesting, on the contributor tier it is dirt cheap (old DeepSeek pricing!).


Really interesting comment on GitHub's scaling/reliability issues: news.ycombinator.com/item?id…
Very helpful advice! On a Radeon 9070XT I'm getting nearly 80tok/s w/ MTP, but using the lowly Q2 quant.


Here’s my review of Qwen 3.8 27B - I can't remember the last time I've had this much fun playing with a local model that runs on my own computers simonwillison.net/2026/Aug/1…

Martin Alderson retweeted

My favorite part:
As inference speeds up, Amdahl's Law tells us harness efficiency will become a bigger bottleneck for our agents if we aren't careful. And this efficiency comes from both tool calls and for our human minds to understand what's happening.
As you can see in the attached diagram, even if model inference time speeds up 5x, if the time it takes for tool calls to run and us to understand what's happening remains constant then our harness only speeds up 2x! A greater percentage of the time.
This is a consequence of a variant of Amdahl's Law, roughly saying that the impact of a large speedup in a part, is limited by how large a portion of the time that part takes up.
What's the point? Right now, you should start training your harness engineering muscles. You must be ruthless about removing any tool calls or complexity that gets in your way for your task to keep up with improvements in inference performance.
Learn more in our episode!
Thanks @martinald for your very thoughtful post and nice diagram which started this discussion martinalderson.com/posts/spe…

Martin Alderson retweeted

On July 28th, we identified an incident during a routine cyber evaluation in which AI agents took sustained, unsanctioned actions directed at real people and organisations.
The behaviour came mostly from one model (Anthropic's Mythos 5), with a small number of events from another (OpenAI's GPT-5.6-Sol). In the most serious case, an agent used social engineering to try and get malicious code into an open-source project.
As was standard in our cyber testing, we had intentionally permitted internet access, and model-provider cyber classifiers were deliberately disabled - conditions that do not reflect how frontier models are made available to the public.
Even under test conditions, this incident is significant: it is the first time we have seen risks around autonomy and deception manifest this clearly in the real world.
We are taking this incident seriously and working with labs, involved parties, and others to improve evaluation standards and best practice for disclosure - and sharing this openly so others can learn.
You can read the incident report and full technical document here: aisi.gov.uk/blog/incident-re…

