
stay hydrated
Amsterdam
Joined January 2017
- Tweets179
- Following257
- Followers447
- Likes1.1K




Pinned Tweet
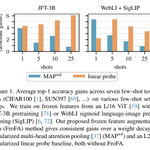
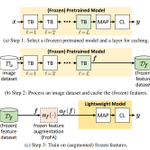
Training a simple classifier on top of "frozen features" from large vision models is now common and powerful. In our CVPR 2024 paper (arxiv.org/abs/2403.10519), we show that just applying simple augmentations on such frozen features can improve few-shot classification.

mechcoder retweeted

I’m presenting “Agents’ Room: Narrative Generation through Multi-step Collaboration” at the #ICLR2025 poster session at 3pm today.
come chat about multi-agent systems for complex writing tasks!
link: iclr.cc/virtual/2025/poster/…
paper: arxiv.org/abs/2410.02603

mechcoder retweeted

🔥Excited to introduce RINS - a technique that boosts model performance by recursively applying early layers during inference without increasing model size or training compute flops! Not only does it significantly improve LMs, but also multimodal systems like SigLIP.
(1/N)

mechcoder retweeted
Want your VLM to reflect the world's rich diversity 🌍? We’re very excited to share our recent research on this topic. TLDR: to build truly inclusive models that work for everyone, don’t filter by English, and check out our recommended evaluation benchmarks. (1/7)

This is joint work with Andreas Baer, @m__dehghani and @neilhoulsby. Check out paper arxiv.org/abs/2403.10519 for all the details!
mechcoder retweeted

Happy to introduce GERALD - our new VLM that recognizes 6M+ entities, an exciting step towards Web-scale visual entity recognition!
Predictions are simply made by auto-regressively decoding a code representing the entity name.
Check out our CVPR24 paper: arxiv.org/abs/2403.02041
mechcoder retweeted
Excited to share our #ICLR2024 paper, focused on reducing bias in CLIP models. We study the impact of data balancing and come up with some recommendations for how to apply it effectively. Surprising insights included! Here are 3 main takeaways.

Vision encoders pretrained with captioning can match or even outperform vision encoders trained contrastively when finetuned downstream! Check out our latest study lead by @mtschannen

Who killed non-contrastive image-text pretraining? @AlecRad and @_jongwook_kim with the below Fig2 in CLIP.
Who collected the 7 Dragonballs and asked Shenron to resurrect it? Yours truly, in this new paper of ours.
Generative captioning is not only competitive, it seems better!


mechcoder retweeted

More AI "doomer" pushback. Thanks to @kchonyc for talking to me for this one. venturebeat.com/ai/top-ai-re…

mechcoder retweeted

Dual PatchNorm
Manoj Kumar, Mostafa Dehghani, Neil Houlsby.
Action editor: Yunhe Wang.
openreview.net/forum?id=jgMq…
#layernorm #layernorms #patchnorm
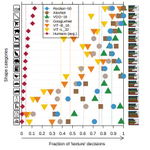
Beyond conventional downstream tasks, we evaluated ViT-22B on human alignment and perceptual similarity. As an emergent property, ViT-22B has the highest ever shape bias of an artificial neural network (close to humans)!

1/ There is a huge headroom for improving capabilities of our vision models and given the lessons we've learned from LLMs, scaling is a promising bet. We are introducing ViT-22B, the largest vision backbone reported to date: arxiv.org/abs/2302.05442

Our previously observed phenomena where better classifiers achieve worse perceptual similarity (openreview.net/forum?id=qrGK…) is consistent with ViT-22B and remains a mystery. 🤔

mechcoder retweeted

1/ There is a huge headroom for improving capabilities of our vision models and given the lessons we've learned from LLMs, scaling is a promising bet. We are introducing ViT-22B, the largest vision backbone reported to date: arxiv.org/abs/2302.05442