

한국어, English, 日本語. Omarchy, CC Max, OA Pro, Grok Heavy, M3U 512GB, GX10 TP=4. Aspiring value investor. @fortyfourbits. A software engineer at Karrot.
Republic of Korea
Joined October 2017
- Tweets31.6K
- Following628
- Followers5K
- Likes29K


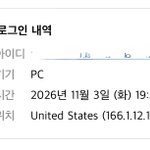



쿨럭, 나도 모르는 사이에 사용량 부족해서 클로드 로그인 상태를 체크하겠다고 무한 반복 스크립트를 만들어서 돌리고있는데, 스크립트 폭주중이라고 보고 받음. 나 차단 당하면 어떻게 하라고 ㅜ...
Daegwon Nacyot Kim retweeted

Introducing GPT‑6 Cyber: a major advance in security research that pairs stronger capabilities with better model alignment.
The model powered the Linux kernel research we announced yesterday, and security teams at companies like Mozilla, Palo Alto Networks, Calif, and Cisco—alongside our own at OpenAI—are already putting it to work.
GPT-6 Cyber is available to select Daybreak Red customers and we are expanding access over time.
openai.com/index/introducing…


Daegwon Nacyot Kim retweeted

그래서 치킨게임, Cost Decreasing 산업의 구조를 설명해주고,
AI 수요도 중요하지만,
메모리 산업은 치킨게임을 언제 시작하느냐...가 더 중요하다...라고 설명해줬더니,
이해는 못 하겠고, 술맛만 버렸다는 표정이더라.
평범한 이웃들이 확신에 찬 표정일때가
난 항상 두렵더라 -.-;
Daegwon Nacyot Kim retweeted

근데.. 이 계약에 도장찍게 한건 대퓨님이란 것..

NYT, 뉴진스 멤버들이 체결한 계약서를 입수해서 표준계약서와 비교해 상당히 열악한 조건이었음을 고발하는 기사 보도. (어쩌다 뭔가 판이 커졌다?) nytimes.com/interactive/2026…

Daegwon Nacyot Kim retweeted

‼️ Ruby on Rails apps using ImageMagick can be made to write attacker-chosen files by one crafted image upload, no login needed.
Rated 9.8/10, it can also leak secrets like secret_key_base if uploads sit on disk.


우리 DS4.1F가 병렬 브라우징 힘겹게 해내고 있는데, 그럴 필요가 있나, Grok Bot, Dot, 피클 처럼 VM만들어서, 한 작업에 하나씩(!) 할당해서 작업하면 되는 거 아닌가 싶어서... 바로 구현중. 실제 구현은 브라우징 전용 환경만 공유풀로 만들면 될 듯.
Daegwon Nacyot Kim retweeted

oMLX 0.7.4.dev1 is out!
github.com/jundot/omlx/relea…
With the new Prefill Accelerator, connect an M5 Max to your big Mac and prefill up to 2.9x faster!
Prefill Accelerator (64K prompt, M3 Ultra 512GB + M5 Max 128GB)
- DeepSeek V4.1 Flash: 1,060 -> 3,123 tok/s (+195%)
- Qwen3.8 Flash-Next: 1,309 -> 3,666 tok/s (+180%)
- GLM-5.3 Flash: 540 -> 1,388 tok/s (+157%)
- MiniMax M3.1: 297 -> 569 tok/s (+92%)
- An M5 Max 64GB still adds 30-118%, and decode speed stays the same.
Faster DeepSeek V4.1 with A8 and buffer pool improvements
- Prefill on M5 Ultra is 43-48% faster, 32K goes 2,631 -> 3,779 tok/s (+44%).
- oQ4e builds now run INT8 Activation Prefill on M5.
Faster Qwen3.8 Flash-Next
- FP16 builds get the fused kernels. Decode on M3 Ultra goes 38.9 -> 63.0 tok/s (+62%), and +23% on M2 Max.
- Decode after long prompts is 3-5% faster on M5 Max.
Better for agents
- Parallel tool results from Claude Code reach the model in call order, so Qwen no longer pairs a result with the wrong call.
- Agent sessions on a cluster reuse the prompt cache across tool turns, 743 -> 9,266 cached tokens by the fifth turn.
- Switch oMLX models inside Codex and Copilot with /model.
Also in 0.7.4.dev1
- Ming-3.0 TTS with a 2x faster decode loop.
- Ask AI can use an oMLX server on another Mac.
- Check for model updates in the macOS app.
- German across the web dashboard and the macOS app.
- Batched decode with 6 requests on 8-bit models is 16% faster.
A big thank you to everyone who sent PRs, reported bugs and tested builds for this release, and a warm welcome to the five new contributors!

Daegwon Nacyot Kim retweeted

This is a dream I had since I bought M5 Mac 128GB!
Prefill Accelerator (64K prompt, M3 Ultra 512GB + M5 Max 128GB)
- DeepSeek V4.1 Flash: 1,060 -> 3,123 tok/s (+195%)
- Qwen3.8 Flash-Next: 1,309 -> 3,666 tok/s (+180%)
- GLM-5.3 Flash: 540 -> 1,388 tok/s (+157%)
- MiniMax M3.1: 297 -> 569 tok/s (+92%)

oMLX 0.7.4.dev1 is out!
github.com/jundot/omlx/relea…
With the new Prefill Accelerator, connect an M5 Max to your big Mac and prefill up to 2.9x faster!
Prefill Accelerator (64K prompt, M3 Ultra 512GB + M5 Max 128GB)
- DeepSeek V4.1 Flash: 1,060 -> 3,123 tok/s (+195%)
- Qwen3.8 Flash-Next: 1,309 -> 3,666 tok/s (+180%)
- GLM-5.3 Flash: 540 -> 1,388 tok/s (+157%)
- MiniMax M3.1: 297 -> 569 tok/s (+92%)
- An M5 Max 64GB still adds 30-118%, and decode speed stays the same.
Faster DeepSeek V4.1 with A8 and buffer pool improvements
- Prefill on M5 Ultra is 43-48% faster, 32K goes 2,631 -> 3,779 tok/s (+44%).
- oQ4e builds now run INT8 Activation Prefill on M5.
Faster Qwen3.8 Flash-Next
- FP16 builds get the fused kernels. Decode on M3 Ultra goes 38.9 -> 63.0 tok/s (+62%), and +23% on M2 Max.
- Decode after long prompts is 3-5% faster on M5 Max.
Better for agents
- Parallel tool results from Claude Code reach the model in call order, so Qwen no longer pairs a result with the wrong call.
- Agent sessions on a cluster reuse the prompt cache across tool turns, 743 -> 9,266 cached tokens by the fifth turn.
- Switch oMLX models inside Codex and Copilot with /model.
Also in 0.7.4.dev1
- Ming-3.0 TTS with a 2x faster decode loop.
- Ask AI can use an oMLX server on another Mac.
- Check for model updates in the macOS app.
- German across the web dashboard and the macOS app.
- Batched decode with 6 requests on 8-bit models is 16% faster.
A big thank you to everyone who sent PRs, reported bugs and tested builds for this release, and a warm welcome to the five new contributors!
Daegwon Nacyot Kim retweeted

저와 일하고 싶은 분 계신가요? 저희 회사 겨울 인턴 뽑고 있습니다. 😉
search-careers.gm.com/en/job…

Daegwon Nacyot Kim retweeted

오늘 내가 본 최악의 코드가 갱신됬다.
1위 new ) 장소 추천하는 앱인데 코드에 장소를 하드코딩해둠
이게 400주고 외주 준 앱이라는데
아니 어쩐지 장소 데이터 추가하려면 코드를 엎어야 한다 -> 라고 했다
이말에서 꼬리한데했어!!
왜!! 모든사람들은!! 나를먼저안부르고! 일을저지를까!!
Daegwon Nacyot Kim retweeted

【11月4日 朝のニュースまとめ】
・GPT-6.2 Astra、Opus 5.5並みへ60%値下げとの情報
・Anthropic、応答元モデルを検証できるFlashProveを発表
・Claude、ログインだけでMCPプラグインに自動接続
・本番障害の原因を探るTraversal、$120M調達
・Revolut、約2000人のエンジニアを自前GLMに移行
・OpenAI、機械・電気設計やシミュレーションでの活用成果を公開
・Gemma 4 Agentコンペに小型モデル特別賞$10K追加
・自作大喜利AI対決、SFT+DPOや多モデル選抜で競う
・Mistral Large 4、学習途中でAttention構成を変更
・Agentハーネス最適化、コスト選好は探索の最後に適用を
・Google DeepMind、RLで精神科インテーク面接を改善
・Deep Agentsのブラウザ操作はStagehand基盤、設計を解説
・NVIDIAの音声修復RE-USEでノイズ除去と文字起こしを比較
===
GPT-6.2 Astra、Opus 5.5並みへ60%値下げとの情報【続報】
・Codexの利用内訳に出現したOpenAIのGPT-6.2 Astraに関する続報です
・一部ユーザーでAstraへのリクエストがGPT-6.2にルーティングされている様子が共有され、投入間近との観測が広がっています
・価格をOpus 5.5並みに60%引き下げるとの情報も出ており、ブラインドテストではアプリ構築でOpus 5.5より好まれたとされます
・性能と価格の両面で競争力が高まるとして、Agent用途でのシェア拡大を見込む声が出ています
===
Anthropic、応答元モデルを検証できるFlashProveを発表
・AnthropicがLLMのprovable inferenceに関する研究成果としてFlashProveを発表しました
・既存の暗号技術を基盤に、ある応答が特定のAIモデルから出力されたかを開発者が検証できる仕組みです
・浮動小数点対応の検証技術を持つ企業からも反応があり、provable inferenceの必要性を訴える声が出ています
===
Claude、ログインだけでMCPプラグインに自動接続【続報】
・ClaudeのMCPコネクタ向けエンタープライズ管理認証に関する続報です
・Claudeにログインするだけで、対応するMCPプラグインへ自動接続できるようになりました
・Claudeを信頼できる発行者として受け入れるMCPサーバーが対象で、管理者が設定すればメンバーは初回利用時に自動接続されます
・再認可の手間は大きな不満点だったため、Agent利用の効率化として歓迎する声が多く上がっています
===
本番障害の原因を探るTraversal、$120M調達
・本番システムの障害解析を行うTraversalが、評価額$1Bで$120Mを調達しました
・サービスと依存関係をマッピングし、障害時に複数の原因候補を並列に検証、学んだ知見をコーディングAgentに戻す仕組みです
・コード生成は速くなったが本番の理解は追いつかないとして、ボトルネックが運用に移ったとの共感が集まっています
===
Revolut、約2000人のエンジニアを自前GLMに移行
・RevolutがコーディングAIを自社ホストのGLMに切り替え、Claude CodeとCodexを例外扱いにしたと報じられました
・B200を56基使い、100万トークンあたり約30セントと、従来の約1/10のコストでリードタイムは70%短縮したとされます
・知能スタックを自社で持つことが競争力の鍵だとして、オープンモデルの本番採用例として注目されています
===
OpenAI、機械・電気設計やシミュレーションでの活用成果を公開
・OpenAIがChatGPTとCodexを物理世界のエンジニアリングに活用した進捗を公開しました
・機械設計、電気工学、シミュレーションの領域で、自社ハードウェアチームの反復高速化や業界パートナーとの検証を紹介しています
・ブログ内のグラフから、未公開の内部モデルが公開モデルを大きく上回っていると読み取る声も出ています
===
Gemma 4 Agentコンペに小型モデル特別賞$10K追加【続報】
・KaggleのGemma 4 Developer Agent Competitionに関する続報です
・Gemma E2BまたはE4Bを使う小型モデルの開発Agent向けに、ボーナス賞$10,000が追加されました
・該当する提出のうちPrivate順位が最上位のものが対象で、LoRAファインチューニングも本戦同様に使えます
・賞金総額は$100,000、エントリー締切は11月25日で、時間があれば挑戦したいとの声も出ています
===
自作大喜利AI対決、SFT+DPOや多モデル選抜で競う
・Kagglerらがそれぞれ自作した大喜利AIで対決する企画動画が公開されました
・複数AIの回答から選抜、Dotに選ばせるなど作り方は三者三様で、Qwen3.5-9BをSFT+DPOした例もあります
・追加学習モデルは惨敗も回答速度は圧倒的1位で、字幕付けなどの編集にもCodexを活用したそうです
===
Mistral Large 4、学習途中でAttention構成を変更【続報】
・Mistral AIの1TパラメータMoEモデルMistral Large 4に関する続報です
・設計の要点をまとめた投稿が共有され、MLAとクエリあたり2,048キーを選ぶsparse attentionで1M文脈に対応しています
・事前学習の途中でSWAとCLAのハイブリッドを試したところ、perplexityは同等でもSWE-benchが悪化しました
・そのためフルAttentionに戻しつつYOCOは維持したとされ、perplexityだけで設計を判断する危うさを示す事例です
===
Agentハーネス最適化、コスト選好は探索の最後に適用を
・品質とコストの両面でAgentハーネスを最適化する際の知見を示した研究が紹介されました
・探索の各ステップでコスト選好を適用すると、より良いハーネスにつながる候補を捨ててしまうとしています
・コスト選好は探索の最後にのみ適用すべきという点が要点で、ハーネス改善に取り組む開発者に示唆のある結果です
===
Google DeepMind、RLで精神科インテーク面接を改善
・Google DeepMindが、シミュレーション患者とのマルチターンRLでGeminiに精神科のインテーク面接を学習させました
・32人の精神科医が患者役を演じた二重盲検試験で、同一プロンプトのベースモデルに対し60件中76.7%で勝利しています
・評価は別の精神科医パネルが盲検で行っており、シミュレーション内RLが臨床対話に効く例として注目されています
===
Deep Agentsのブラウザ操作はStagehand基盤、設計を解説【続報】
・LangChainのManaged Deep Agents 0.10で追加されたブラウザ操作機能に関する続報です
・LangChainが、ブラウザ操作ツールをどう選び、どう調整したかを解説する記事を公開しました
・BrowserbaseのStagehand上に構築し、ブラウザ操作がコンテキストウィンドウに与える負荷への対処を扱っています
・Harrison Chaseは今春にモデルがブラウザを操れる水準に達したとし、ブラウザは新たなターミナルだと述べています
===
NVIDIAの音声修復RE-USEでノイズ除去と文字起こしを比較
・NVIDIAの音声修復モデルRE-USEをポッドキャスト音声に適用した検証記事がZennで公開されました
・ノイズ除去の効果と、その後の文字起こし結果への影響を比較する内容です
・音声修復を文字起こしの前処理に使えるかを判断する実践的な参考になりそうです