

Share Tips AI, SWE and Work Culture | Business Inq on [email protected] | @SpaceXAI Ambassador | @open_ai Codex Ambassador | Build https://xitter.cf/t.co/J62lghozl7
Jakarta Selatan, DKI Jakarta
Joined December 2011
- Tweets91K
- Following3.9K
- Followers19.2K
- Likes11K




Pinned Tweet
DevDay Exchange Community: Jakarta, 15 November 2026.
Klo kamu pakai ChatGPT atau Codex, ini buat kamu. Ga harus developer.
Kenapa? Karena AI skrng udh bukan cuma urusan engineer. Yg kerja di edukasi, konten, sampai bisnis juga udh pakai tiap hari.
Jadi isinya dibikin untuk semua orang:
- Nonton DevDay bareng
- Panel "AI for Everyone" dari sisi public figure, education, dan technology
- Tech talks
- Networking
Panelnya bakal ngobrolin dampak AI, gimana workflow kerja berubah, dan gimana AI bisa diakses semua orang. Panelisnya aku share nanti.
Save the date:
- Minggu, 15 Nov, 10.00 WIB
- Lokasi Ganara, fX Sudirman
Benefit:
- Credit Codex dan OpenAI API
- Networking
- Insight dari panel dan tech talks

ALT DevDay Exchange Community: Jakarta event cover
Wow, model baruu.. GPT-6.1 Terra udah rilis! Sangat worth it kalau kamu pakai ChatGPT Plus. Usage hampir 2x dari Sol, task selesai 3x lebih cepat dari Sol, dan intelligence Terra max setara Sol medium.
TLDR
- Speed: 91 tps, Sol 69 tps
- Intelligence: 48, Sol 52, Astra 53
- Usage Plus: 35-285 message per 5 jam, Sol 15-160
- Harga API: $1/$5 per 1M token, setengah dari Sol
- Context 1M token
Terra bagus dimana?
- Computer use: skor setara Astra di Agents' Last Exam, harganya 1/10
- Visual: baca screenshot, gambar teknis, chart, hampir nyamain Sol dan Astra
- Coding: Terminal-Bench 50.3%, 2x lebih tinggi dari GPT-5.6 Terra
- Hallucination turun jauh: error rate di max 4.3%, hampir sama kayak Sol
Kenapa pakai Terra? Buat kerjaan harian kayak nulis, isi form, olah dokumen, computer use, coding rutin. Quota Plus kamu jauh lebih awet. Buat coding yg berat dan reasoning yg dalam, tetap Sol.
Imho buatku, intelligence-nya ga beda jauh lah ya sama Sol, aku bakal coba 1-2 hari. Cuman klo dari aku bisa gini
Sol xhigh (51) > Sol high (50) > Terra max = Sol medium (48) > Terra xhigh (45) > Terra high (44)
Apalagi klo pilihannya speed, Sol itu 69 tps, Terra 91 tps

OpenAI has released GPT-6.1 Terra, pushing the cost efficiency frontier. It is the first Terra-class model since GPT-5.6, and is more intelligent for less than a third of the cost
Pricing per token is half or less that of GPT-5.6 Terra - at $1/$5 per million input/output tokens vs $2/$12 for the previous model. Cache write has also halved, now at $1.25 per million tokens. Cached input is one quarter at $0.05 vs $0.20 per million tokens.
Key takeaways:
➤ Pareto-optimal for Intelligence vs Cost at low and medium effort: At max effort, GPT-6.1 Terra gains 6 points in the Artificial Analysis Intelligence Index over GPT-5.6 Terra, at less than a third of the cost per task ($0.40 vs $1.40). At lower effort levels the gain is larger, between 7 and 13 points. The low and medium effort levels are Pareto-optimal for cost efficiency, while the other effort levels sit behind the frontier. At max effort, the model scores 4 points below GPT-6.1 Sol and 10 points above GPT-6 Luna in the Intelligence Index.
➤ Pushes the Coding Agent Index cost efficiency frontier: With a score of 48 in the newly released Artificial Analysis Coding Agent Index v2.0, the model is 6 points below GPT-6.1 Sol (54) and 17 points above GPT-6 Luna (31). The xhigh and low effort settings sit on the frontier of cost efficiency in the Coding Agent Index, while other effort levels are behind the frontier.
➤ 50 point drop in hallucination rate: GPT-6.1 Terra guesses 38% of the time when it does not know the answer to a question in AA-Omniscience, our private knowledge and hallucination benchmark. Previously, GPT-5.6 Terra's hallucination rate was 88%. This significant reduction in hallucination is coupled with a 2 point increase in AA-Omniscience accuracy - meaning the model simultaneously answers more questions correctly.
➤ 20 point jump in Terminal-Bench 4.0, small improvements across most evaluations: The model makes significant progress in the terminal-based agentic benchmark, Terminal-Bench 4.0, with a gain of ~20 points, now rivaling GPT-6.1 Sol at max effort. Gains across most other evaluations are smaller, for example, 5 points in GDP.pdf.
Congratulations @OpenAI and @sama on the launch!


Gajian pertama cuma 5 hari kerja, apa PPh 21-nya dihitung dari gaji full? Enggak. Sejak 2024, PPh 21 bulanan pakai TER (tarif efektif rata-rata), dan dasarnya penghasilan bruto yg beneran kamu terima bulan itu.
Kenapa? Karena rumusnya simpel. PPh 21 = tarif TER x bruto bulan ini. Di bulan biasa, ga ada istilah gaji kamu "disetahunkan" dulu.
Contohnya gini. Gaji kamu Rp6 juta, status TK/0 (kategori A). Masuk tengah bulan, cuma kebayar 5 dari 22 hari kerja.
- Gaji prorata kira2 Rp6 jt / 22 x 5 = Rp1,36 jt
- Kategori A, bruto sampai Rp5,4 jt tarifnya 0%
- Jadi PPh 21 bulan ini Rp0
Yg perlu kamu cek di slip gaji:
- Status PTKP kamu udah bener. Kategori A itu TK/0, TK/1 dan K/0. Kategori B dan C batas 0%-nya lebih tinggi
- Bruto itu termasuk tunjangan tetap dan premi BPJS tertentu yg dibayar kantor (JKK, JKM, Kesehatan), jadi angka yg dikali TER bisa sedikit di atas gaji pokok
- Cara prorata tiap kantor beda, ada yg pakai hari kerja, ada yg pakai hari kalender. Tanya HR biar ga kaget
Satu lagi. Di masa pajak terakhir (Desember, atau bulan terakhir kamu kerja), PPh 21 dihitung ulang setahun pakai tarif Pasal 17. Jadi bisa ada selisih kurang atau lebih potong di situ.
Jadi santai aja, gaji 5 hari ga bakal dipajakin kayak gaji sebulan penuh.


Ini referensinya klo mau baca lebih lengkap.
jdih.kemenkeu.go.id/api/down…
After Origin, now there's Entire. Two new Git forges built for AI agents in just 2 months.
And this month GitHub and GitLab both went down more than once. Maybe this is the sign: don't put all your code on 1 provider. Have a backup.
TLDR Entire:
- Built by Thomas Dohmke, ex-GitHub CEO
- Trails: every push gets scored 0-100 by review agents, then gates decide when it can merge, with human review optional
- Claims pushes up to 89x faster than GitHub
- Continuous Memory: agent sessions saved inside the repo
- Can mirror from GitHub, works with Claude Code, Codex, Cursor and more
Pros:
- Mirror from GitHub, so it can be your backup without moving everything
- Built for agents, not humans clicking buttons
- Free trial, $100 credit or 90 days, no card
Cons:
- The 89x number is from their own benchmark, no independent test yet
- Agent scores are LLM judgments, not tests. Who maintains the evals?
- Agent transcripts pushed by default, readable by anyone with repo access
- Only branches and tags move. Issues and PRs stay behind
- Still early, CLI is 0.x
So backup provider, yes. Just remember a mirror backs up your code, not your whole workflow.

ALT Illustration of a developer at a laptop beside two server nodes, one dimmed and one glowing as a backup
Source: entire.com/blog/the-git-forg…

agenda bareng istri @fifiyuu sebelum bobo, dengerin kuliah umum Pak Eko di-rujakan @raymondchins

Kontrak PKWT habis dan ga mau lanjut? Hubungan kerjanya berakhir sendiri sesuai tanggal di kontrak. Ini diatur di UU 13/2003 Pasal 61 ayat (1) huruf b, yg masih berlaku setelah diubah UU 6/2023 (Cipta Kerja). Jadi kamu ga perlu bikin surat resign.
Tp tetep kabarin atasan dan HR, tertulis. Kenapa? Biar handover jelas, paklaring lancar, dan nama kamu tetep baik. Dunia kerja itu kecil.
Yg sering kelewat, ada uang kompensasi PKWT. Berlaku klo masa kerja minimal 1 bulan, besarnya masa kerja/12 x 1 bulan upah (pokok + tunjangan tetap). Khusus usaha mikro dan kecil, besarnya ikut kesepakatan.
Cek ke HR sebelum hari terakhir:
- Kapan uang kompensasi dibayar
- Kapan paklaring keluar
- Status BPJS Ketenagakerjaan biar JHT gampang diurus
Pamit aja baik2, biar hak kita dapat. Kedua hal ini perlu jalan bareng.
Satu lagi, selama masih kerja, slalu over communication.
Sumbernya klo mau baca lengkap:
jdih.kemnaker.go.id/berita/d…

Gimana kalau editor video kamu itu agentic?
Aku masuk early access Agentic Video Editor dari @ImagineArt_X. Kamu tinggal bilang editnya mau gimana, agent-nya yg ngerjain di timeline.
Bayangin aja gini. Kamu content creator, punya produk buat jualan, suka bikin footage.
Skrng dgn adanya ini, fokusnya cari banyak2nya assets. Video produk, foto produk, footage mentah.
Part editing bakal kita kasih ke Agentic Video Editor. Mulai dari edit timeline, trim, cut, cut sesuai beat, buang bagian yg silent, B-roll yg nyambung sama shot, caption, sampai mixing audio.
Penasaran nanti bakal kayak gimana. Kita lihat sejauh apa.

Kalau udah punya brand baju, sekarang bisa bikin lookbook full cuma dari 1 foto produk.
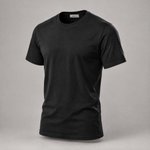
Aku coba pakai ImagineArt. Dari 1 foto kaos hitam (brand fiktif KAIN&CO), hasilnya:
- Foto produk studio yang clean, siap buat katalog
- Kalau dipakai orang, fit-nya kelihatan kayak gimana
- Dipaduin sama OOTD casual, jeans + sneakers
- Dipaduin sama OOTD smart casual, overshirt + chino + loafers
Semua di-generate pakai ImagineArt dari 1 foto produk. Biar makin mirip, kasih 2-3 foto produk sebagai referensi.
Kenapa ini berguna? Brand baju kecil dan affiliate seller jarang punya budget buat model, fotografer, dan lokasi. Jadi pembeli bisa kebayang hasilnya pas dipakai, bukan cuma lihat baju digantung.
Catatan: pastiin produknya beneran ada, dan pakai lebih dari 1 foto biar detailnya akurat.


Tools yang aku pakai: ImagineArt, model GPT Image 2.5
@ImagineArt_X @ImagineArt_Creo
Males berangkat kerja itu normal. Yg perlu dicek, malesnya karena apa.
Kenapa? Karena solusinya beda2.
- Capek fisik atau kurang tidur? Benerin dlu jam tidur sama makannya, ini ga perlu resign
- Capek batin, overthinking terus? Coba ngobrol sama psikolog, dan dekatkan diri ke Tuhan
- Kerjaan repetitif, udh ga ada yg dipelajari? Ini sinyal growth-nya mentok
- Atasan atau tim bikin takut salah tiap hari? Ini masalah ekosistem
Jadi klo soal growth, coba minta tanggung jawab baru atau pindah tim dlu sebelum mikir resign.
Klo soal ekosistem, coba ngobrol langsung sama atasan. Klo udh dicoba dan tetep sama, baru itu alasan resign yg valid.
Klo soal gaji, cek dlu pasarannya, baru nego dgn data.
Tanya ke diri sendiri, di sini aku masih berkembang ga? Masih aman buat nyoba dan salah ga?
Klo jawabannya ga, ya siapin exit plan. Dana darurat beberapa bulan, CV di-update, apply sambil masih kerja.
Males itu wajar, asal tetep semangat hidup. Ambil keputusannya sbg orang dewasa, karena apa2 yg terjadi nanti, kita sendiri yg tanggung jawab.


r/opensource baru aja ban semua project yg nyentuh AI. Padahal Linus Torvalds sendiri pakai Claude Code buat bikin patch kernel.
Menurutku ini kebablasan. Kenapa? Linus bilang dia suka pakai AI, dan patch series-nya ditulis jelas di cover letter kalau dibantu AI.
Tapi kernel juga ga asal terima. Rule-nya:
- AI agent ga boleh nambah Signed-off-by. Cuma manusia yg bisa certify DCO
- Manusia yg review code-nya, dan tanggung jawab ada di dirinya
- Linus juga mau discourage drive-by AI patch, karena bikin maintainer stress
Dan ini bukan cuma kernel. Riset ke 281 AI policy di project open source populer (Hora, Robbes & Zacchiroli, Sep 2026) nemu 83.3% allow AI di code. Yg ban cuma 14.9%.
Slop problem itu real, aku setuju. Maintainer banyak yg kebanjiran PR dan report karena hasil AI kaga di-review, jadinya banyak slop dan problem. Solusinya ya review dan accountability, kayak yg kernel lakuin.
Aku sendiri kerja kayak gini tiap hari. AI bantu ngerjain, aku yg review sebelum release atau merge. Tanggung jawabnya tetap di aku. Klo down atau ada bug, masa bilang "gegara AI nih"? Kan ga make sense.
Gimana pendapat temen2 soal rule forum open source ini? Ini namanya gatekeep ga sih?

A 10-year-old image model just beat GPT-6 Astra and Claude Fable 5.1 at reading skin lesions.
A dermatologist, Dr Magnus Lynch, gave all three the same 200 biopsy-proven lesions. Each lesion had a clinical photo and a dermoscopic image, and each model picked one of six diagnoses.
Here is how it went.
- Fine-tuned Inception v3 (a Google CNN from 2015) got 125 right, 62%
- GPT-6 Astra got 84, Claude Fable 5.1 got 85, both 42%
- On one invasive melanoma, both LLMs called it a harmless growth and said the patient could be discharged. The CNN called it melanoma.
The CNN was fine-tuned for about 20 minutes on 68,011 public dermatology images. Small, old, specialised.
But read the limits before you share this as "LLMs are useless".
- 200 lesions and only 30 melanomas, so the uncertainty is wide
- Each LLM case ran once, one prompt, default settings
- It's a blog post, not a peer-reviewed paper
- At its preset threshold the CNN sent home 18 of 30 melanomas. The LLMs sent home 3 and 4.
So none of the three is safe to make that call alone.
For me the lesson is about tool choice. A general model that writes like a doctor is not the same as a model trained for one narrow job. Pick the tool for the task, then measure it on your own cases.
Here's the source if you want to read more.
lynchlab.net/llm-skin-cancer