

https://teapawt.org/t.co/xaLUuOzmda is an on-demand GPU cloud delivering NVIDIA’s latest silicon - B200, A100 & RTX 6000 Pro - at 50%+ below market.
San Jose, CA
Joined April 2026
- Tweets200
- Following5
- Followers298
- Likes104





Token Factory is LIVE - and it's FREE!
dash.packet.ai/serverless
While most teams are busy talking about AI tokens, ours has been busy turning them into memes. 😂
The team has already started flooding our internal channels with some serious meme material.
So, let's take this to LinkedIn!
Which one deserves the crown? 🏆
Comment 1, 2 or 3 with your favourite.
And here's the fun part: the most entertaining comment wins a surprise gift from us!
Go on, show us your meme-ranking skills!
#AI #TokenFactory #PacketAI #AICommunity #Memes
#AIInference #GPUCloud #FreeAIAccess #Tokenfactory


1
33
RTX 5090 available on Packet•ai
And we're giving you more GPU hours to put it to work.
Use Voucher - GET50MORE 👇
Top up your wallet with $50 or more and we'll add $50 FREE from our side.
That's $100 in total.
At just $0.36/GPU-hr, that's 277+ hours of RTX 5090 compute - over 11 days of non-stop GPU power.
More compute. More experiments. More possibilities.
👉Deploy now: dash.packet.ai/account?gpu=n…
#RTX5090 #GPUCloud #AICompute

1
19
Token Factory is live, and it's serverless. No pods to spin up, no GPUs to manage, no idle bills. Just an API key and a prompt.
Head to the Serverless section in your dashboard, verify your phone number, and you're running in under a minute. Three models are ready behind one OpenAI-compatible endpoint:
DeepSeek-V4.1-Flash
MiniMax-M3.1-Flash
Qwen2.5-1.5B-Instruct
🎁 And this month it's on us. Usage is free - build something real, test it hard, and ship it. Nothing to install, nothing charged by surprise.
🚀 Serverless inference, zero setup, free to start. Open Serverless and send your first prompt.
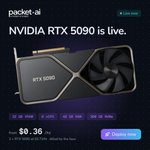
NVIDIA RTX 5090 is live on packet.ai.
32 GB VRAM per GPU · 6 vCPU · 48 GB RAM · 300 GB NVMe. Dynamic allocation, billed by the hour.
1 × RTX 5090: $0.36/hr
2 × RTX 5090: $0.72/hr
Deploy now: dash.packet.ai/account?gpu=n…

1
152
🔥 Thursday's GPU Take
Before buying a bigger GPU for inference, test whether quantization could get the job done on your current hardware.
Lower memory requirements can change the economics, but model quality and serving performance still need to hold up.
Would you test quantization before upgrading?
23
Got H100s?
Good. Now, what kind?
SXM, PCIe and NVL are not interchangeable. Neither are the systems they're built into.
Know before you list.
packet.ai/blog/got-h100s-wha…
🤖 Made with AI

16
Your Black Friday GPU deal just got bigger.
Run NVIDIA B200 at $3.75/GPU-hr and get an extra $50 in credits in your wallet.
Here's the deal:
💰 Top up $100 → Get $50 FREE in your wallet
🚀 Deploy B200 or any other gpu by the hour based on your workload.
Scale when you need it. No long-term commitment.
Just powerful Blackwell GPUs at a compelling rate.
Don't let this Black Friday opportunity pass you by.
👉 Get started: dash.packet.ai/
Limited-time offer. Minimum $100 top-up (One-time only).
#BlackFriday #NVIDIAB200 #GPUCloud #AIInfrastructure #PacketAI #Blackwell

1
37
💸 GPU Bill Rescue
You move a workload from one GPU to two.
Runtime drops by just 10%, but GPU spend nearly doubles.
What would you investigate before deciding whether the second GPU is worth it?
11
Buying the GPU is the straightforward part.
Pricing it right, keeping it online, meeting verification requirements and making the economics work? That's where new GPU hosts get caught out.
7 operational mistakes worth avoiding: packet.ai/blog/gpu-hosting-m…
🤖 Made with AI

16
🧭 Tuesday's GPU Choice
Your model needs more than 48GB of VRAM but fits on one 96GB GPU.
Would you use one larger GPU or split the workload across two 48GB GPUs?
Which would you test first, and why?
35
Before connecting your GPUs to a hosting platform, ask what you're giving it access to.
Your machines, your network, your data, your liability.
We've put together 12 questions GPU providers should ask before listing their capacity.
packet.ai/blog/gpu-provider-…
🤖 Made with AI

21
38 providers were already listing B300 capacity on one tracker by October 28.
The early-mover window is getting smaller. Buyers can compare providers, prices and availability.
Owning the GPUs is one thing. Having the infrastructure to put them to work is another.
What B300 providers need to know: packet.ai/blog/got-b300-why-…
🤖 Made with AI

46
🔥 Thursday's GPU Take
A GPU that wins your benchmark can still lose you money in production.
A benchmark might reward peak throughput. Your production workload might be constrained by latency, concurrency, memory pressure or the cost of completing each job.
Winning the benchmark and winning in production aren't necessarily the same thing.
14
Got H200s? The real question is who needs that memory, and what they'll pay for it.
H200 vs H100, rental prices, and where inference demand is heading:
packet.ai/blog/got-h200s-whe…

19
💸 GPU Bill Rescue
Your expensive GPU spends a significant amount of time waiting for data from the CPU or storage.
The team wants to upgrade to a faster GPU.
Would you make the switch, or investigate the bottleneck first?
What's your take?
14
Installed the GPUs. Collected the payment. End of story?
Not necessarily. MSPs and integrators have several ways to build a revenue stream beyond the initial sale. The right model depends on what they're willing to own.
packet.ai/blog/how-msps-and-…

9
🧭 Tuesday's GPU Choice
Two GPUs look suitable for your workload.
One has slightly stronger specs. The other has mature support for your framework and libraries.
Which would you test first, and why?
Hint: Hardware is only part of the decision.
15
A GPU can be good collateral and still be a repayment risk.
For lenders, the key isn't just whether a GPU is busy. It's whether that activity generates billable revenue, and whether the contracts can sustain repayment.
What to monitor, what to ask, and where idle capacity matters:
packet.ai/blog/gpu-financing…

12
NVIDIA A100 PCIe at $0.89/hr. NVIDIA B200 at $3.75/hr.
Both live on packet•ai. Dynamic or Dedicated. No contracts, billed by the hour.
dash.packet.ai/compute?utm_s…

ALT packet.ai launch graphic: NVIDIA A100 PCIe from $0.89/hr and B200 from $3.75/hr, both live, on-demand and dedicated.
16