

Get structured data feeds from any website through our cloud-based data extraction platform. Check out our products @JobsPikr @DataStockS @42_signals
Lewes, Delaware
Joined November 2010
- Tweets8.8K
- Following358
- Followers1.8K
- Likes1.8K




The demo works in a week. Three sites, clean data, meeting concludes this is straightforward.
Correct, and irrelevant. Building was never the expensive part, year two is.

Compare the true long-term costs of building versus buying web scraping infrastructure with PromptCloud’s build-vs-buy calculator: shorturl.at/2DnCc

70% of the web had a rough Wednesday.
Sites went offline worldwide to patch PHP2Shell. Your scraper saved "We'll be back soon!" as a product title and logged it as 200 OK.
Patch your servers. Then check your data supply.
Link in the replies.
#PHP2Shell #DataForAI

See how PromptCloud helps maintain reliable, high-quality data pipelines for AI: shorturl.at/HVdgh

Compliant collection is four decisions.
What is the purpose, stated narrowly. What is the permission basis per source. What happens when a control is hit, which should be stop. What trail is attached per record.
Public availability is not a basis.

Explore PromptCloud’s approach to compliance and data governance: l1nq.com/iew8xbm

Happy Dussehra to everyone!
The shelf does not take the day off, which is rather the point of the festival if you squint at it. Back to the data tomorrow.

If collection were banned tomorrow: price comparison dies in a week, salary benchmarking follows, and academic research takes the quietest hit and the longest to notice.
Search engines are built on the exact mechanism being argued about. That part never makes the argument.

Responsible data collection also means making scraping pipelines easier to maintain: shorturl.at/DxdwX
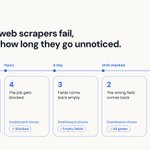
Crashes are cheap. Blocks are cheap. You find out immediately.
The expensive one is a job that silently stops covering a subset of pages. Volume looks normal. Totals look normal. A whole category quietly leaves your analysis.

A closer look at why web scrapers fail in production and how to catch silent data quality issues: shorturl.at/i74Aq


The part of in-house collection that never makes it into a budget is silent failure.
A run that breaks at 2am and alerts nobody does not appear as a cost. It appears six weeks later as a decision made on stale data.

Run your own numbers in our cost calculator: shorturl.at/AA8Cr
Most collected websites, 2026: TikTok, Google, ChatGPT, Naver, Perplexity, Make.com, Target, Amazon, GitHub, Stack Overflow.
Three survive from last year.
Teams stopped asking what people search for. They are asking what the answer engines say back.

AI platforms are changing what data matters: shorturl.at/geNwL

