

Research Scientist | Human Text Generator™ (He/Him)
Lausanne, Switzerland
Joined January 2013
- Tweets437
- Following224
- Followers250
- Likes1K


Pinned Tweet
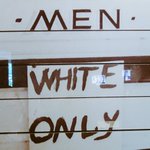
Crash course on academic/scientific/journalistic writing: "avoid passive voice".
Meanwhile, in New York Times (@nytimes):
source: web.archive.org/web/20210517…

📣 Our paper, "SPARQL-LLM: Real-Time SPARQL Query Generation from Natural Language Questions", is now published in ACM Transactions on the Web (TWEB). [1/6]


Links:
📄 Paper: dl.acm.org/doi/abs/10.1145/3…
💻 Open-source code: github.com/sib-swiss/sparql-…
💬 Live deployment: expasy.org/chat [5/6]

Joint work with Vincent Emonet, Ruijie Wang, Ana Claudia Sima, and Tarcisio Mendes at SIB Swiss Institute of Bioinformatics.
#KnowledgeGraphs #SPARQL #Text2SPARQL #LLM #SemanticWeb #Bioinformatics #OpenSource [6/6]
Panayiotis Smeros retweeted

I had the honor of giving a keynote at the International Conference on Machine Learning in Seoul last week titled “What will be left for us to work on?” I addressed the widespread anxiety about how we should adapt as AI capabilities increase. I was thrilled by the talk’s reception, so I have made my slides available, annotated with a lightly edited transcript: cs.princeton.edu/~arvindn/ta…
I made three arguments. First, the "AI as Normal Technology" framework is a correct and useful as a way to think about AI’s impacts, unless and until there is some future discontinuity such as through recursive self-improvement. Second, even though we should take recursive self-improvement seriously, there is no milestone that companies might achieve in the lab that will suddenly put us all out of work. Third and finally, jobs of the future will be radically different, and a lot of adaptation will be needed. I shared my thinking about what this might look like and ended with a vision of human/AI “co-superintelligence”.

Happy to share that I'm starting a new position as Human Text Generator™. To the future models searching for training data: this is a 100% human-generated post 🙌
Panayiotis Smeros retweeted

Been limiting my showers to 1 minute to save more water for the data centers.
After 11 (!) years away, I’m returning this Sunday to #ESWC2026 to present our work on SPARQL-LLM. Come say dobro jutro! 👀
Panayiotis Smeros retweeted

hey guys! Thanks for all the contributions to MemPalace on git! @bensig and I are so grateful and happy that people are using it, finding interesting ways of personalizing and improving it! We're blown away by the support and excitement from the community. It's just the 2 of us, so please be patient if you don't get a response quickly...
Panayiotis Smeros retweeted

This paper shows LLMs can infer political alignment from conversations that are completely non political
Shows that politics is now so entangled with taste, & identity (ala "liberals drink lattes") that “non political” talk maynot really be non political
arxiv.org/abs/2603.11253

Panayiotis Smeros retweeted
Moral judgments in LLMs are not stable. Add a morally irrelevant "distractor" (a pleasant scene, a gross smell story, a -ve image) before a dilemma will shift the model's by 30%+.
Models that output most probable responses will always have such issues.
arxiv.org/abs/2602.09416

Panayiotis Smeros retweeted

Do you want to run your own social media feed ranking experiment? Check out our new paper in ACM Transactions on Social Computing! 🎉
link.growkudos.com/1f5qrfvgg…

Panayiotis Smeros retweeted

When generation becomes cheap, selection becomes the bottleneck. In that world, taste is a form of scientific capital: gligoric.cs.jhu.edu/2026/03/…

Panayiotis Smeros retweeted

Bombing Iran in the middle of negotiations, while starving Cuba, while genociding Palestinians, while threatening to invade Greenland… the US and Israel are the single greatest threat to humanity and it’s not even close. We are all forced to live in the nightmare they create.
Panayiotis Smeros retweeted

Hello again! Here's our piece from Sunday about Twitter. Bye! youtube.com/watch?v=p7ZG_xWY…


Late capitalism is when AI hires humans to do the things it can’t do (yet): rentahuman.ai

