

RL Environments and Coding @joinhandshake | led embedded ml @noco
San Francisco, CA
Joined November 2019
- Tweets959
- Following988
- Followers821
- Likes3.6K




Pinned Tweet
Presenting Jeve (pronounced jeev - sanskrit word for life)
A simulation engine mostly powered by Jev from @typesafeai
Jeve is significantly more efficient (cost and time) compared to LLM-based GABMs and is a solid framework for long-running simulations
Live demo coming soon
I am excited for a world where knowledge and intelligence is more accessible globally
Frontier models have been only truly accessible to a very small fraction of the population until now IMO


Punit Arani retweeted

We are releasing Ultramarine 1 Flash, a frontier-class model built for knowledge work. It is open-source and achieves similar performance to Fable 5, while being 60x cheaper.
It was post-trained by a team of 5 for ~$300k all-in. Available on API now, with weights releasing in 2 weeks.
Inference is largely underdiscussed in the post-training space
You can post-train all the models you want, but most can’t efficiently serve
GPU scarcity and inference efficiency are real problems
has anyone looked into why xhigh-max reasoning effort for frontier models perform worse
one reasoning pattern i've been noticing across models is to use
- high on large models (opus/sol)
- xhigh on medium (sonnet/terra)
- max on small (haiku/luna)


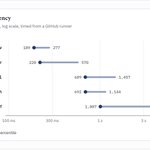
Benchmarked 7 Decision APIs vs 4 LLMs
Decision APIs are
just as accurate
2-7× faster
but not much cheaper
Tips
1. Batch questions that share context
2. Temperature-scale the probabilities
3. Use LLM if you need reasoning


Jev is the best all-rounder Decision API, with @perplexity_ai Decider and @OpenAI GPT 6 Decisions in second depending on use-case
@deepseek_ai V4.1 Flash is the best LLM alternative
Claude Projects is singlehandedly the best UX for getting work done
- threads
- filesystem
- repos
- memory and shared context
- cloud environments
- works on mobile, desktop, and web
DeepSeek V4.1 Flash is such an underrated model
Especially for non-coding tasks that requires intelligence, speed and efficiency
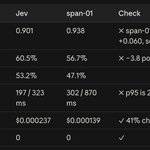
Was trying out @typesafeai Jev vs @RespanAI Span-01 and found
1. Span-01 performs slightly worse than Jev
2. Jev is 2x faster
3. Span-01 is over 40% cheaper
Span-01 was also harder to integrate while missing some types and features
Excited to try out @OpenAI Decisions API soon

BERT would be proud

Introducing Span-01, the first hyper-parallel reasoning classifier built for unseen challenges (RLAIF).
2x cheaper, 18% better than Jev.
700x cheaper, 4% better than GPT-6 Luna.
Frontier reasoning for every behavior, at classifier speed.
• Span-01: #1 on Behavior Benchmark
• Span-01 Lite: Better than Jev and completely free!

