

Head of Engineering for Pexels at Canva. Ex Google. Writes about AI, coding, management, tech, business, and geeky stuff.
London, UK
Joined September 2008
- Tweets835
- Following262
- Followers3.7K
- Likes247



Understanding is one of the greatest pleasures in life. At least for me (whether it's my vLLM experiments or watching some all Smarter Every Day episodes).
35
Even though priority doesn't affect how each step is constructed in vllm (AFAIK), it does affect which request gets preempted when there's KV pressure.

1
1
59
I just published a blog post about by first week of learning vLLM, the experiments, the charts, what I learned, it's all here: pablofernandez.tech/2026/11/…
58
Given a constant stream of higher priority requests, in vllm, the lower priority one could have to wait for a long time. I wonder if this is what "batch" is when using the OpenAI and other APIs like that, that have interactive and batch (there's probably more to it than that).

1
41
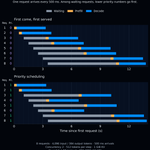
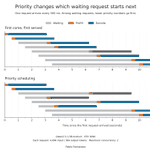
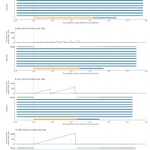
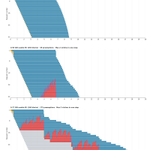
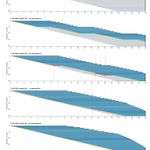
Today I learned about vLLM priority for requests. It does affect which request gets picked up next (first chart), but doesn't affect how the scheduler chooses which tokens to run in each step (second chart).


2
2
136
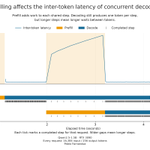
On today's lesson I was learning the effects of different max token budgets per step in vLLM to time to first token and inter-token latency. In the first chart you can see how prefill takes longer if you want to keep time between tokens down and vice-versa.


3
1
342
I'm appalled by the new trend of putting USB-C sockets on devices without implement USB-C, so only a USB-A to C cable works, a USB-C to USB-C doesn't. And there's no way to tell before you purchase these devices. Really annoying.
1
56
I'm starting to understand why you might want to disaggregate prefilling and decoding for LLMs. Prefilling almost feels like a batch process and decoding like an interactive process. One cares about throughput, one cares about latency. Prefilling can mess up latency.


1
1
110
I wanted to chart the impact of preempting requests in vllm when we have a lot of prefix sharing (think production workload with the same prompt repeated). Hitting the limit of the KV cache can cause a cascade of preemptions.


4
70
Continuing to build my intuition for inference engineering: what happens when you vary KV cache capacity while keeping everything else fixed? These charts show a synthetic workload.
What surprised me was the lack of preemptions with the smallest caches.


3
1
76
Requests spent longer waiting because the scheduler couldn’t allocate enough KV space to admit them.
With a little more capacity, more requests could start, but as their histories grew during generation, some needed to be preempted.
1
28
Now working on developing an intuition of prefix caching on (KV) in vLLM with Qwen2.5. This is working at the single request/conversation level, so the proper compromises of VRAM vs GPU is not completely apparent yet (prefix caching on has no consequences).


I wanted to develop an intuition of the impact of KV caching with vLLM. I think it's so fundamental we can't call it an optimization anymore. I had to add a scheduler extension to discard the KV cache after each pass to disable it, that's how fundamental it is.


2
1
69
I’ve started digging into vLLM and I wanted to build an intuition about the behavior of the scheduler. I got more excited than I expected with this. I plotted request while increasing concurrency from 1 to 512, serving Qwen2.5-1.5B-Instruct to see how limits affect metrics.

2
3
90
New personal rule: these get labeled when taken out of the box, immediately. I have no idea what most of these are or were for.

1
34