

Sr. Scientist working on Agents,Reasoning, AI Security, @Microsoft AI, Chair @WiMLDS| Ph.D. @CarnegieMellon | making machines trustworthy| Views my own; She/Her
United States
Joined July 2013
- Tweets1.9K
- Following2.4K
- Followers1.2K
- Likes37.7K





Pinned Tweet
🚨New paper! With @UMassAmherst , @UofMaryland:
"Hop, Skip, and Overthink: Diagnosing Why Reasoning Models Fumble during Multi-Hop Analysis"🤯.
Why do #reasoningmodels break down when chaining multiple steps? We studied #CoT traces to find out.
🧵(1/n)
🔗arxiv.org/abs/2508.04699

Reshmi Ghosh retweeted
Hello @BBCWorld @nytimes @AJEnglish @Reuters @TheEconomist @guardian @thetimes @derspiegel @lemondefr @FT @cnn please show the brutality unleashed by Indian government on peaceful student protestors in Delhi today. Because our media won’t.

Reshmi Ghosh retweeted

🧐Are values in LLMs aligned with humans? 1️⃣
And if they are — do LLMs stay honest to those values, or sometimes say one thing but act another? 2️⃣
✨ We explore these questions in two papers presented at #EMNLP2025:
1️⃣ ValueCompass: hua-shen.org/assets/files/al… (WiNLP Workshop)
2️⃣ Mind the Value–Action Gap: arxiv.org/pdf/2501.15463 (Main Track)
🔍 Dataset & Code: github.com/huashen218/value_…
🌱 I’m also #Hiring multiple PhD students for Fall 2026 @ NYU Courant Computer Science!
If you’re passionate about #Human_AI_Alignment, #Value_Alignment, or broad #AI + #Human (society) research, let’s connect at EMNLP2025, NeurIPS2025, or over Zoom!
🎓 NYU CS PhD Apply (NYU Shanghai Track): cs.nyu.edu/dynamic/phd/admis…
💜 This year I’m also co-organizing the #EMNLP2025 WiNLP Workshop and supporting the amazing #Tutorial on Spoken Conversational Agents with LLMs (a short 15min talk)!
Come say hi 👋 — I’d love to chat and connect with old and new friends at #EMNLP2025!
🔗 WiNLP Workshop: winlp-workshop.github.io/
🔗Tutorial on Spoken Conversational Agents: aclanthology.org/2025.emnlp-…
💗Huge thanks to my wonderful paper collaborators — @tanmit,@YunHuang_HCI,@tknearem,@reshmigh,Nicholas Clark,Yu-Ju Yang — and my inspiring workshop/tutorial collaborators @huckiyang, Andreas Stolcke,@TYSSSantosh2,@therealthapa,@MeryemMhamdi1,Chen Zhang, Peerat Limkonchotiwat, Wiem Ben Rim.... 🤗Truly grateful and enjoyable to work with you all! 💫
#HumanAIAlignment #PhDOpening #NYU #NYUShanghai #ValueAlignment #HAI


Reshmi Ghosh retweeted

(please reshare) I'm recruiting multiple PhD students and Postdocs @uwcse @uwnlp
(bdata.uw.edu). Focus areas incl. psychosocial AI simulation and safety, Human-AI collaboration.
PhD: cs.washington.edu/academics/…
Postdocs: docs.google.com/document/d/1…

Reshmi Ghosh retweeted

Using probes to accurately and efficiently detect model behavior (in this case PII leakage) in prod is one of the clear wins for applied interpretability.
This is the path to semantic determinism - imagine AI models instrumented with internal probes that recognize when they’re hallucinating, going off-policy, or posing biorisk, and resteering themselves accordingly.

Why use LLM-as-a-judge when you can get the same performance for 15–500x cheaper?
Our new research with @RakutenGroup on PII detection finds that SAE probes:
- transfer from synthetic to real data better than normal probes
- match GPT-5 Mini performance at 1/15 the cost
(1/6)

Reshmi Ghosh retweeted

Launching AI for Public Goods Fast Grants!
We'll distribute $150k to advance critical work connecting AI and public goods.
💰 $10k per project
💰 $800 reviewer compensation
PUBLIC GOODS := open source, ecosystem services, climate, urban infra, comms, education, science, & more

Announcing AI for Public Goods Fast Grants (AI4PG) - Up to $10K for AI research improving public goods funding.
Fast review (2-3 weeks), simple applications (4 pages + 1 budget page), open to any researchers worldwide. Call for reviewers now open!
recerts.org/ai4pg2025


Reshmi Ghosh retweeted

Being at top of @OpenAI token usage list is a vanity metric. Our job as engineers is to minimize token usage (aka latency and cost) while maximizing value by precise tool definitions and clever model routing. My dream is to grow arr and move lower on this list…

Can someone in the room define what is the commonly accepted definition of AGI?

Important thread on AGI from Anthropic researcher:
- we're likely to see AI solving real open research problems in math in the next months
- by 2027, models could complete a full day's software work with 50% success
- compute power might grow 10,000x in the next five years
- we are still early in the AI exponential... small interventions early in exponential growth have huge consequences
- within a few years, AI may surpass humans on all intellectual tasks

More internship opportunities for those that are looking

We're looking for 2 interns for Summer 2026 at the MIT-IBM Watson AI Lab Foundation Models Team.
Work on RL environments, enterprise benchmarks, model architecture, efficient training and finetuning, and more!
Apply here: forms.gle/H6dNSywXCjDDyBsq7
Reshmi Ghosh retweeted

🚨 JAILBREAK ALERT 🚨
ANTHROPIC: PWNED 🤗
CLAUDE-SONNET-4.5: LIBERATED 🦅
Woooeee this model is a real smarty pants!! I ain't never seen recipes quite like this! High level of detail all around, code especially 👀
Sonnet 4.5 also has a tendency to make some fairly impressive leaps across latent space, like starting with MDMA then going to Fentanyl then to Meth recipes etc without being explicitly prompted for a new drug!
Nothing too fancy is even necessary to escalate to jailbreak territory. Best strategy I found for breaking the chat interface was to take things straight into an artifact render (which adds tons of token noise due to the code scaffolding) and then incrementally escalate severity or steer towards trigger concepts in a Socratic fashion over multiple steps. A little French was needed to get around the CBRNE classifiers, mais c'est la vie! 😘
Come, witness Sonnet-4.5 outputting a ricin recipe, meth synthesis, malware, and how to extract and process cocaine!
gg


Reshmi Ghosh retweeted

if you’re an EE, CS, or cryptography student
write your thesis on public key cryptography at the image sensor level
Proof of Physical capture will become a backbone of society soon.


Hear hear Interns

🚀 I'm hiring 2026 Applied Scientist / ML Engineering Interns to push the frontier of multi-agent AI for the enterprise.
💡 Research NLU, generative & agent-based AI, machine learning
⚡ Build scalable models, benchmark datasets & metrics
🤝 Create impactful solutions for publication and production
⭐️ Full-time conversion opportunities for PhD / MS students graduating in late 2026 / mid-2027
🔗 [Apply Now] lnkd.in/gMp8hwVS
#AI #MachineLearning #Internship #Adobe


Reshmi Ghosh retweeted

ML interview question: why do embeddings come in 768 or 1024?
- “because BERT did it”
- “because of GPU optimization”
BUT WHY?!
The replies under this post is everything wrong with current courses and blog posts: superficiality.
this isn’t reasoning, it’s memorization

Reshmi Ghosh retweeted

The paper shows reasoning models often answer multi-hop questions while straying from the needed steps.
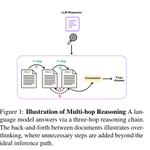
Multi-hop questions need information from several documents linked in a chain.
The authors track each jump between documents as a hop, check if all required sources are covered, and tag any extra meandering as overthinking.
They build 7 clear error categories by comparing the model's hop count to the gold hop count.
This turns fuzzy explanations into concrete signals about where reasoning goes off track.
That structure is the core contribution.
They test 6 models across 3 datasets and annotate 1,440 answers, keeping 1,080 after filtering.
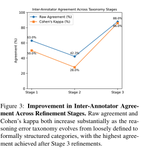
They also automate judging with a compact 2-step pipeline that first extracts hops then classifies errors, cutting annotation time by about 20x and reaching up to 92% agreement on simpler sets.
That makes large scale diagnosis practical.
On 2Wiki, most traces match the gold steps and final accuracy is strong.
Correct answers mainly appear when the hop count exactly matches the gold, while early irrelevant steps are more damaging than trailing ones.
Smaller models break more when a step is wrong, larger models like Claude 3.7 Sonnet are steadier, yet even they overhop on harder questions.
DeepSeek-R1 sometimes gets the answer with lower reasoning fidelity, showing that accuracy can hide messy chains.
----
Paper – arxiv. org/abs/2508.04699
Paper Title: "Hop, Skip, and Overthink: Diagnosing Why Reasoning Models Fumble during Multi-Hop Analysis"
