






DeepSeek V4.1 Flash Orca, now packed for Sushi by @Beamsters1 🍣
Tested on a 48GB Mac.
Tiny refusal pilot: both judges marked 9/12 answers as fulfilled. Orca used 512 output tokens; comparators used 256. Full results and caveats in the model card—not a full benchmark.
huggingface.co/sanasol2008/D…

37
DeepSeek V4.1 Flash Heretic, packed for Sushi by @Beamsters1 🍣
Tested on a 48GB Mac: 5–7 tok/s xD
Tiny refusal pilot: judges marked 8–11/12 Heretic answers as fulfilled vs 0/12 for stock DS FLASH Maya/DS FLASH API. Caveats in the model card — not a full benchmark.
huggingface.co/sanasol2008/D…

1
63
one RTX 5090, two RTX 3090s, a Ryzen 9 9950X
Qwen3.8-Flash-Next IQ3_S (SC117 abliterated GGUF) on Strata
DeepSeek-V4.1-Flash Maya-XS on Project Maya

162
One copy of the experts in RAM, three engines on it: RTX 5090 + two 3090s (one on OCuLink x4) all serve Qwen3.8-Flash-Next from a 50 GB shared arena. 4 streams, 371-392 t/s aggregate, 512K context on the 5090. Gotcha: /dev/shm quota kills it silently at 36 GiB.
1
33
Our two used Chinese RTX 3090s screamed 24/7 — 3300 RPM even at idle, even at 16 W. We couldn't flash a fix: Ampere rejects edited VBIOS. Now they idle at 0 RPM, and the flash chip was never touched. Thread on the trick nobody tells you about 🧵

1
97
For the brave: Ampere fan tables live beyond the 512K ROM window (full PROM read via BAR0+0x300000, driver unbound). The min_* fields are read-only in editors → hand-patch u16s, fix the additive checksum, normalize to ampere-relocated-v1 (512K GSP cap).
1
79
Full reproducible recipe, offsets, deploy pitfalls and the exact payload for this card → github.com/sanasol/3090-fans… If your used 3090 howls at idle, it's one patched image + one reboot. No soldering iron, no CH341A, no brick.

13
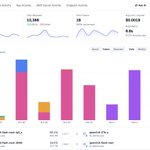
My first local 1B tokens, took 1 week of relaxed work
Qwen3.8 Flash Next and Qwen3.8 27b (retired now)

22
